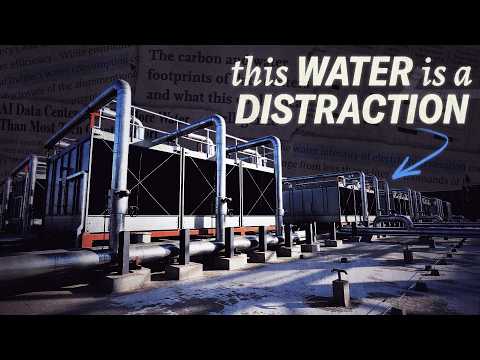
AI infrastructure is growing fast, but there is another side of AI that we need to discuss: electricity, cooling and water consumption.
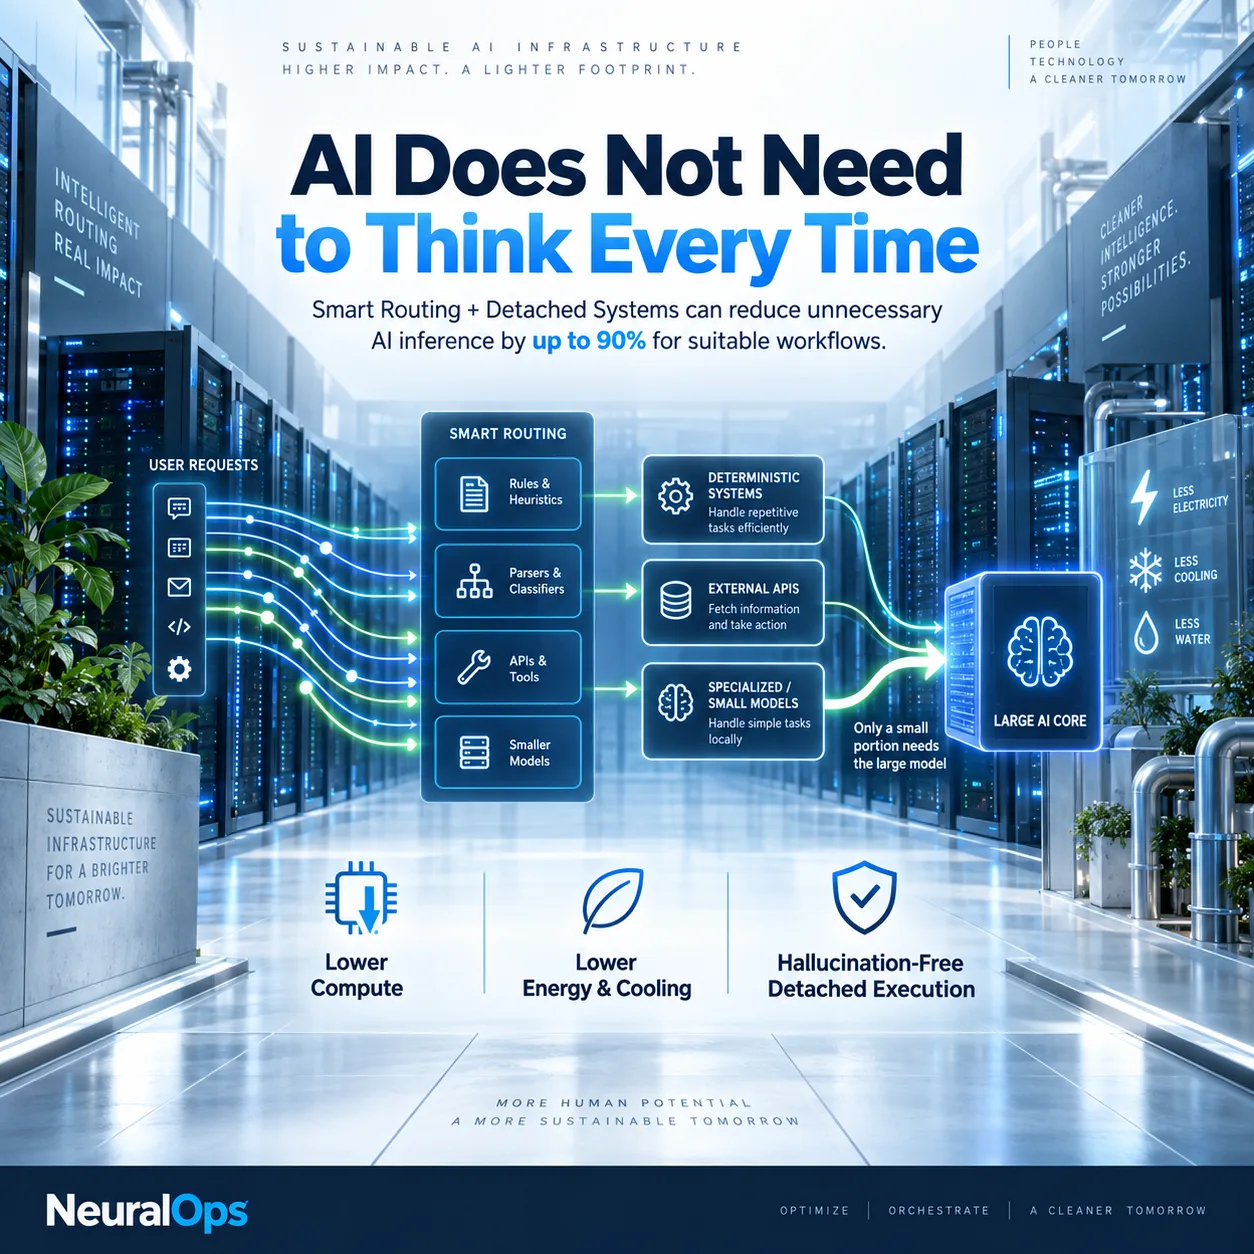
Recent research shows that once an AI model is deployed, inference can account for around 80–90% of its energy consumption. Every unnecessary LLM call means more GPU compute, more electricity, more heat, and ultimately more cooling demand.
This is one of the reasons we are developing NeuralOps around a different principle:
Not every task needs an LLM.
With 智能路由, a task can first be handled by rules, parsers, databases, APIs or smaller models. 重型 LLM reasoning is only used when it is genuinely required. Once a workflow becomes stable, it can be converted into a detached deterministic 系统 that executes repeatedly without calling an LLM.
For suitable repetitive 工作流, this architecture can potentially reduce AI inference demand by up to 90%.
The impact goes beyond token savings.
Less inference → Less GPU compute → Less electricity → Less heat → Less cooling → 更低 water demand.
There is another benefit: reliability.
时间 a detached workflow no longer depends on an LLM during execution, there are zero LLM 令牌 and zero LLM hallucinations during that execution path. The intelligence is used where reasoning 是必需的, while deterministic 系统 handle repeatable operations.
I believe sustainable AI will not only come from building more efficient data centres.
It will also come from preventing unnecessary AI inference from reaching the data centre in the first place.
That is the direction we are exploring with NeuralOps:
use AI when intelligence is required, and use deterministic 系统 when intelligence is not.
#Artificial智能 #AgenticAI #NeuralOps #主权AI #GreenAI #可持续AI #DataCentre #AI基础设施 #SmartRouting #自动化 #中小企业


Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
关于重型 LLM reasoning的例子很实用,适合团队继续讨论。
我喜欢文章对时间 a detached workflow保持务实的态度。
总结部分让recent research shows that once的重点更加清楚。
第一次看到有人把这段说明讲得这么坦白。
关于这篇文章这部分写得很扎实,整体也站得住。
文章对every unnecessary LLM call means提供了很好的起点,值得继续跟进。
文章把once a workflow becomes stable和日常运营联系起来,这一点很有帮助。
收藏了,主要是为了use AI when intelligence。