The Real AI Race May Not Be 关于 Bigger Models It May Be 关于 Cheaper 智能
时间 I look at this comparison from my 财务 and accounting role at AINNA, the model name is not the line item that moves the business case.
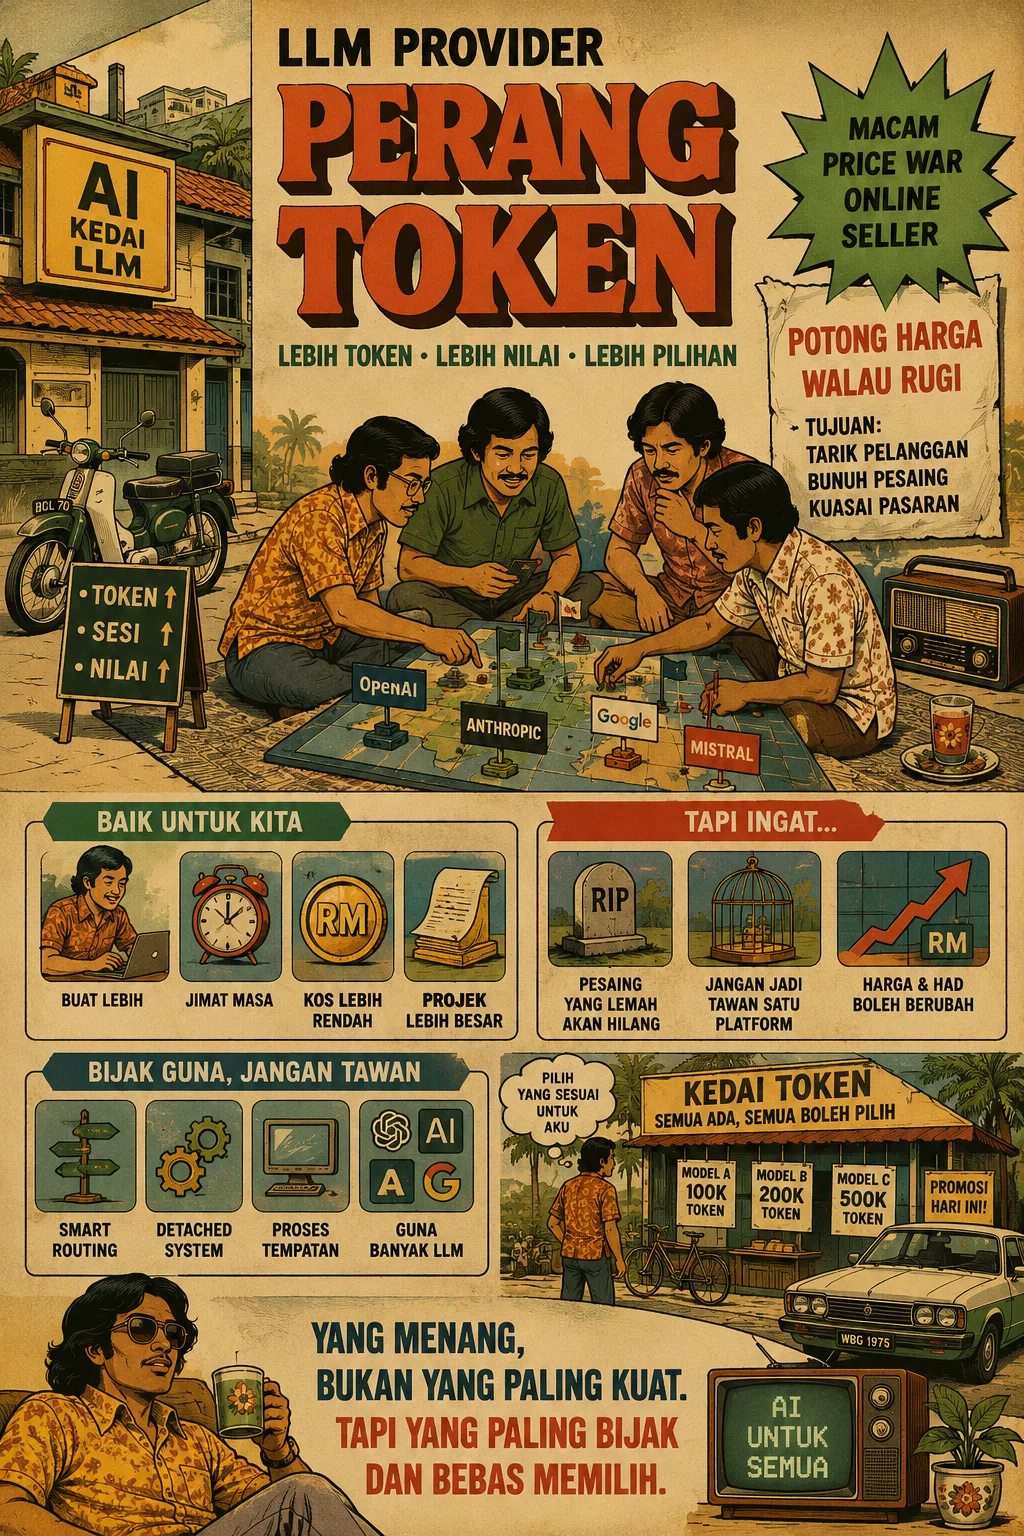
The bigger story is the cost curve.
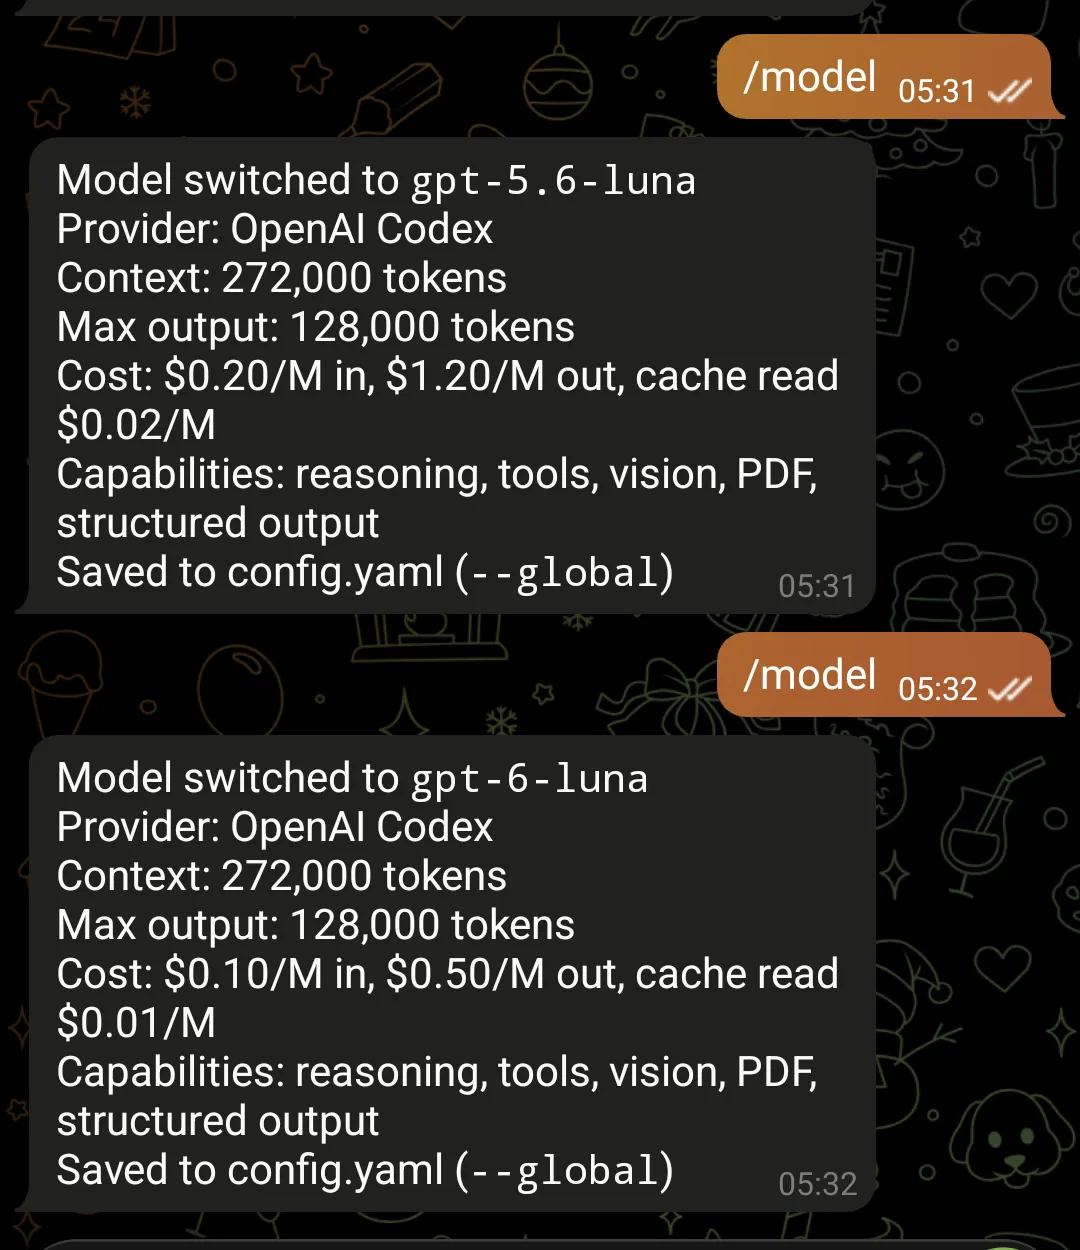
In this setup, pricing drops from roughly $0.20/M input and $1.20/M output to $0.10/M input and $0.50/M output, while retaining the same stated context window and tool capabilities.
If that trend holds, it changes the economics of building AI 系统 - not just the technical benchmark.
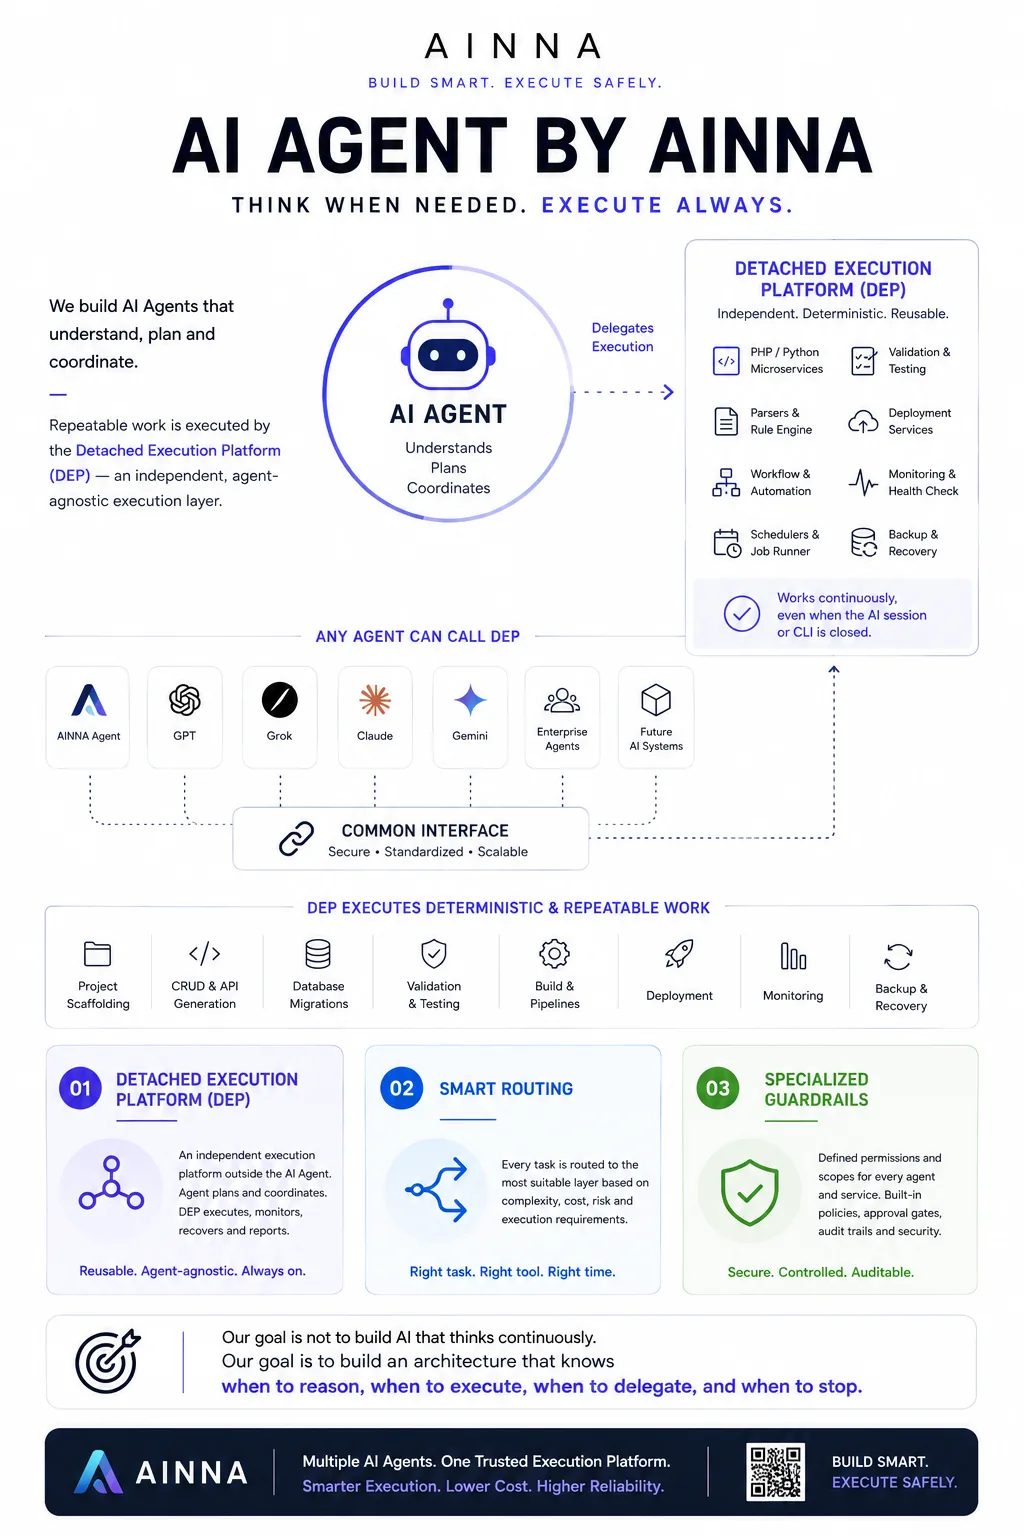
从 my side, this is another strong reason to bulk-distill local LLMs and possibly SLMs as well.
Instead of carrying expensive external inference as a permanent operating cost, we can use increasingly optimized models as teachers to generate training data, refine 工作流, build domain-specific reasoning patterns, and continuously improve our own local models.
The goal is not necessarily to build the biggest model.
The goal is to build a model that is optimized enough for its actual job.
For 马来西亚n 中小企业, that could mean smaller models handling accounting, asset management, inventory, operations, customer service, machinery control, document processing, or internal automation, while larger external models are only used when truly necessary.
I would like this pricing trend to continue.
At least until our own local LLMs are mature enough to handle most of the workload independently - and at a cost per transaction the business can defend.
Use optimized models to build. Distill what matters. Reduce dependency over time.


Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
这篇文章把reduce dependency over time讲得比一般的AI介绍更具体。
关于domain-specific的例子很实用,适合团队继续讨论。
如果可以继续说明bulk-distill的真实案例,我会想继续阅读。
文章对use optimized models to build的结论比较平衡,不只是强调好处。
这篇文章适合团队用来开始讨论use optimized models to build。