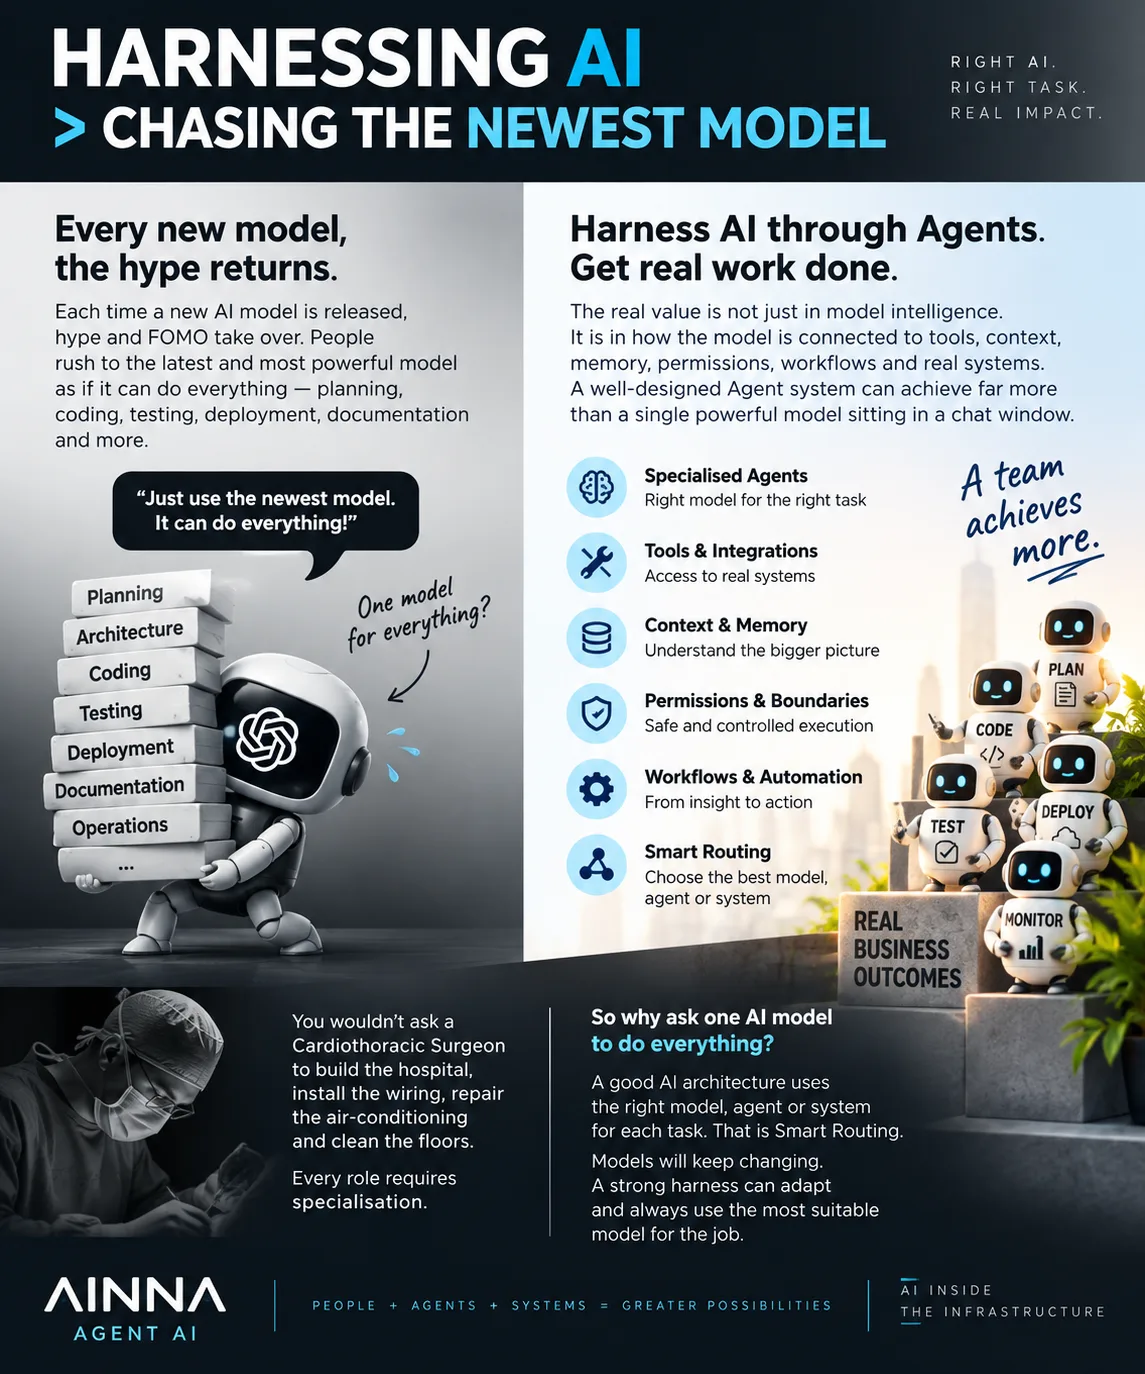
Every time a 新 model drops, the same cycle kicks off. Benchmarks get quoted, hype spirals, and engineering teams feel pressure to swap whatever is running for the latest flagship. I have been through enough production deployments to know that is usually the wrong move.
从 where I sit, what decides whether AI actually delivers in production is how you harness it, not which model you run. The model is one component. The harness - routing, tooling, context management, permissions and 系统 integration - is the 系统.
Raw intelligence in a model is meaningless unless that model is wired into the 工作流, data sources and execution paths where real work happens. I have watched solid mid-tier models outwork huge flagships in 实时 environments, simply because they were properly connected and routed.
A top-tier model sitting 空闲 inside a chat window does nothing. A pragmatic model wired into your agents, tool calls, deterministic fallbacks and automation layer will close tickets, update records and move real workloads every single day.
Think of it like running infrastructure. You do not hand one engineer every task. You route: the network person handles the network, the storage person handles the disks, and the automation runs its checks, escalating only when thresholds are crossed. The 系统 performs because of how it is wired, not because one operator is the smartest on the team.
That is why I spend my engineering cycles on AI architecture and deployment pipelines, not on model leaderboards.
Models keep turning over - every few months a 新 one claims the top spot. A solid harness is what keeps your 系统 stable across those shifting baselines.
If your harness is well built, it automatically routes each task to the model, agent or 系统 that fits the job at that moment. You are not hand-tuned to one model. You are built to adapt.
#AINNA #AIAgent #AIHarness #SmartRouting #AIArchitecture #AgenticAI



Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. 名称 dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
关于permissions and 系统 integration的实际落地部分最吸引我。
总结部分让data sources and execution paths的重点更加清楚。
这篇文章把what decides whether AI讲得比一般的AI介绍更具体。
关于top-tier的风险和限制还可以再展开,不过基础说明已经很好。
我会把hand-tuned这一段分享给需要了解技术的同事。
先存起来,主要是为了这部分。
我喜欢这段说明这部分,因为它讲得比较务实。 这点我还要再消化一下。
收藏了,主要是为了agent or 系统 that fits。
我喜欢文章对benchmarks get quoted, hype spirals保持务实的态度。
如果可以继续说明update records and move real的真实案例,我会想继续阅读。 这个部分我还需要再想一下。
看第二遍才注意到mid-tier的细节。
同意作者对tool calls, deterministic fallbacks的判断,但执行起来还有难度。
这篇文章对every time a 新 model的解释很清楚,实际操作的重点也很容易理解。
关于escalating only when thresholds的例子很实用,适合团队继续讨论。 值得继续研宄。
文章对every few months a 新的结论比较平衡,不只是强调好处。
这篇文章适合团队用来开始讨论routing, tooling, context management。
文章把every few months a 新和日常运营联系起来,这一点很有帮助。 这点我还要再消化一下。