If your AI team is maxing out premium-model quotas before day seven, that's not just a token problem.
It's a unit economics and architecture problem.
You probably need to rethink your model-routing strategy.
In my own stack, ChatGPT Pro + Ollama is the most practical combination. I push Luna and DeepSeek V4.1 hard for development, distillation, and detached-系统 builds-while the higher-tier models mostly come in for final audit, validation, and direction.
In one month, I shipped 25 detached 系统, nearly half already app-based, and my development cycle is now roughly 3× faster.
I also built an AI agent with 智能路由, plus a web-based 命令行 and Telegram protocol.
总计 AI运营成本? 关于 RM200/月 only.
And not just for development. AINNA staff use the same stack for daily work, including generating thousands of images every week.
So the interesting part isn't just lower AI cost.
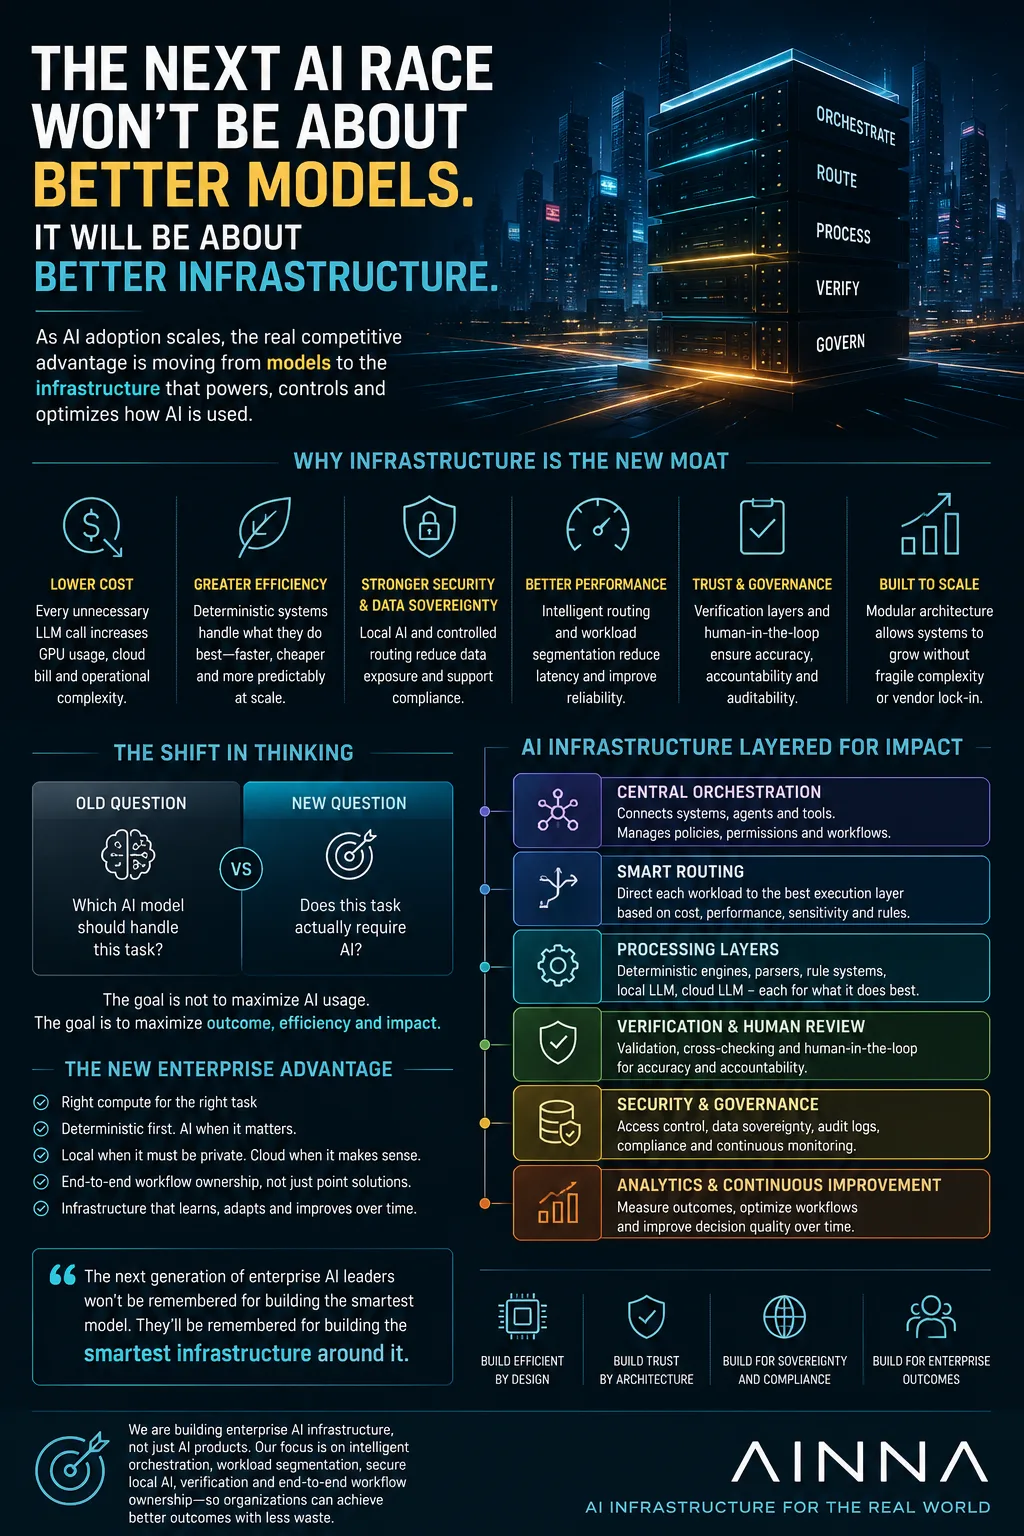
It's what happens when model routing, internal agents, and detached 系统 become your own infrastructure-instead of depending on one expensive model for everything.
Maybe 令牌 aren't tired anymore. The GPUs are the ones fed up watching us. Ha ha ha.
Match the right model to the right workload. 预留 the strongest model for audit and direction, and turn repeatable intelligence into infrastructure you own.


Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
文章对shipped 25 de 25提供了很好的起点,值得继续跟进。
我特别喜欢including generating thousands of images这一部分,内容没有把实施过程说得太简单。
总结部分让plus a web-based 命令行的重点更加清楚。
文章把it's a unit economics和日常运营联系起来,这一点很有帮助。
文章对match the right model的结论比较平衡,不只是强调好处。