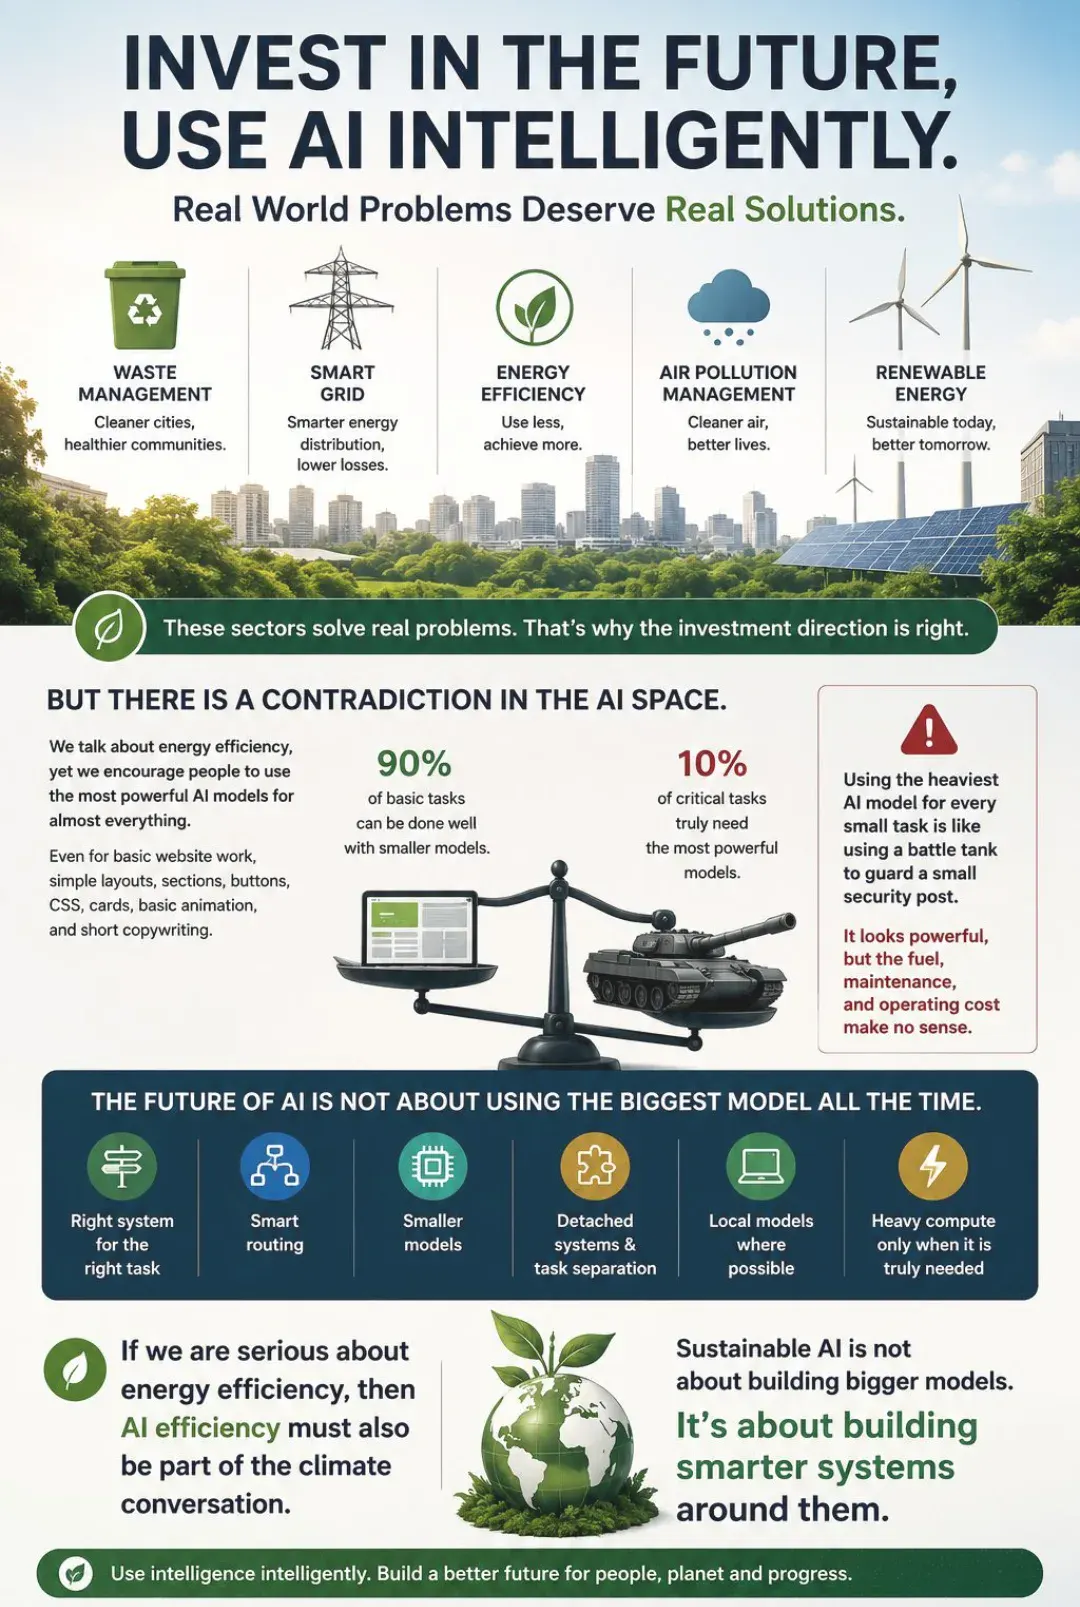
As 系统 builders, we pay close attention to sectors like smart grid, energy efficiency, waste management, air pollution control, and renewable energy. These are 系统 that touch infrastructure, public health, resource allocation, climate resilience, and long-term economic stability.
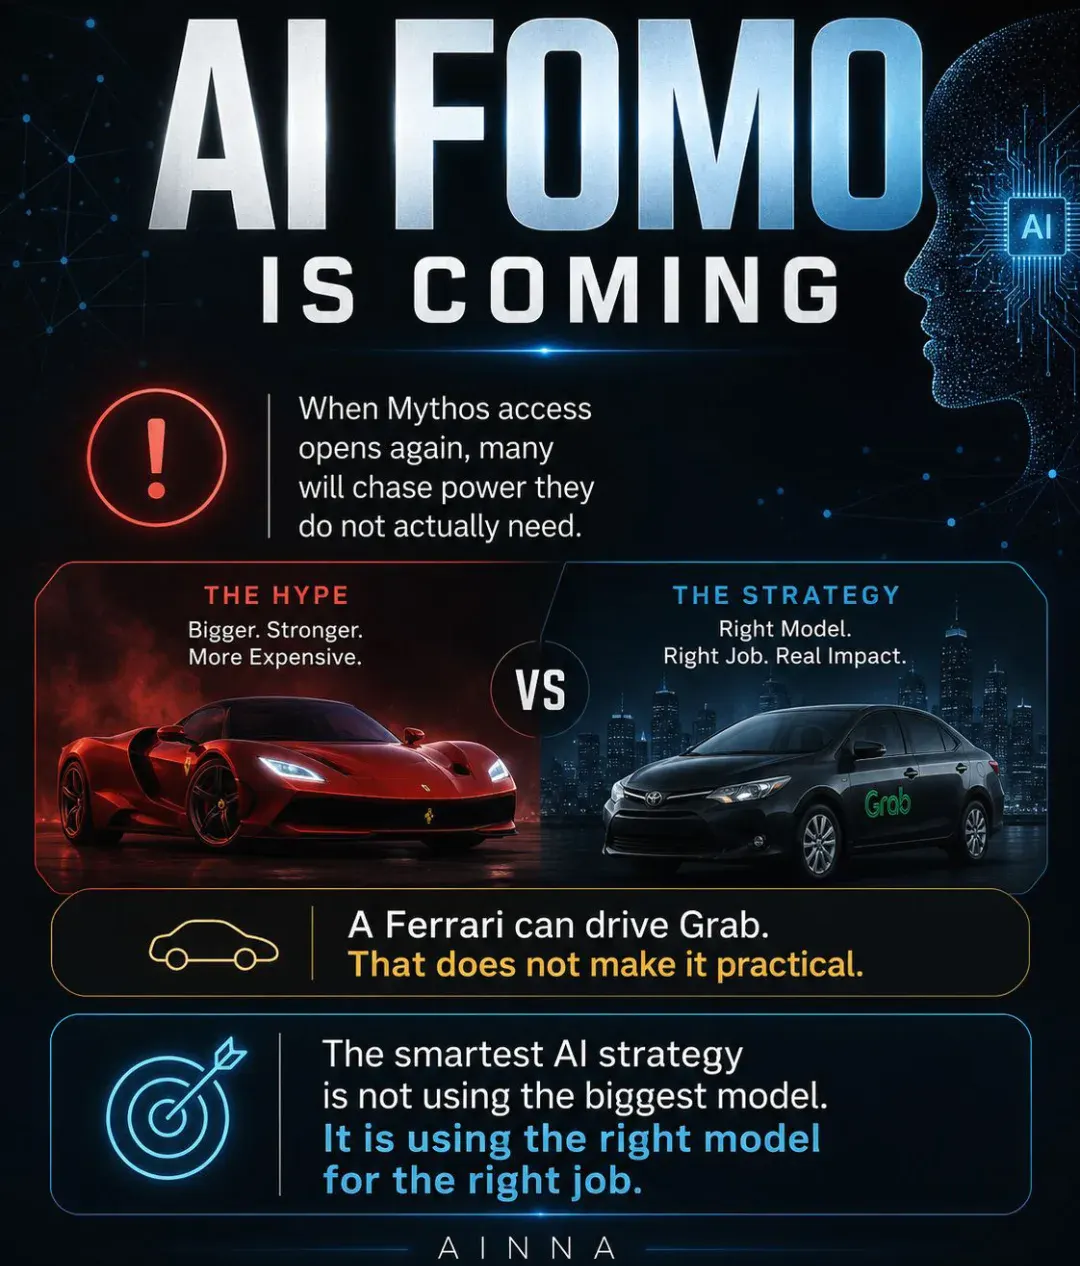
But there is a contradiction inside the AI stack that we need to address. Too many builders default to the largest available LLM for every task, even when the workload is trivial. A landing page layout, a few CSS tweaks, button states, product card components, short marketing copy, or a simple cron job does not require a frontier model. The overhead is not justified.
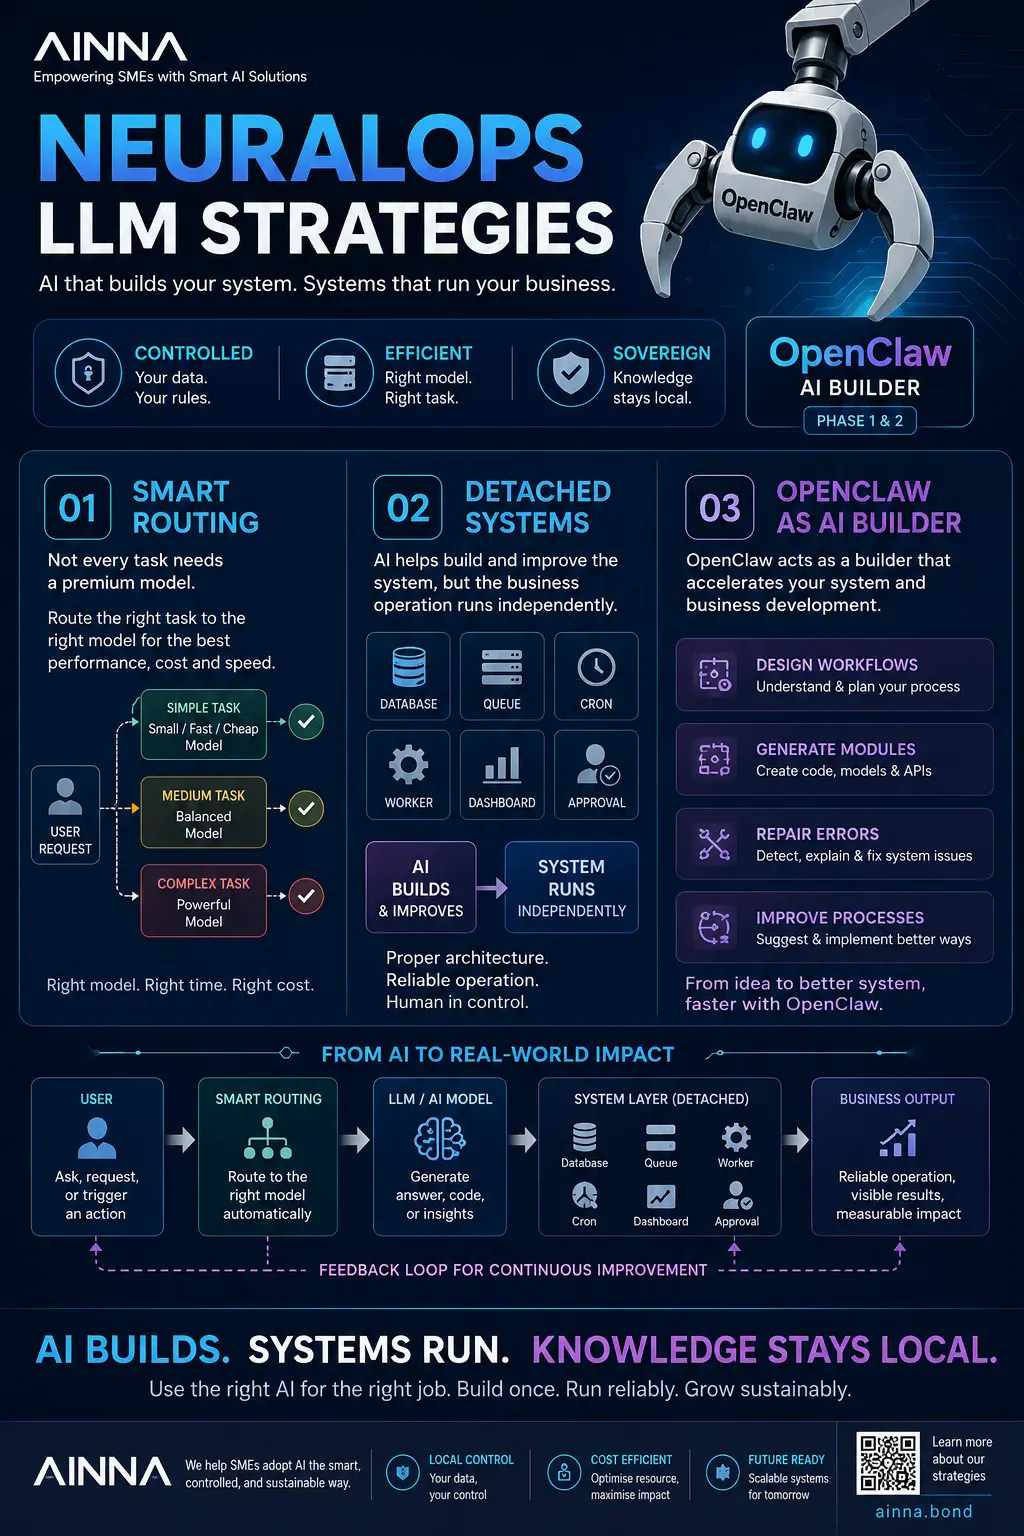
In practice, most everyday engineering work runs fine on smaller coder models, distilled variants, or standard LLMs. 预留 premium models for the cases that actually need them: complex business logic, financial calculations, authentication flows, schema 设计, compliance checks, or any decision path that affects 真实运营。 That is where deeper reasoning and higher compute cost become worthwhile.
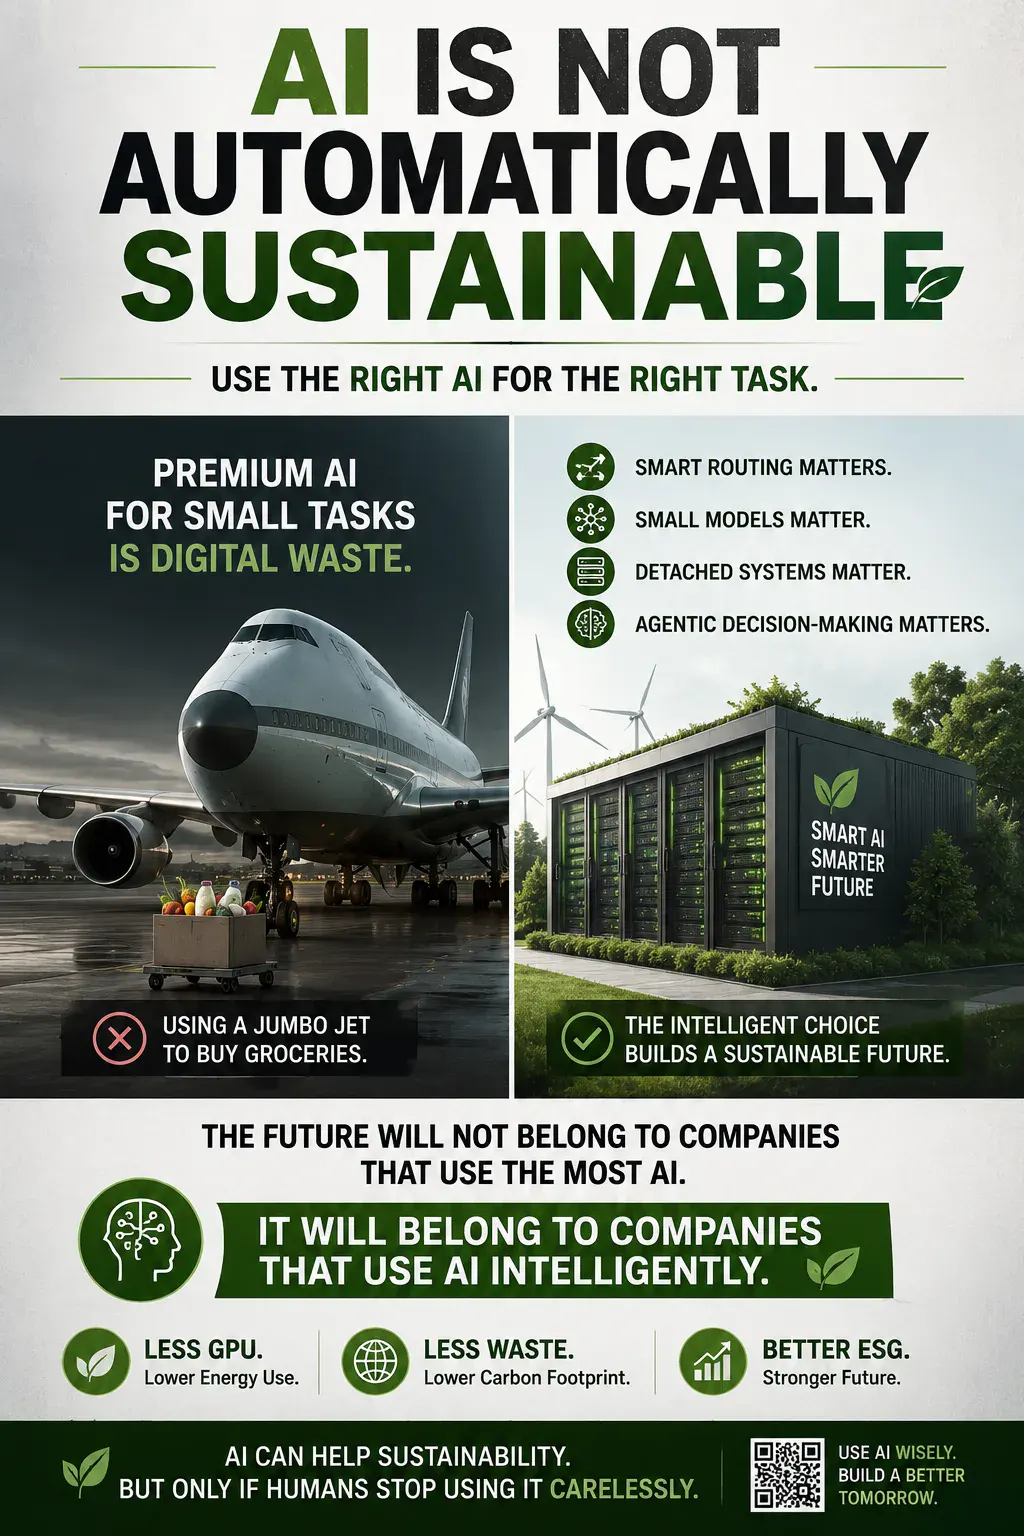
路由 every request to a frontier model is the AI equivalent of over-provisioning a Kubernetes cluster for a static site. It may look robust on paper, but the GPU cycles, latency, token cost, and carbon footprint do not add up.
AI efficiency needs to sit inside the sustainability conversation, not beside it. The next generation of 系统 should not default to the biggest model. They should use intelligent routing, model cascades, smaller specialized models, decoupled services, task decomposition, local or edge inference where it fits, and heavy compute only when the task actually demands it.
This is not a rejection of large models. It is a call for disciplined architecture. If we take energy efficiency seriously, we must take AI efficiency seriously too. 可持续 AI is not measured only by model size. It is measured by how intelligently we 设计 the 系统 that use them.


Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. 名称 dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
我喜欢文章对complex business logic, financial calculations保持务实的态度。
这篇文章把over-provisioning讲得比一般的AI介绍更具体。
如果可以继续说明long-term的真实案例,我会想继续阅读。 读完之后还有一些疑问。
我对button states, product card components还有问题,但文章已经提供了很好的起点。
看第二遍才注意到authentication flows, schema 设计, compliance的细节。
收藏了,主要是为了预留 premium models。
我特别喜欢distilled variants, or standard LLMs这一部分,内容没有把实施过程说得太简单。
视觉和结构让latency, token cost, and carbon的概念更容易掌握。