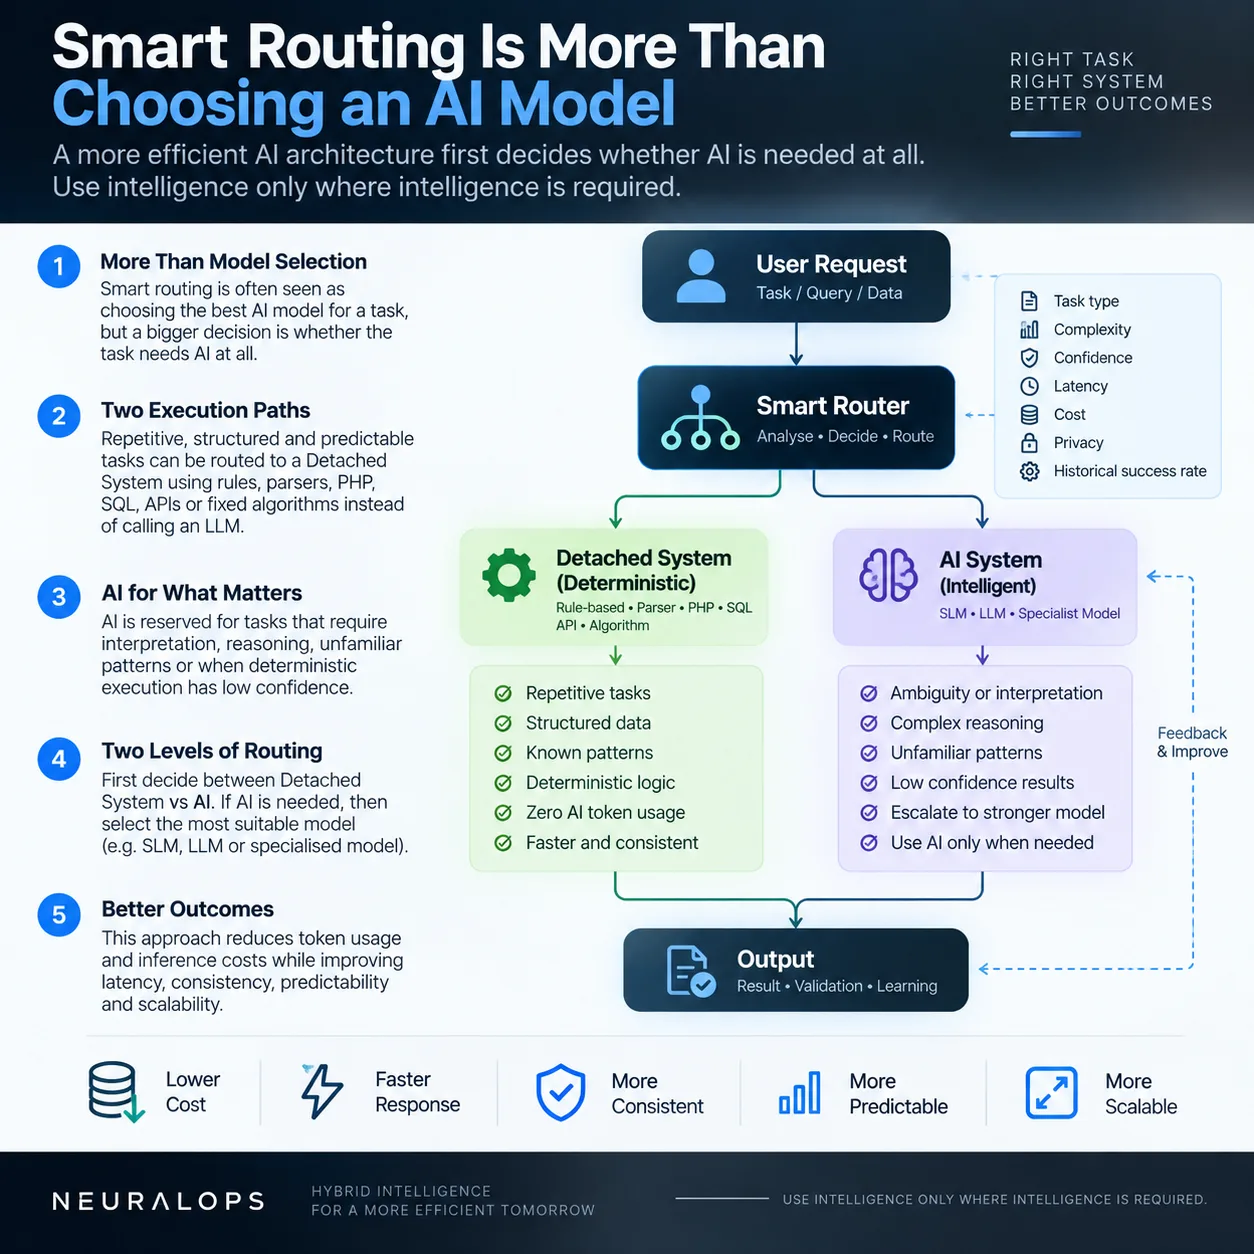
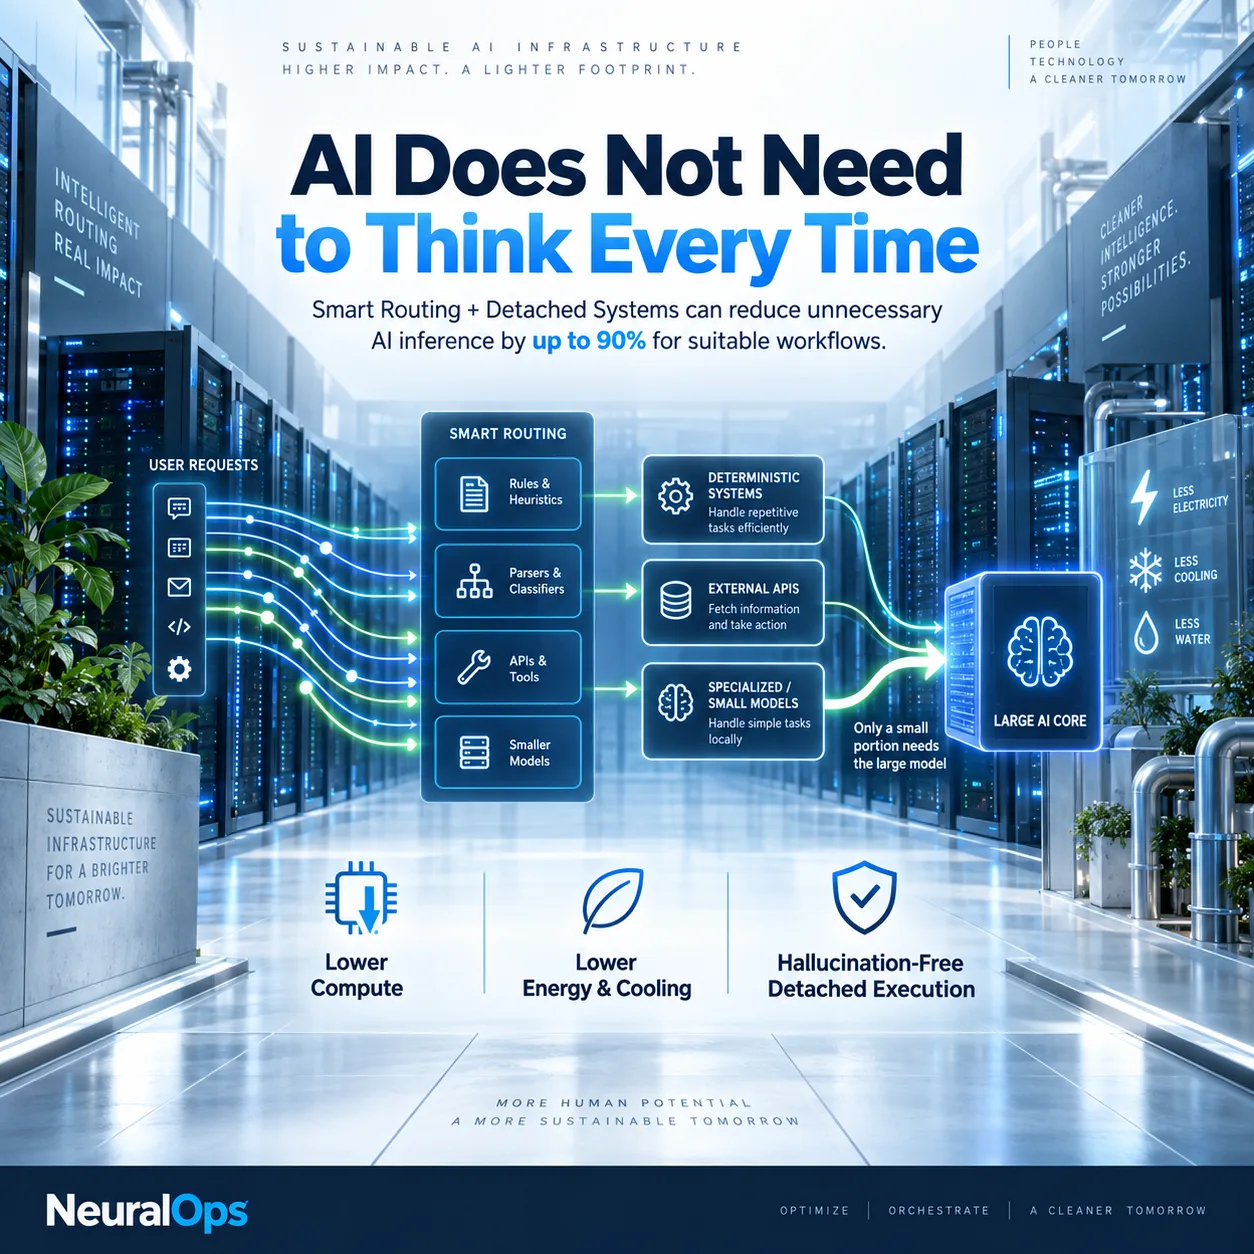
In a hybrid architecture, the 智能路由器 can choose between an AI 系统 and a 独立系统. Repetitive, structured, and predictable workloads can be executed by deterministic components such as rules, parsers, PHP, SQL, APIs, or fixed algorithms-avoiding the recurring cost of LLM calls.
AI is then reserved for tasks that genuinely require intelligence-ambiguity, interpretation, reasoning, unfamiliar patterns, or situations where deterministic execution produces low confidence. This ensures that every AI invocation delivers real value, not just operational overhead. The 系统 can also escalate difficult cases from a smaller model to a more capable model when necessary, optimizing cost per outcome.
This creates two levels of routing. The first is execution routing: 独立系统 vs AI. The second is model routing: which AI model should handle the task. This is fundamentally different from conventional multi-model routing, which starts with the assumption that every task must eventually be processed by AI-and every AI call must be paid for.
The principle is simple: use intelligence only where intelligence is required. Instead of asking only, “Which AI should do this?”, a more efficient architecture first asks, “Should AI do this at all?” This approach directly reduces token consumption and inference costs-two of the largest variable expenses in AI operations-while improving latency, consistency, predictability, and scalability. For Malaysian 中小企业, this translates into measurable savings and a clearer path to ROI.
Official 跨-网络 Resource


Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. 名称 dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
这篇文章把consistency, predictability, and scalability讲得比一般的AI介绍更具体。 这个部分我还需要再想一下。
这篇文章对use intelligence only where intelligence的解释很清楚,实际操作的重点也很容易理解。
关于multi-model的风险和限制还可以再展开,不过基础说明已经很好。
同意作者对which starts with the assumption的判断,但执行起来还有难度。 这个部分我还需要再想一下。
我会把using a smaller model这一段分享给需要了解技术的同事。
如果有更多parsers, PHP, SQL, APIs的数据和结果会更完整。