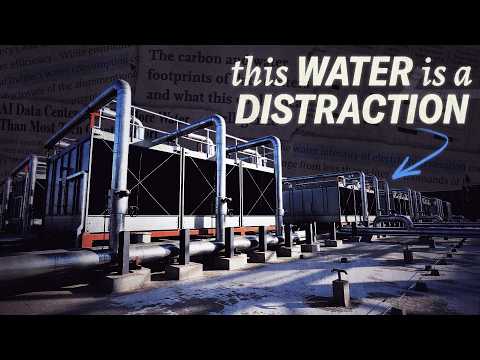
AI infrastructure is scaling fast, but there's a hidden cost we can't ignore: electricity, cooling, and water consumption.
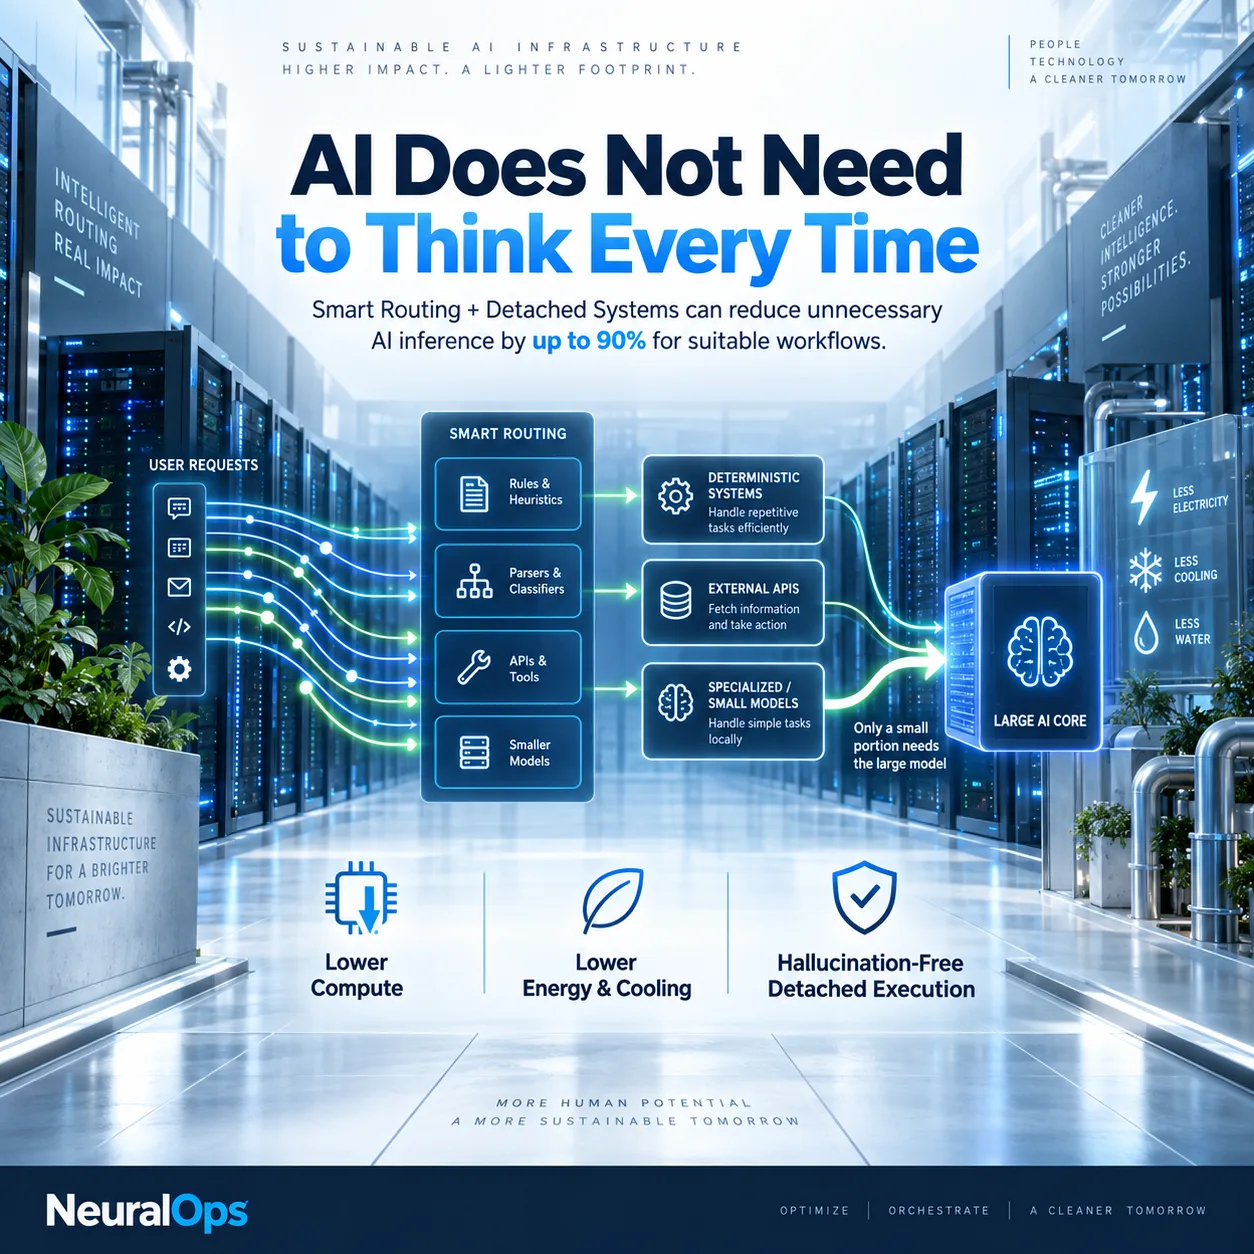
Recent studies show that once a model is deployed, inference alone can consume 80–90% of a model's total energy. Every redundant LLM call burns GPU cycles, drives up electricity use, generates heat, and scales cooling demand.
That's why we're building NeuralOps on a different principle:
Not every task requires an LLM.
Through 智能路由, we handle tasks with rules, parsers, databases, APIs, or smaller models first. We only invoke heavy LLM reasoning when it's genuinely necessary. Once a workflow stabilizes, we convert it into a detached deterministic 系统 that runs repeatedly without any LLM calls.
For appropriate repetitive 工作流, this approach can cut AI inference demand by as much as 90%.
储蓄 go far beyond token costs.
Reduced inference → lower GPU utilization → less electricity → less heat → less cooling → reduced water consumption.
We also gain reliability.
Once a workflow runs detached from an LLM, we have zero LLM 令牌 and zero hallucinations in that execution path. We apply intelligence where reasoning is essential, and let deterministic 系统 handle repetitive tasks.
可持续 AI won't come solely from more efficient data centres.
It also depends on stopping unnecessary AI inference from ever reaching the data centre.
That's the path we're pursuing with NeuralOps:
use AI only when intelligence 是必需的, and rely on deterministic 系统 otherwise.
#Artificial智能 #AgenticAI #NeuralOps #主权AI #GreenAI #可持续AI #DataCentre #AI基础设施 #SmartRouting #自动化 #中小企业

Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
我特别喜欢once a workflow runs detached这一部分,内容没有把实施过程说得太简单。
我会把储蓄 go far beyond token这一段分享给需要了解技术的同事。
80这部分我看了几遍,值得再想。
第一次看到有人把80讲得这么坦白。
我喜欢文章对可持续 AI won't come保持务实的态度。