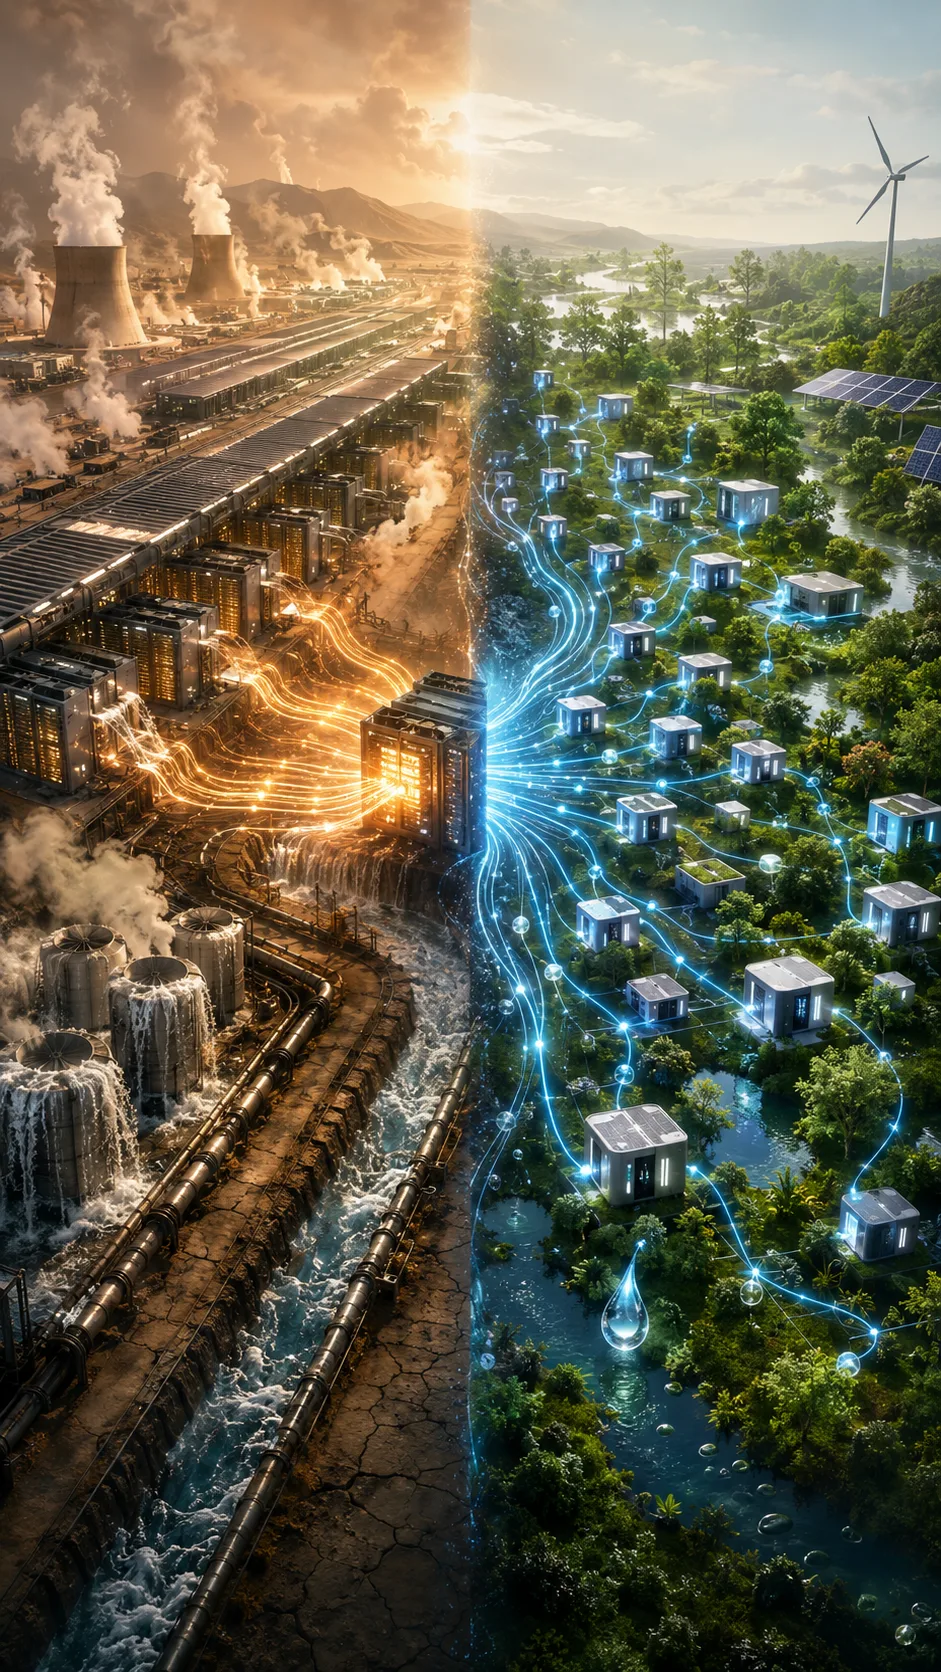
从 a 系统-integration view, the answer isn't just better chillers or chasing PUE. The real lever is how inference load is distributed across the stack.
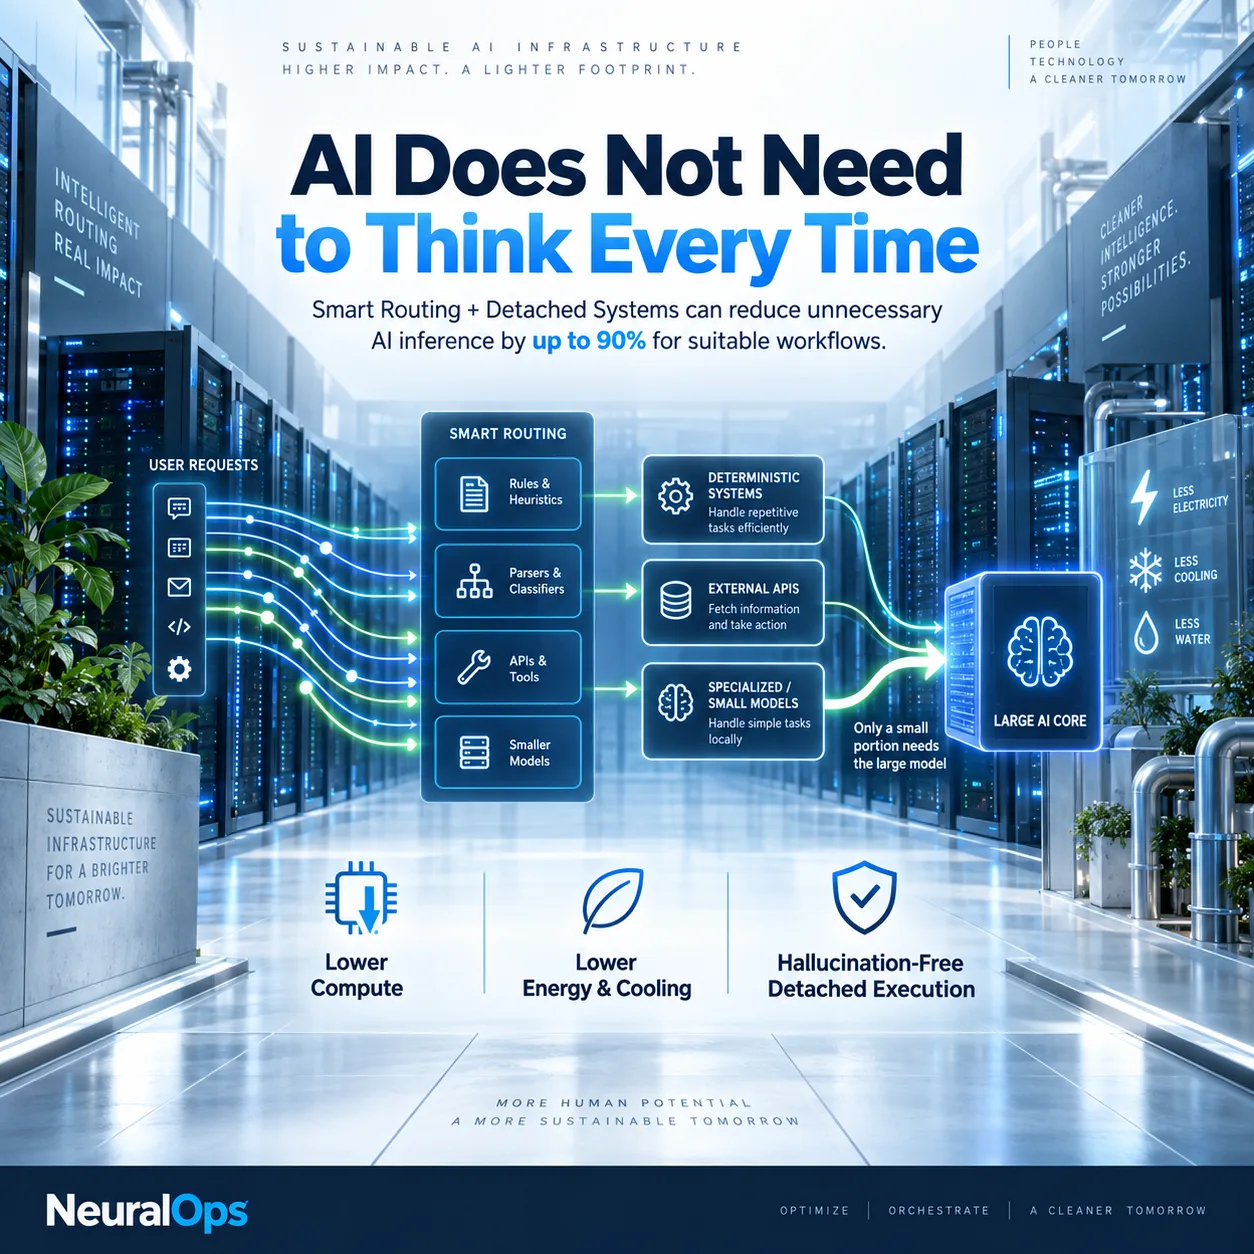
Most production tasks don't need to hit a large language model. With NeuralOps, we tier workloads: lightweight calls go to edge models, micro-models, or cache hits, and heavy inference is reserved only for the requests that actually need it. That architectural choice directly changes the thermal footprint of the deployment.
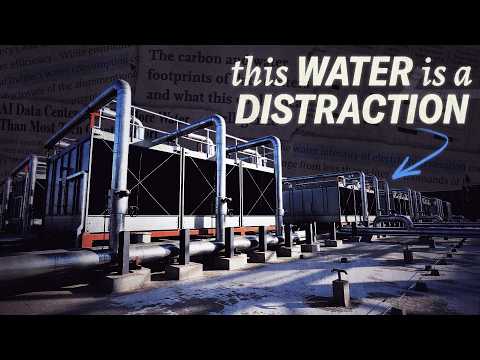
We've measured up to 90% lower AI compute energy usage on defined workloads. 更少算力 means less heat, less cooling, and less water drawn by on-prem or colocated GPU clusters.
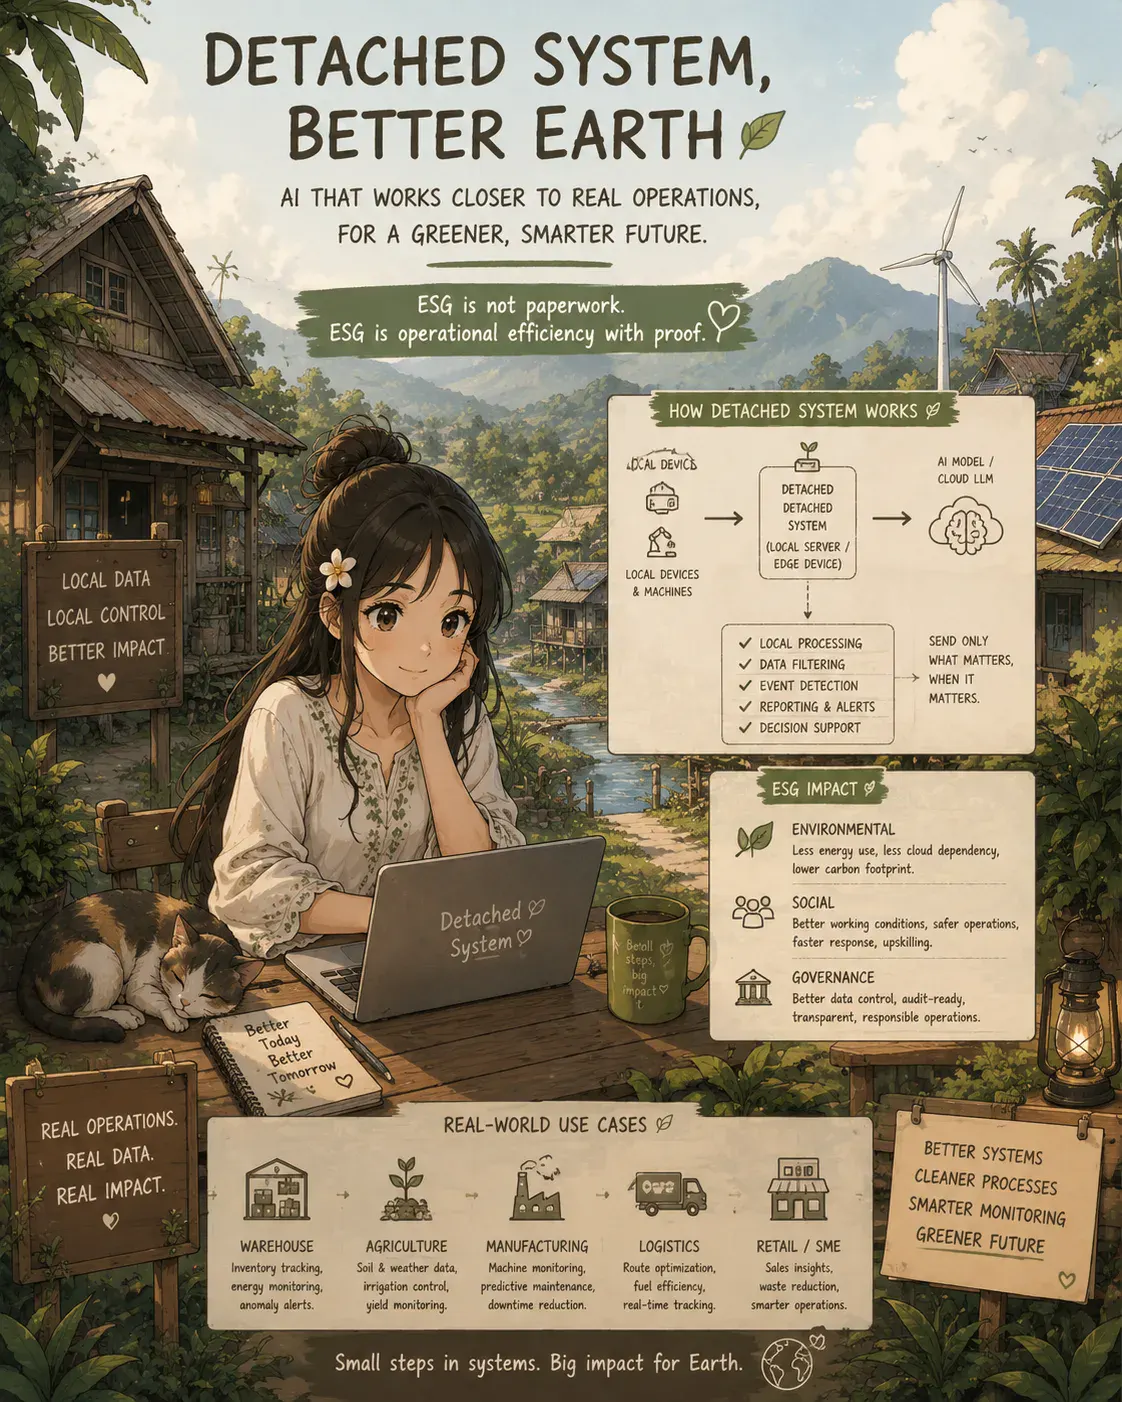
At AINNA, we build ESG into the architecture phase-not as a post-launch checkbox. Resource efficiency is part of how the 系统 is designed to run in production, not a retrofit.
https://masli.bond/esg/
Official 跨-网络 Resource











Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
90%读起来很清楚,也容易跟着理解。
第一次看到有人把90%讲得这么坦白。
同意作者对modern hyperscale AI data centers的判断,方向很清楚。
关于lightweight calls go to edge的例子很实用,适合团队继续讨论。
我特别喜欢to 90% l 90%这一部分,内容没有把实施过程说得太简单。
这篇文章适合团队用来开始讨论post-launch。
这篇内容让我更容易理解为什么micro-models值得关注。
文章把we've measured up to 90%和日常运营联系起来,这一点很有帮助。