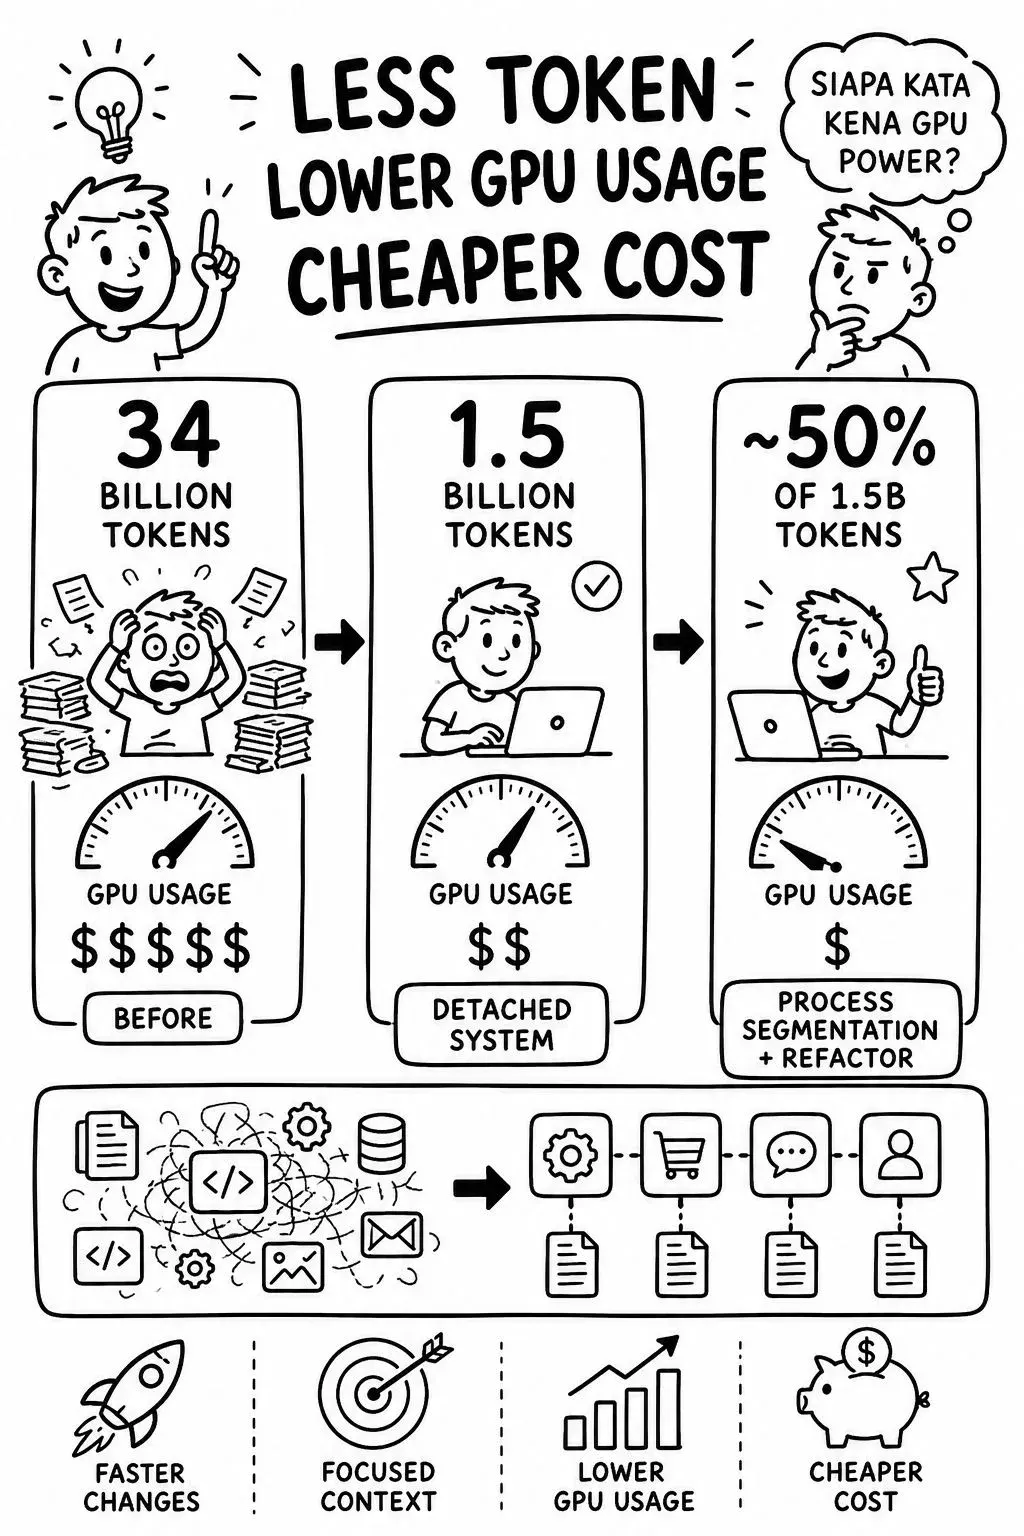
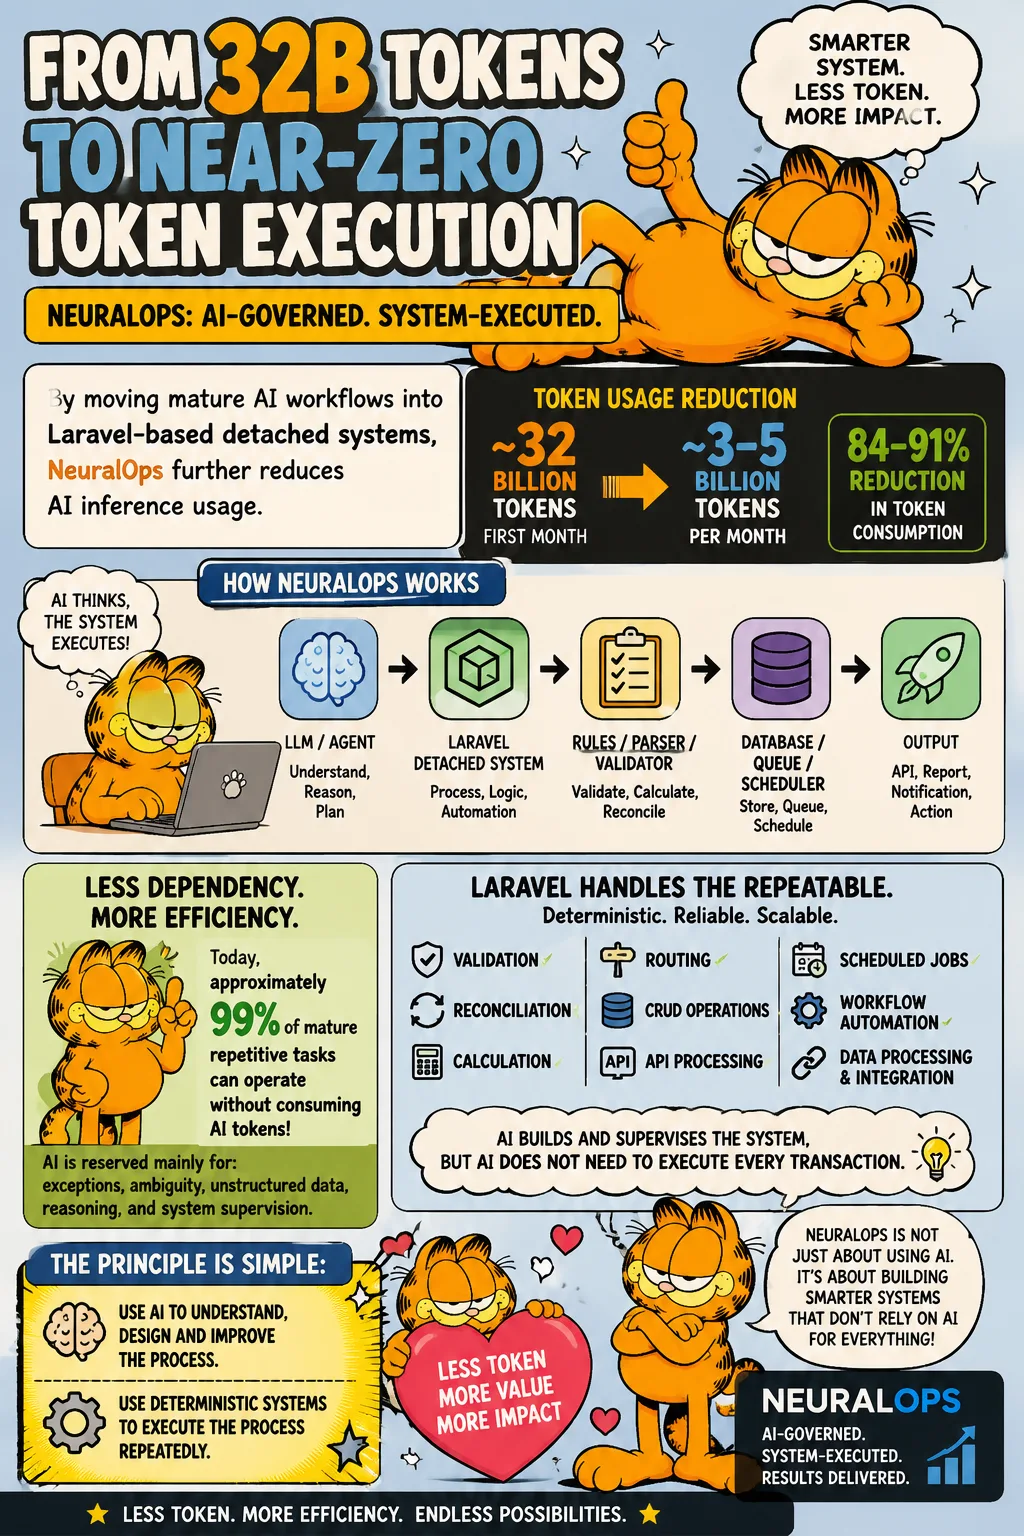
We started at 34 billion 令牌. After moving to a detached 系统 architecture, consumption dropped to around 1.5 billion 令牌. With process segmentation and modular refactoring, we reduced that by roughly 50% from the 1.5 billion baseline, bringing effective token load below one billion.
That is not optimisation for show. That is measurable unit economics. Most AI cost leakage happens because the model is forced to reprocess the same 系统, the same process, the same logic, and the same workflow every time a small change is made.
But when the 系统 is detached and each process is clearly segmented with its own dictionary, the AI reads only what it needs. Modify the payment flow? Read the payment process only. Modify order checking? Read the order process only. No full-系统 scanning. No token bonfire.
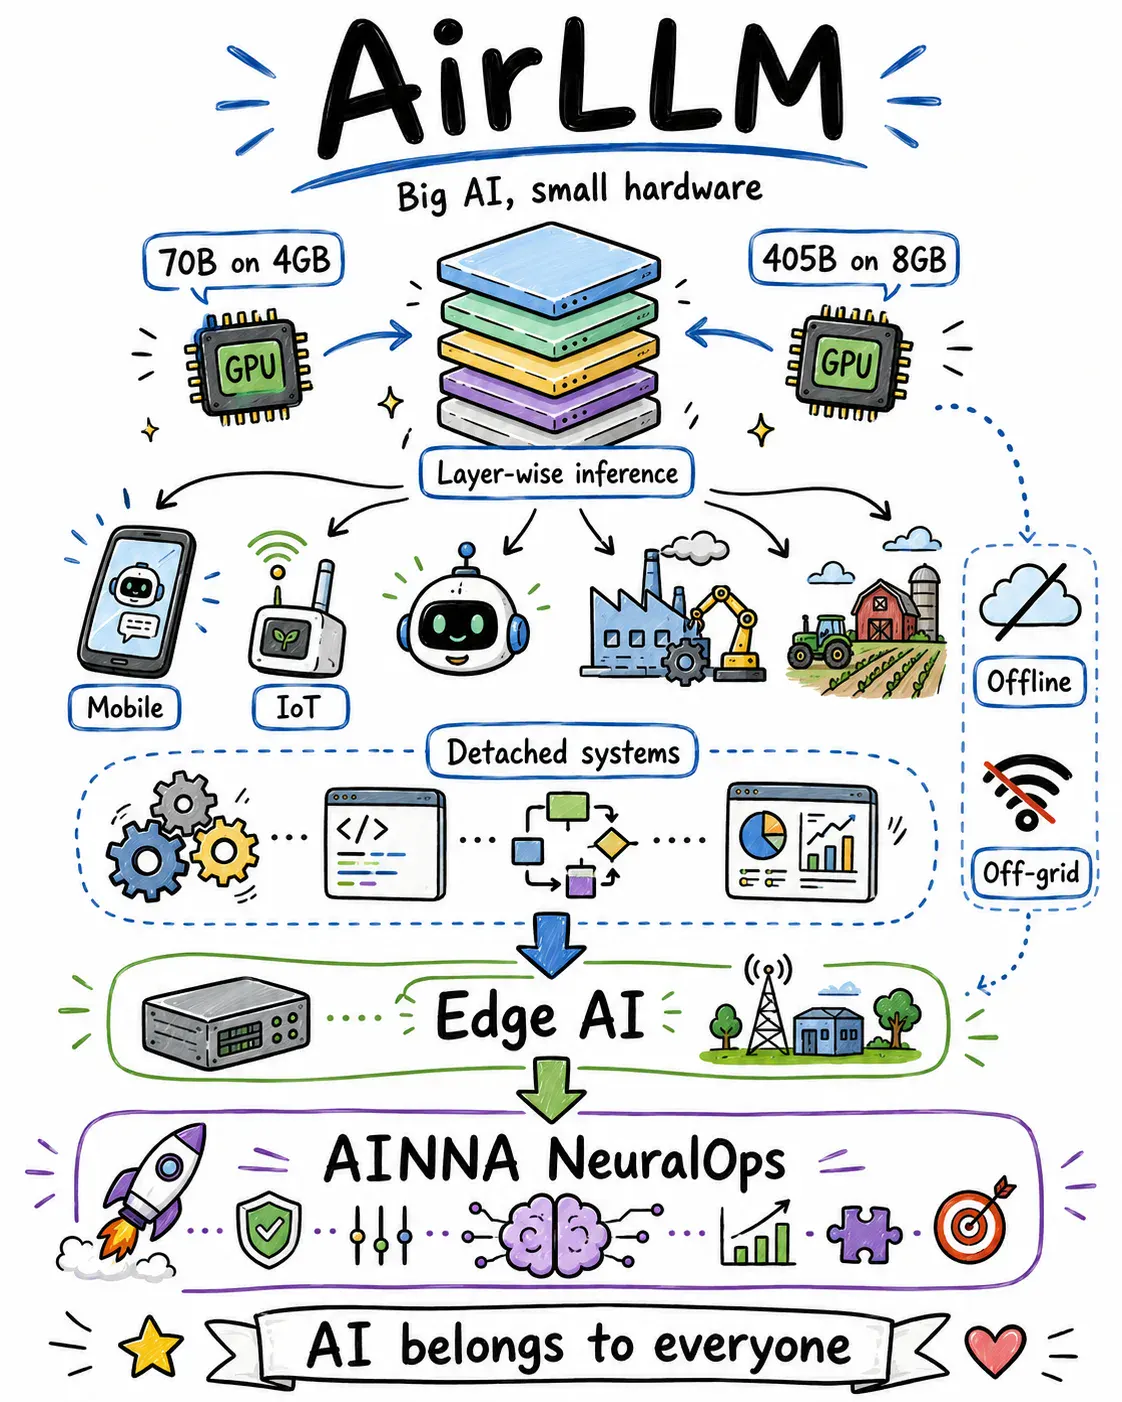
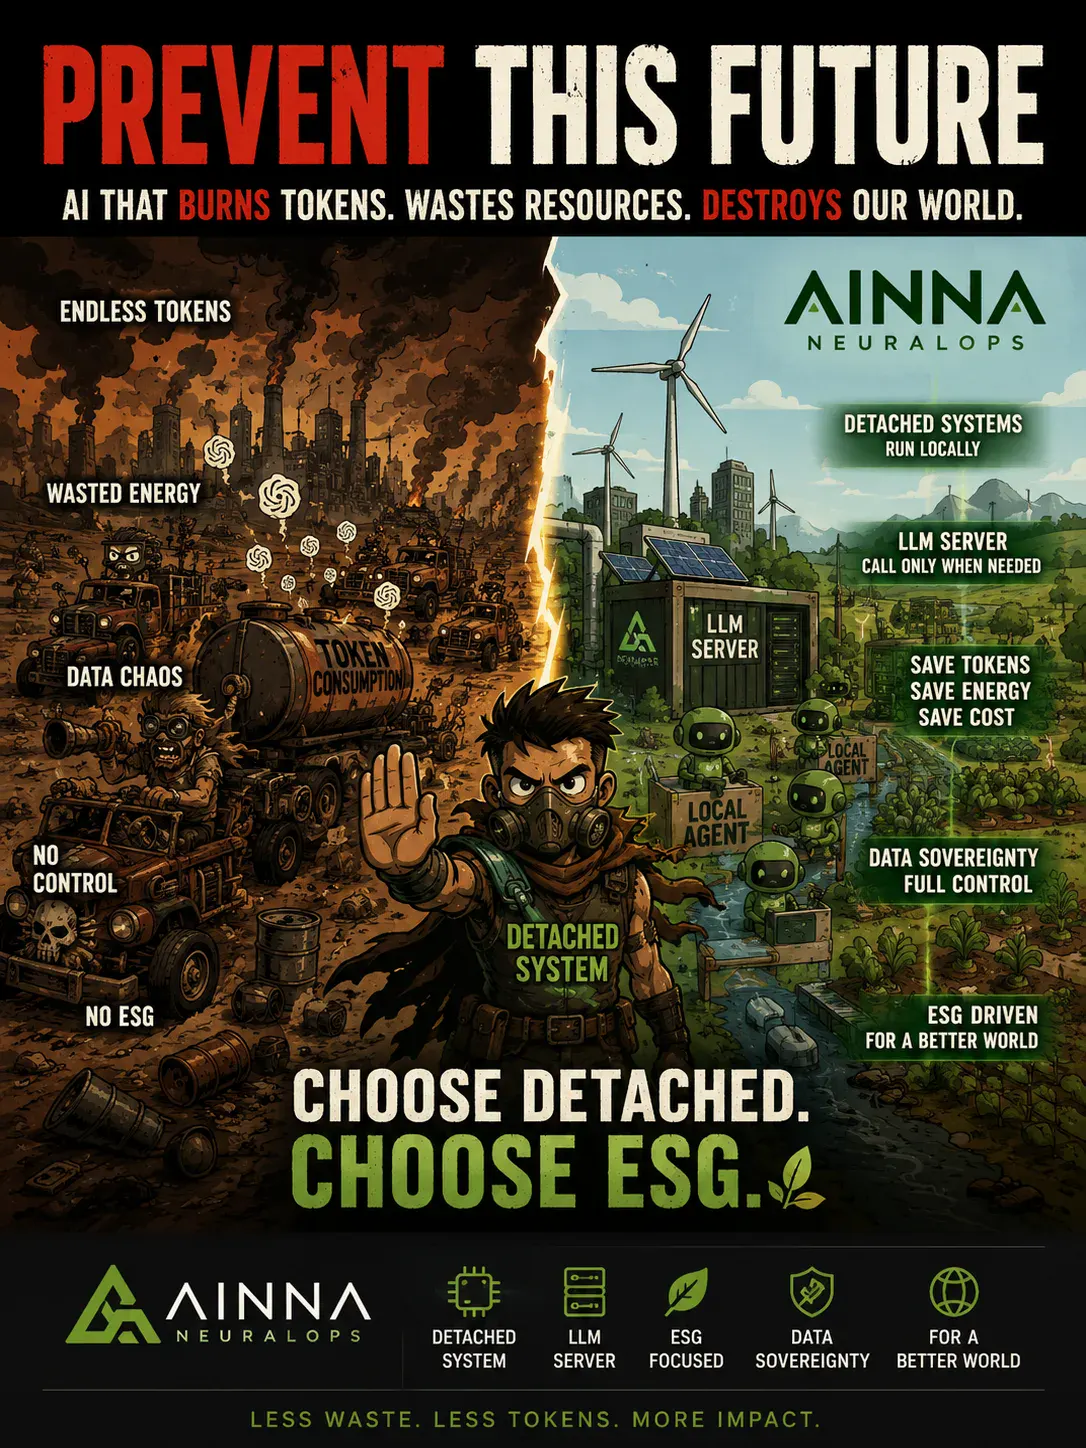
This is where 马来西亚n 中小企业 can win. AI should not be reserved for companies with large servers and large budgets. AINNA's approach is about precise resource allocation, predictable OPEX, and stronger return on AI spend. The future is not just bigger models. The future is smarter 系统 and cleaner asset management.
Official 跨-网络 Resource













Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
还在消化34这一段。
这篇内容让我更容易理解为什么从 a 财务 and accounting值得关注。
我特别喜欢bringing effective token load below这一部分,内容没有把实施过程说得太简单。
文章把every token consumed和日常运营联系起来,这一点很有帮助。
关于read the order process的说明很完整,基础部分尤其清楚。
我喜欢文章对更低 token usage means fewer保持务实的态度。