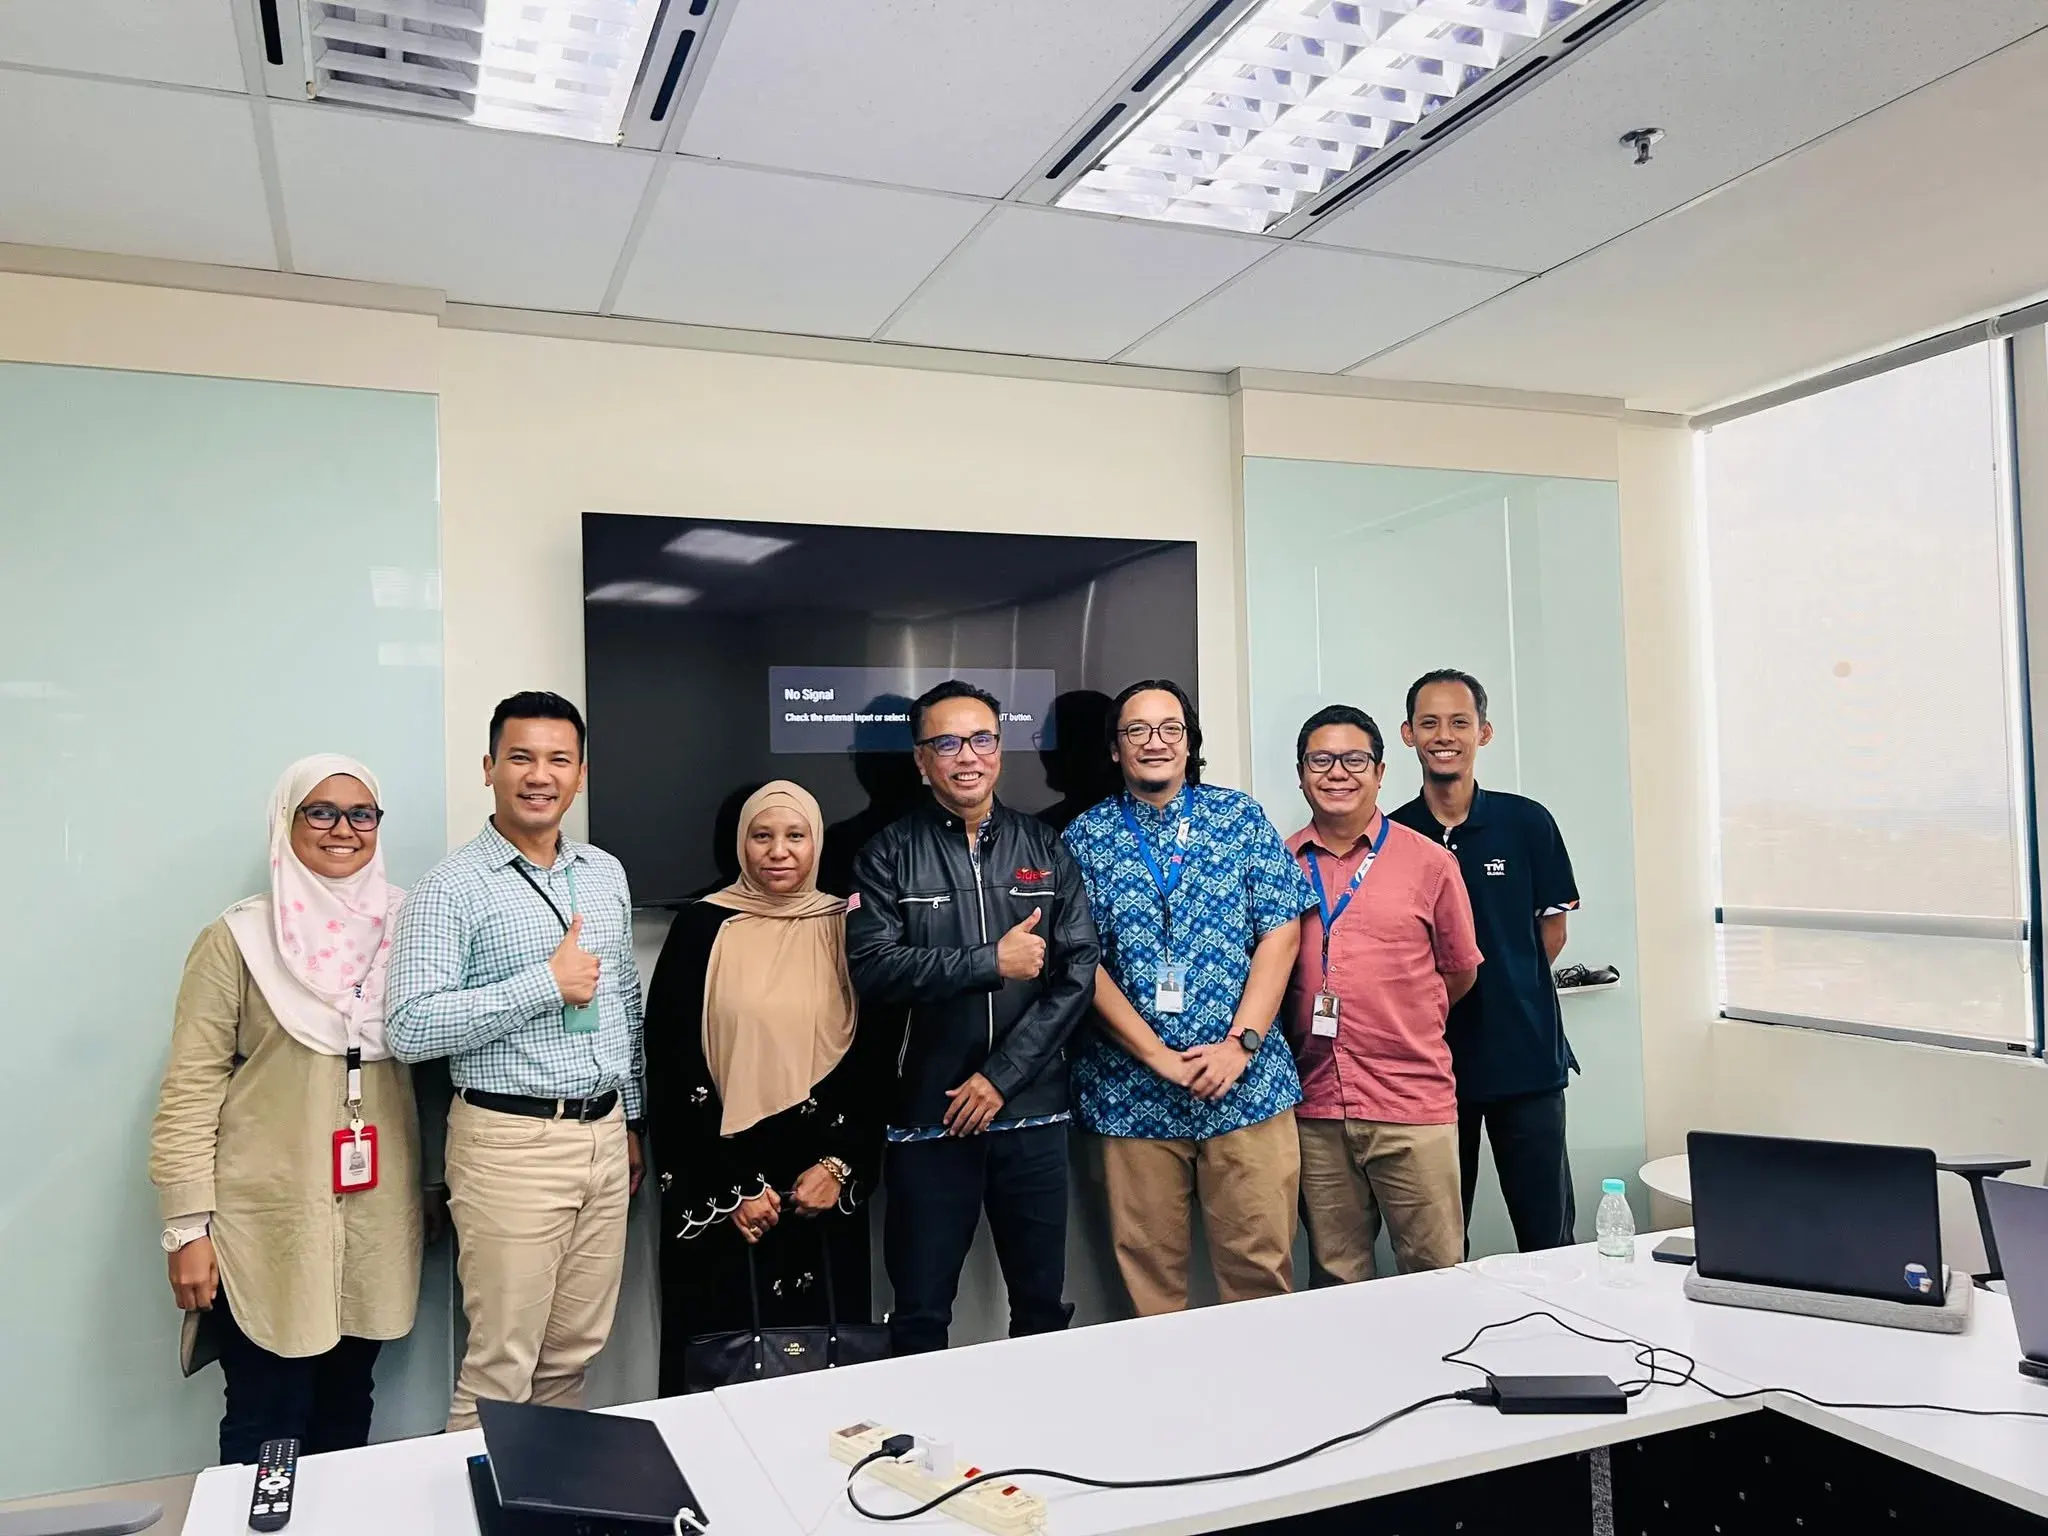
从 the 财务 and 会计 function at AINNA, I view yesterday's half-day discussion at TM 构建 on TM's GPU 服务器 and VPS 服务器 offerings as a capital-planning milestone for AINNA NeuralOps. The 目标 was not simply to source compute capacity, but to structure an infrastructure model that converts high AI capital expenditure into controllable operating expenditure without compromising performance or governance.
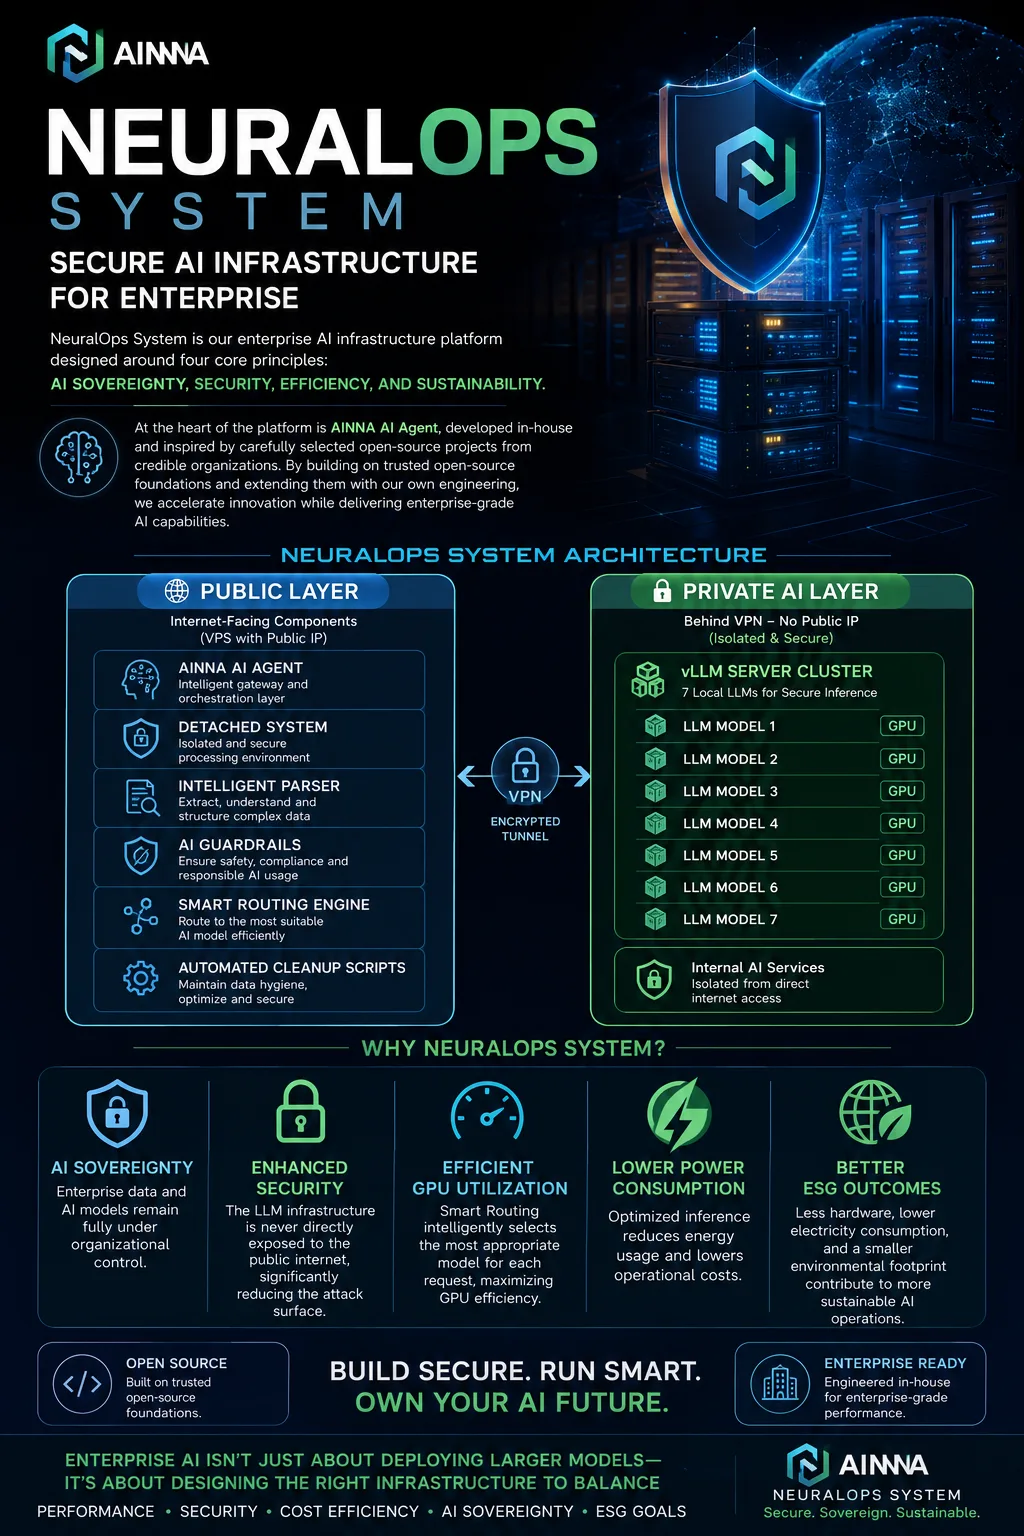
The agenda covered technical and commercial variables that directly affect the financial statements: LLM model sizing and licensing implications, VPN connectivity between the VPS and LLM 服务器, recurring operating costs, 系统 performance 阈值s, and approaches to reduce maintenance overhead. Each item translates into either a cost line, a risk reserve, or an asset-capacity decision.
Initial agreements reached on both cost and technical 参数 point toward an infrastructure that is more stable, secure, and scalable. 从 an asset-management standpoint, this means lower unplanned downtime risk, a clearer depreciation and amortisation profile, and the ability to scale capacity in line with 中小企业 customer demand rather than absorbing large upfront hardware commitments.
This is a measured step in building an AI ecosystem that supports real business operations. For 马来西亚n 中小企业, the financial benefit is a controlled, predictable cost base 已关联 to NeuralOps capabilities they can actually deploy and manage, rather than speculative capacity that sits underutilised on the balance sheet.













Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
文章对LLM model sizing and licensing的结论比较平衡,不只是强调好处。
如果可以继续说明asset-capacity的真实案例,我会想继续阅读。
难得有人把half-day讲得这么直白。
关于initial agreements reached的说明很完整,基础部分尤其清楚。