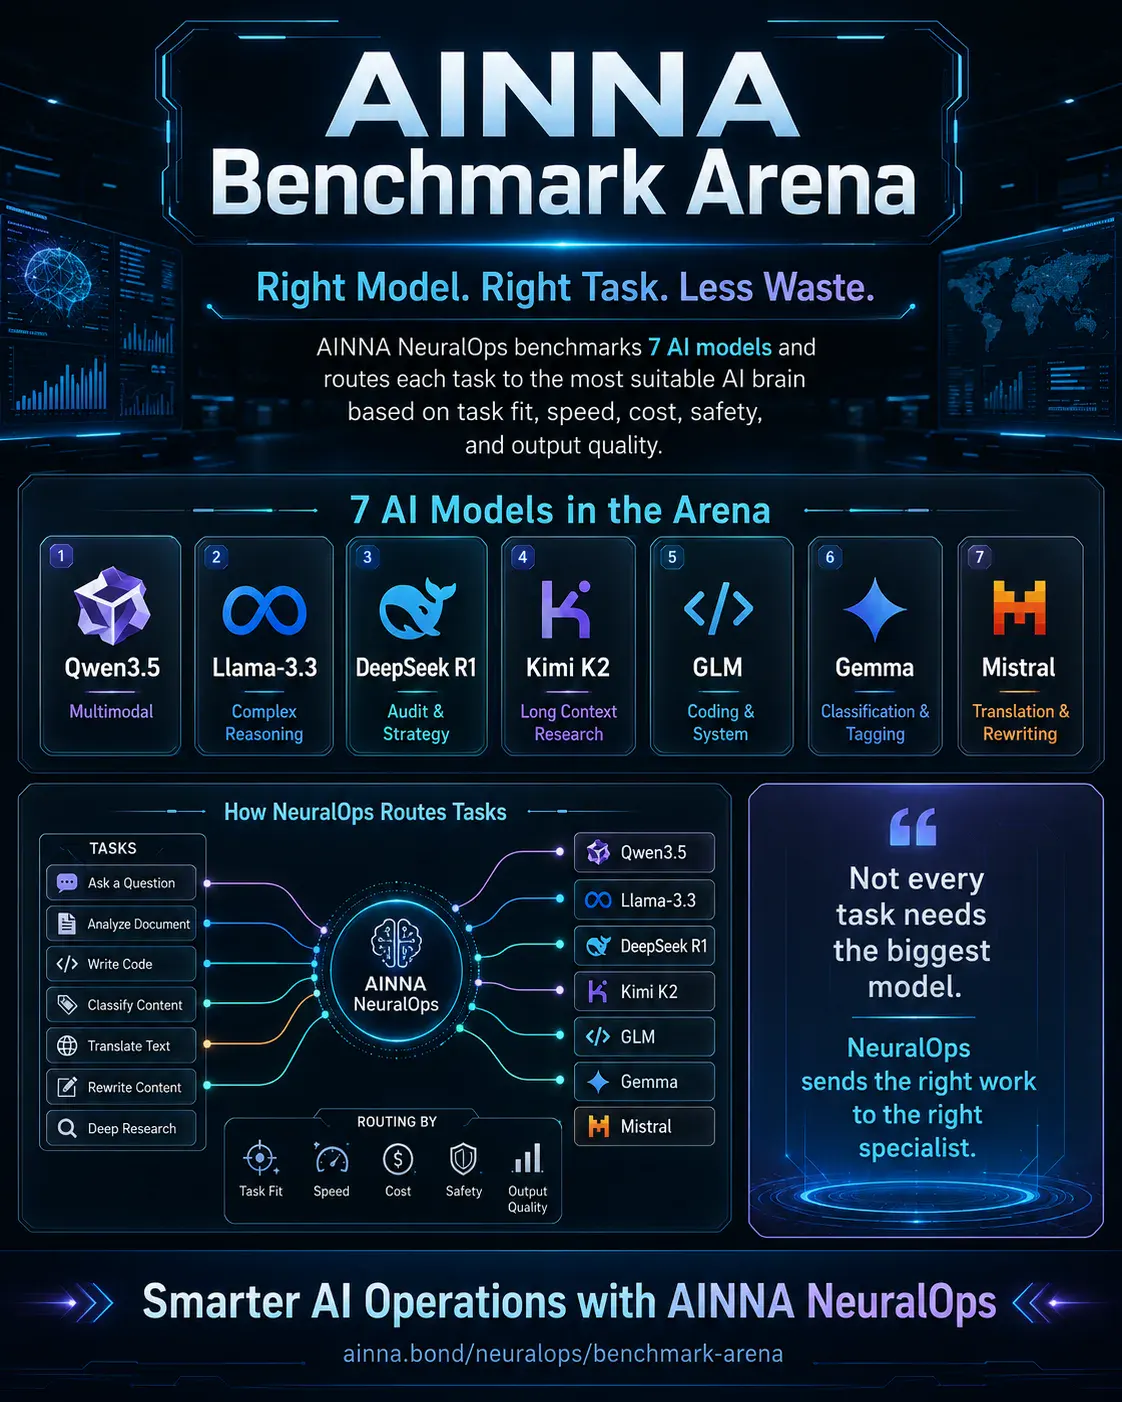
AINNA 基准竞技场:正确的模型,正确的任务,更少的浪费。.
As builders of AI 系统, we have all seen the same trap: reach for the biggest model every time a task comes in.
It looks safe in a prototype, but once you move into production it drains the budget, inflates token counts, adds latency, and burns compute on work that never needed that level of capacity. At AINNA, we 已停止 asking, “Which model is the strongest?” and started asking, “Which model is the right tool for this specific job?”
That question is what AINNA Benchmark Arena is built to answer.
AINNA Benchmark Arena is the model evaluation and routing layer inside AINNA NeuralOps. It benchmarks models against real operational workloads: multimodal analysis, long-document research, compliance review, coding, 系统 repair, classification, tagging, translation, rewriting, and strategic reasoning.
In our NeuralOps stack, every model is assigned a specialized slot. Qwen3.5 handles multimodal input: text, images, screenshots, and product visuals. Llama-3.3 covers complex reasoning and broad general-purpose tasks. DeepSeek R1 is our audit, compliance, risk, and strategic-planning model. Kimi K2 is used for long-context research and heavy document analysis. GLM takes coding, 系统 generation, and technical repair. Gemma runs fast classification, tagging, and intent detection. Mistral supports translation, rewriting, and language polishing.
This is where 智能路由 becomes critical.
Not every prompt needs a flagship model. A customer-message classification does not need the same reasoning layer as a compliance audit. A product tag does not need the same compute as a 100-page document comparison. A website bug fix does not need the same architecture as a poster image analysis. Each task gets the specialist it deserves.
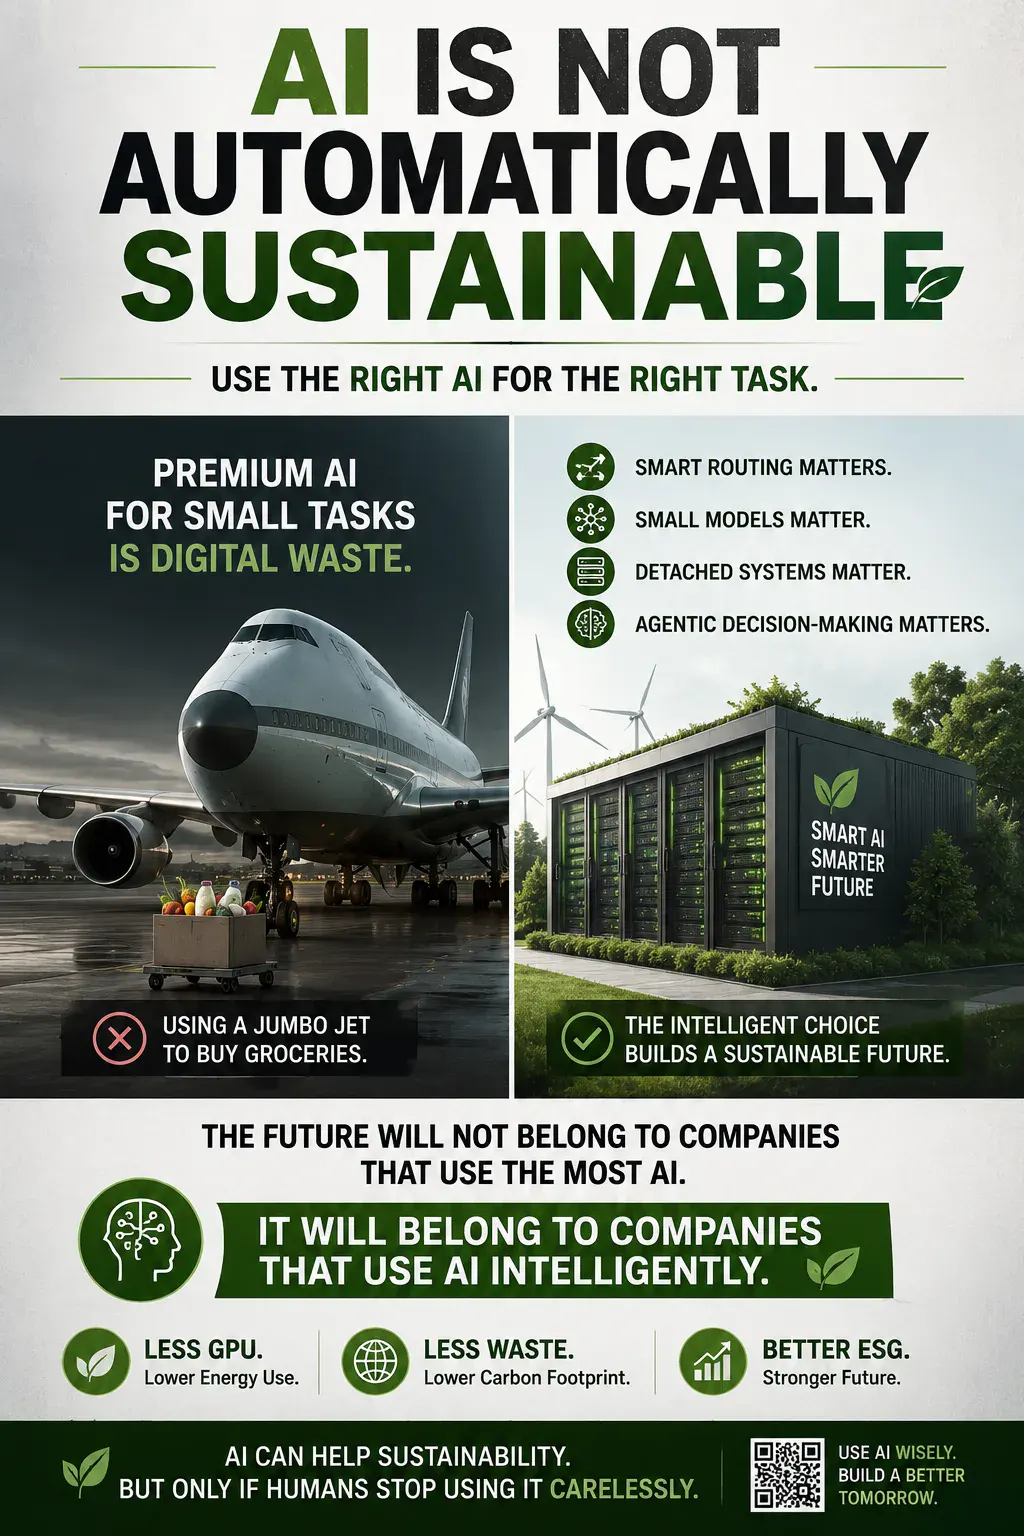
The easiest way to think about it is a hospital workflow. Not every patient needs a cardiothoracic surgeon. Some cases need triage, some need a GP, some need a specialist, some need an auditor, and some need an engineer. AI operations work the same way. 时间 the right specialist handles the right task, the whole pipeline becomes faster, cleaner, and more efficient.
AINNA Benchmark Arena is not a leaderboard. It is not designed to declare one model the universal winner. Instead, it scores model performance across the dimensions that matter in production: accuracy, task fit, speed, cost efficiency, compliance safety, and how much human cleanup 是必需的.
That is important because real-world AI adoption is not only about raw intelligence. It is also about sustainability, consistency, operational cost, and risk control.
A model that writes beautiful prose but requires heavy editing is not always the right pick. A model that is brilliant but overpriced for simple tasks is not operationally efficient. A model that is fast but weak on compliance should never touch sensitive claims. The goal is not to throw more AI at the problem. The goal is to use AI more intelligently.
For AINNA, this feeds a broader architecture goal: NeuralOps as an operating layer for efficient AI execution.
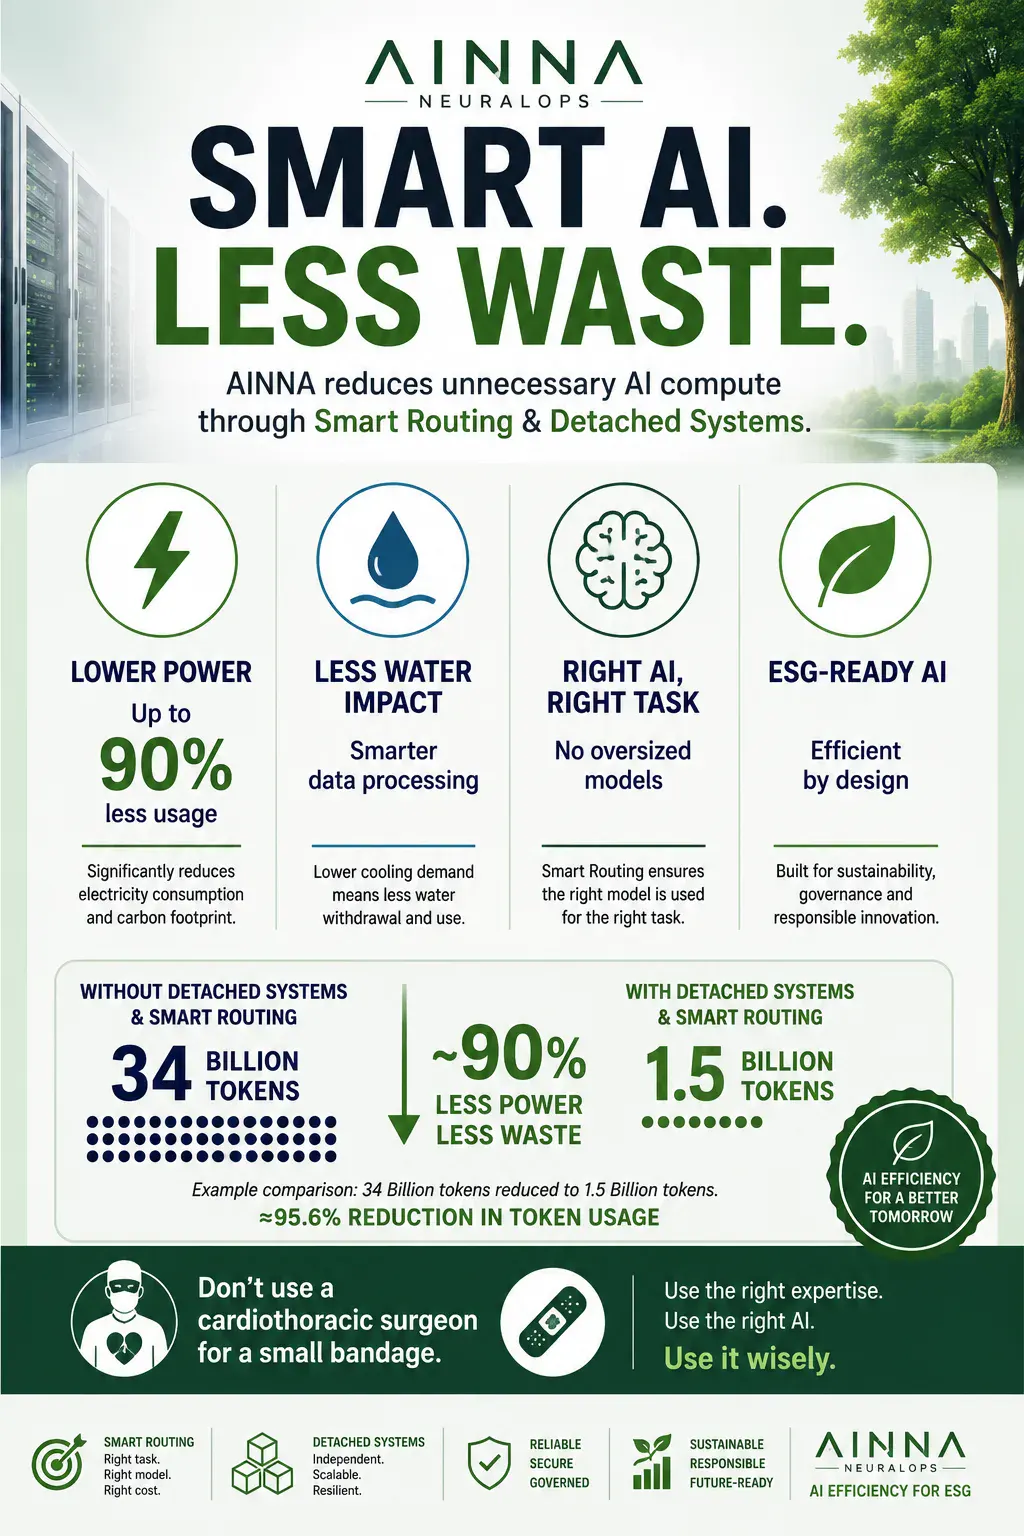
By combining benchmarking, 智能路由, and detached execution, we strip out unnecessary compute without sacrificing quality. Instead of keeping every agent or model warm all the time, AINNA NeuralOps spins up the right capability exactly when it 是必需的. That is the kind of architecture that actually scales inside real business operations.
AINNA Benchmark Arena helps operations and engineering teams answer questions like these:
Which model should handle product image analysis?
Which model owns compliance review?
Which model is best for long documents?
Which model should repair 系统 errors?
Which model is enough for classification and tagging?
时间 should a task escalate to a stronger model?
Where can we reduce token usage without dropping quality?
这就是 direction we are building toward.
Not bigger just because bigger sounds impressive.
Not expensive just because expensive feels premium.
Not complex just because complexity looks advanced.
Just the right model, for the right task, at the right moment.
That is the principle behind AINNA Benchmark Arena.
Right 模型. Right 任务. Less 废弃物.













Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
这篇内容让我更容易理解为什么AINNA benchmark arena值得关注。
这篇文章适合团队用来开始讨论reach for the biggest model。
视觉和结构让AINNA benchmark arena的概念更容易掌握。
我特别喜欢AINNA benchmark arena这一部分,内容没有把实施过程说得太简单。
如果可以继续说明reach for the biggest model的真实案例,我会想继续阅读。