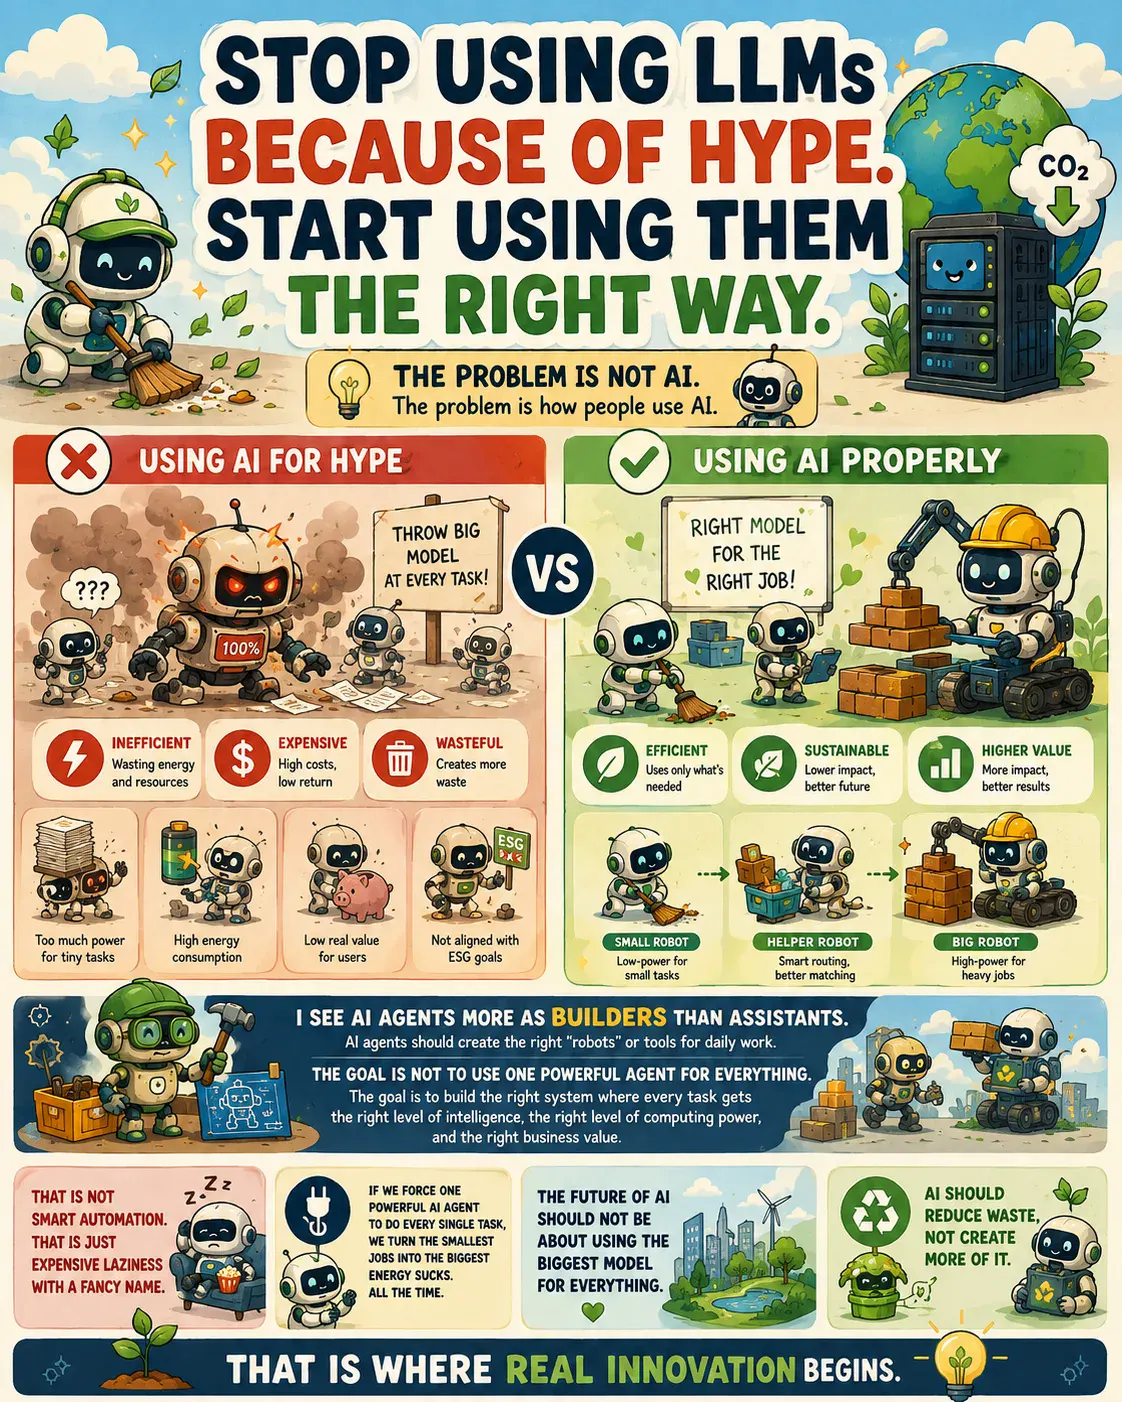
In fact, it drives up carbon footprints, inflates cloud bills, adds operational debt, and leaves end users with little to show for it.
The issue is not the models themselves.
The issue is how we architect around them.
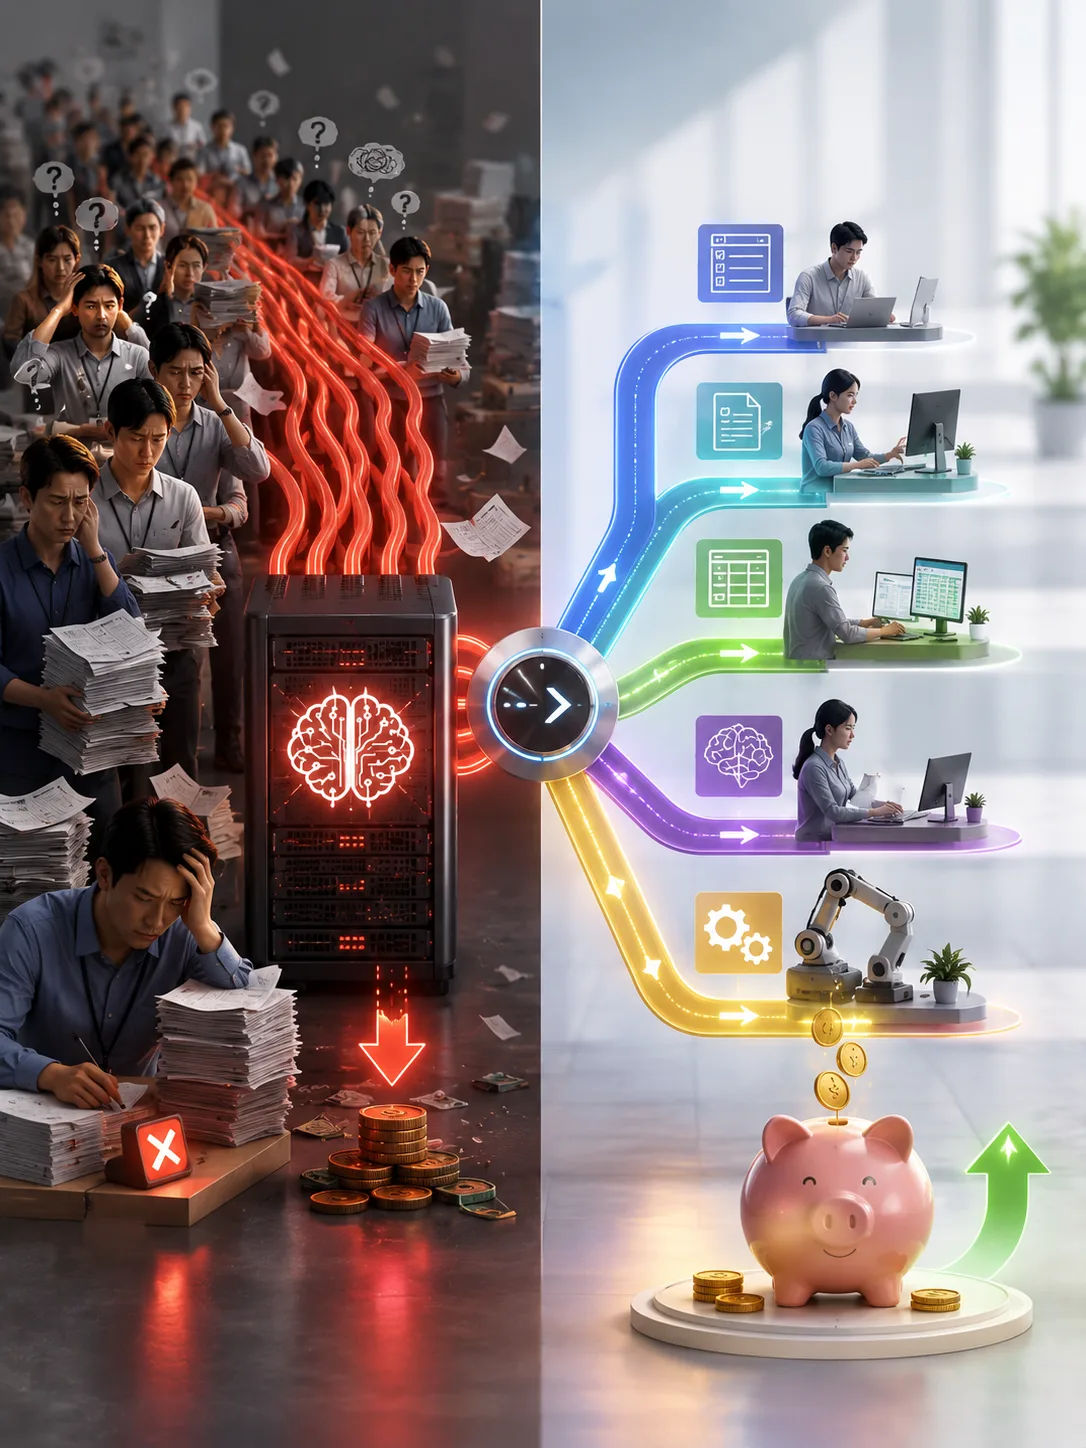
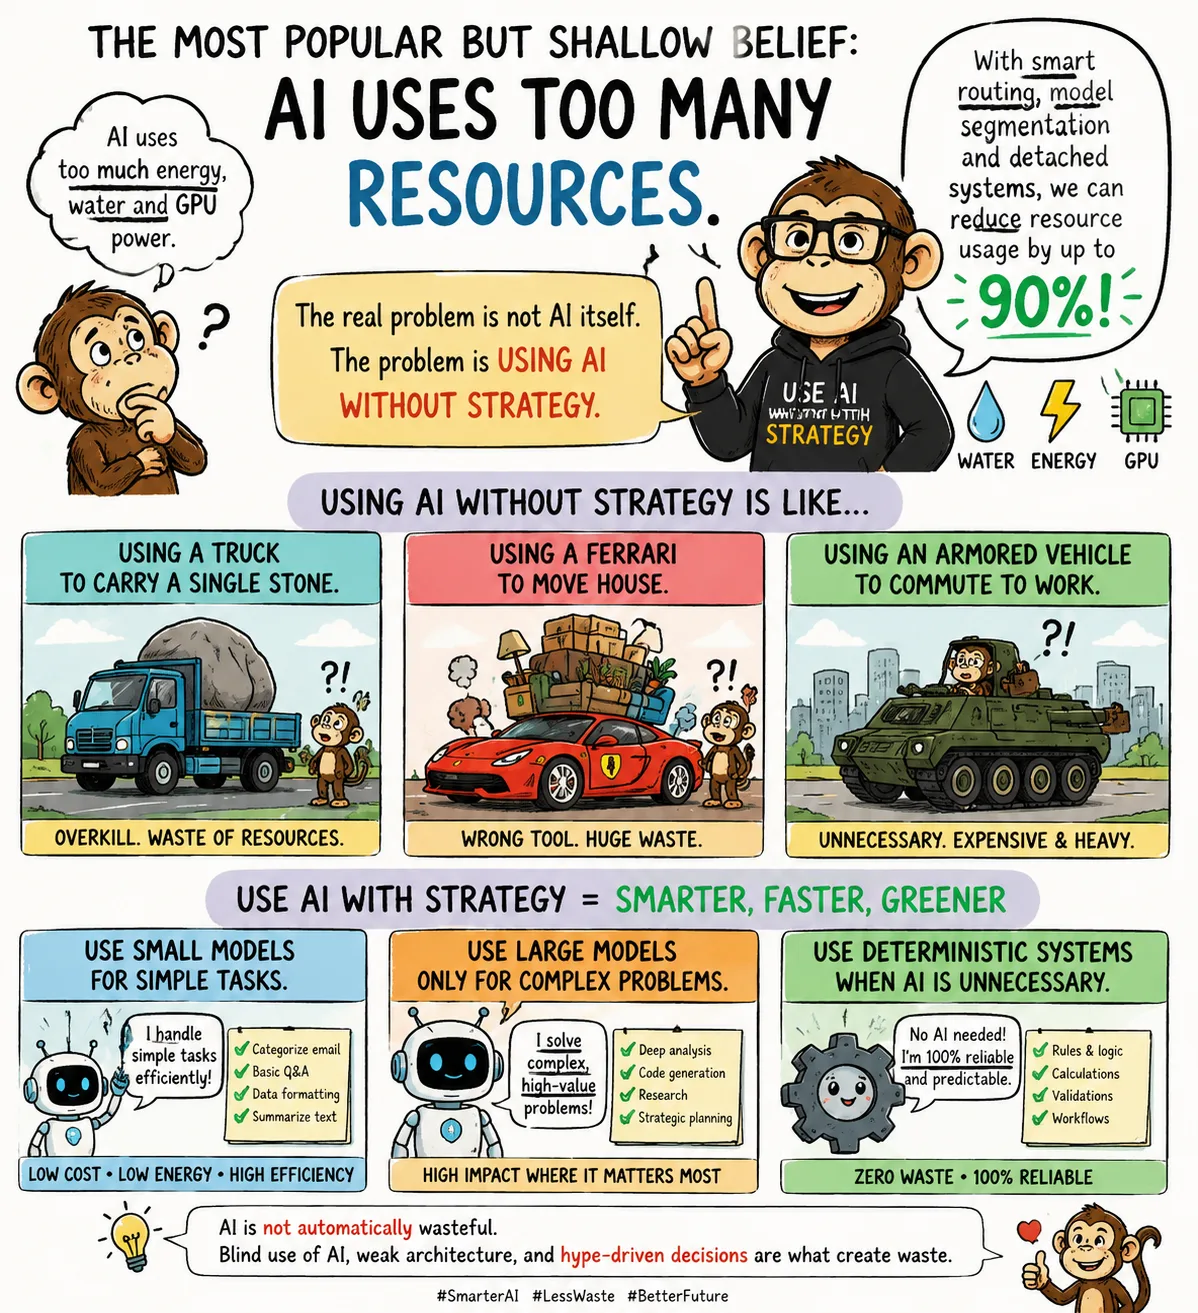
There is a clear gap between slapping an LLM on a problem and engineering an AI 系统 that actually belongs in production. Hype-driven deployment means routing every request to a 70B-parameter model whether the task needs it or not. It demos well, but under the hood it is a compute-hungry, cost-heavy architecture.
Proper AI work is about matching the right component to the right workload.
I treat AI 智能体 as 系统 integrators, not chatbox sidekicks.
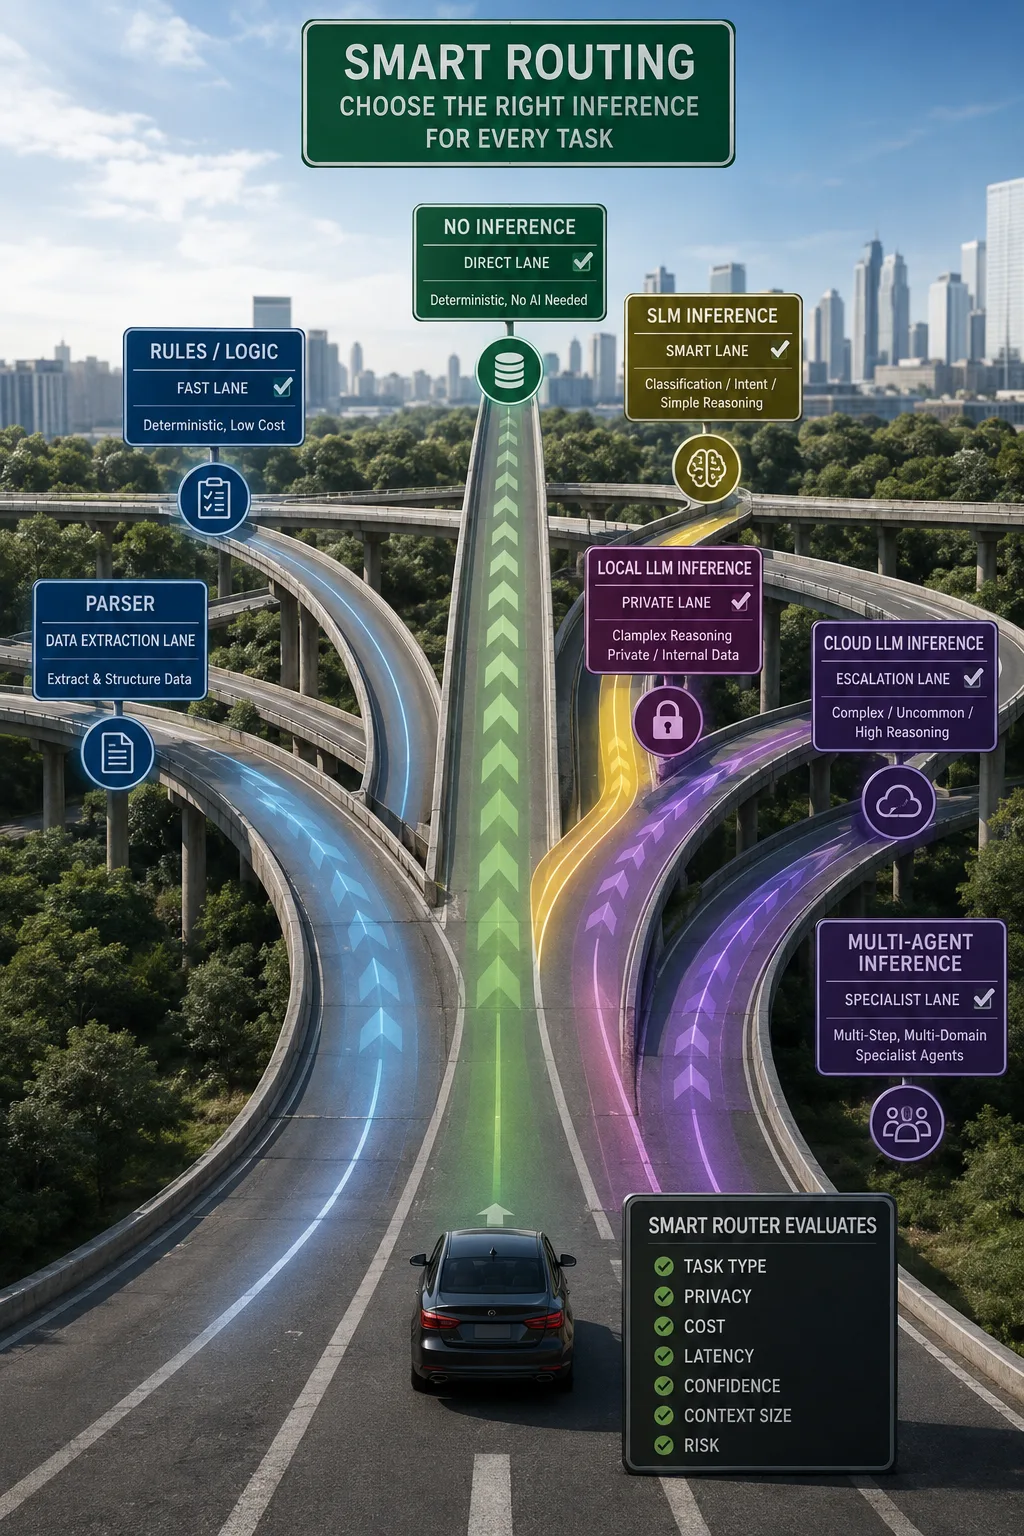
A well-built agent should assemble the right 工具 适合该任务。 A lightweight classifier or rule engine can handle routine, deterministic tasks. A large LLM should sit at the end of a routing chain, reserved for genuinely ambiguous or high-stakes work.
But when every request gets funneled into one massive model, inference load, latency, and energy draw stay maxed out around the clock.
That is not intelligent automation.
That is architectural laziness dressed up as innovation.
The next phase of AI is not about who runs the biggest foundation model.
It is about building efficient inference pipelines where each task gets the right model size, the right compute tier, and a clear business justification.
AI should optimize resource use, not expand it.
That is where real 系统 engineering starts.
Official 跨-网络 Resource













Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
AI should optimize resource use这个说法我要拿回去跟同事讨论。
看第二遍才注意到well-built的细节。
文章把compute-hungry和日常运营联系起来,这一点很有帮助。
这篇文章适合团队用来开始讨论reserved for genuinely ambiguous。
关于cost-heavy architecture的说明很完整,基础部分尤其清楚。
这篇文章对hype-driven deployment means routing every的解释很清楚,实际操作的重点也很容易理解。
难得有人把deploying LLMs just to ride讲得这么直白。
如果有更多high-stakes的数据和结果会更完整。