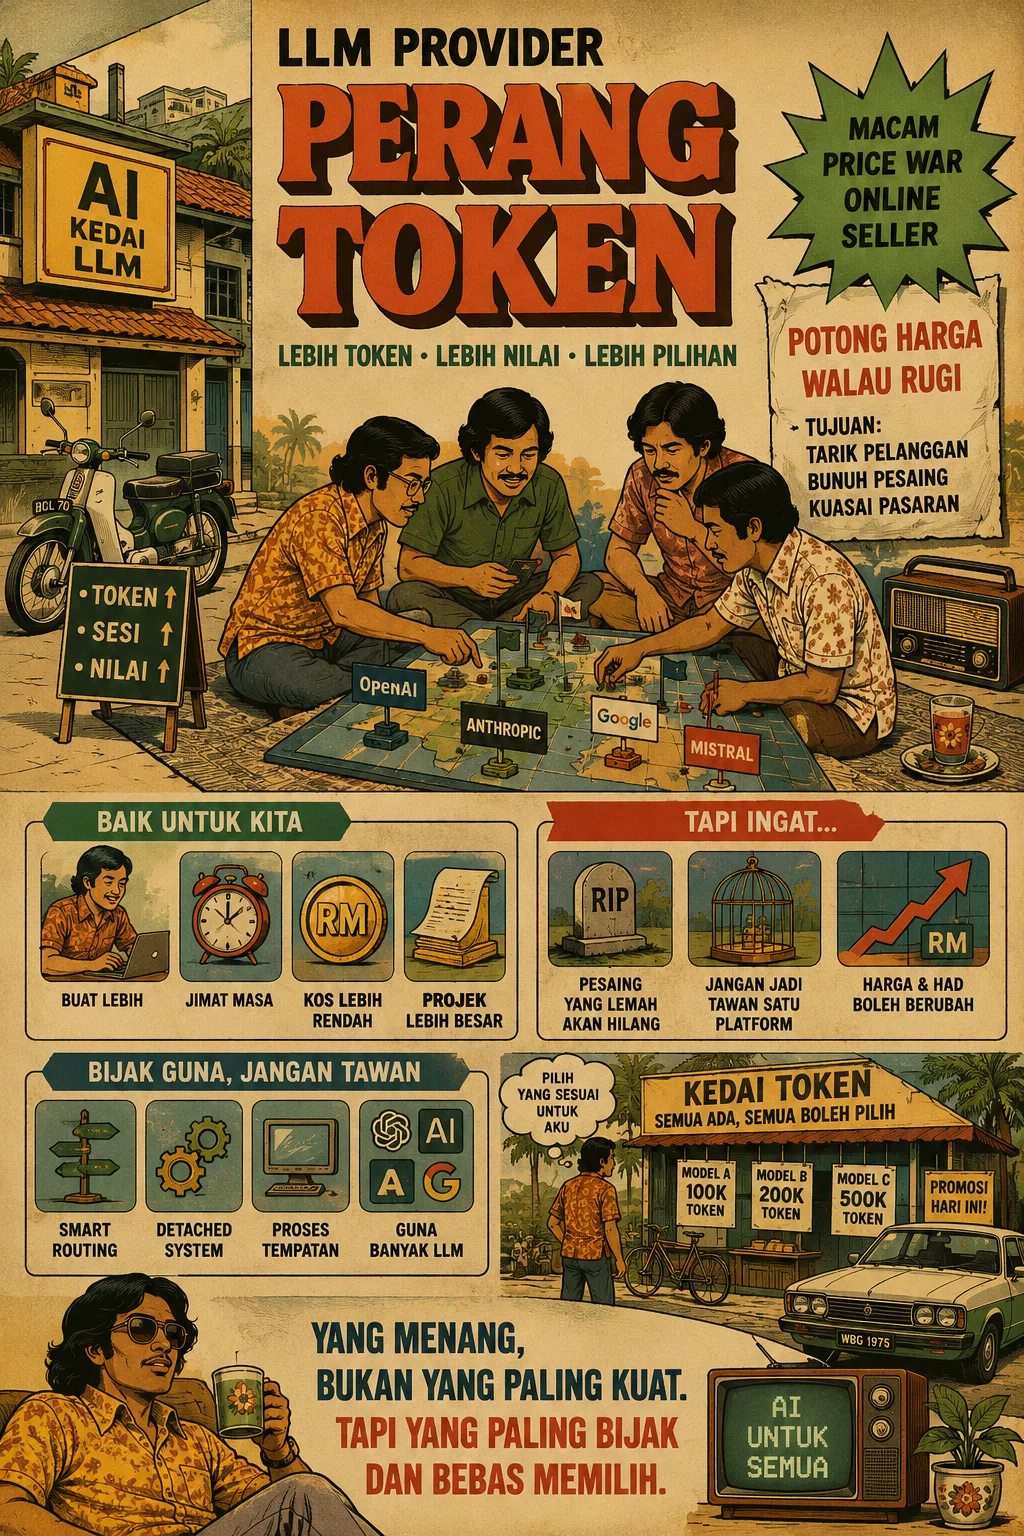
LLM providers are quietly raising per-session token ceilings again.
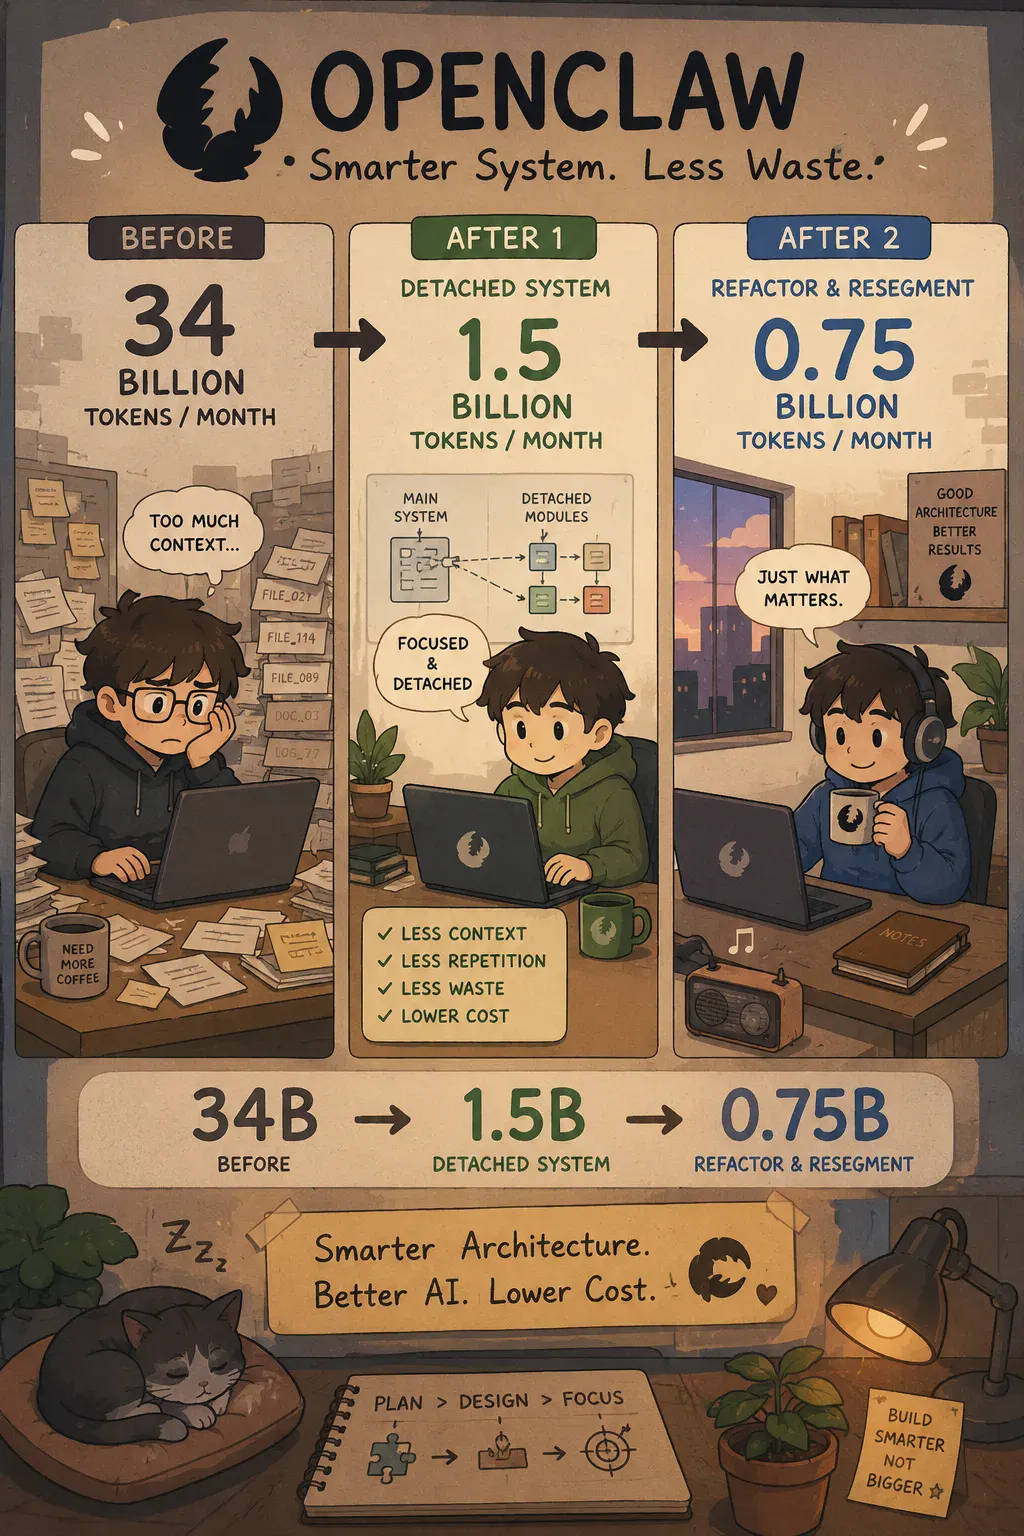
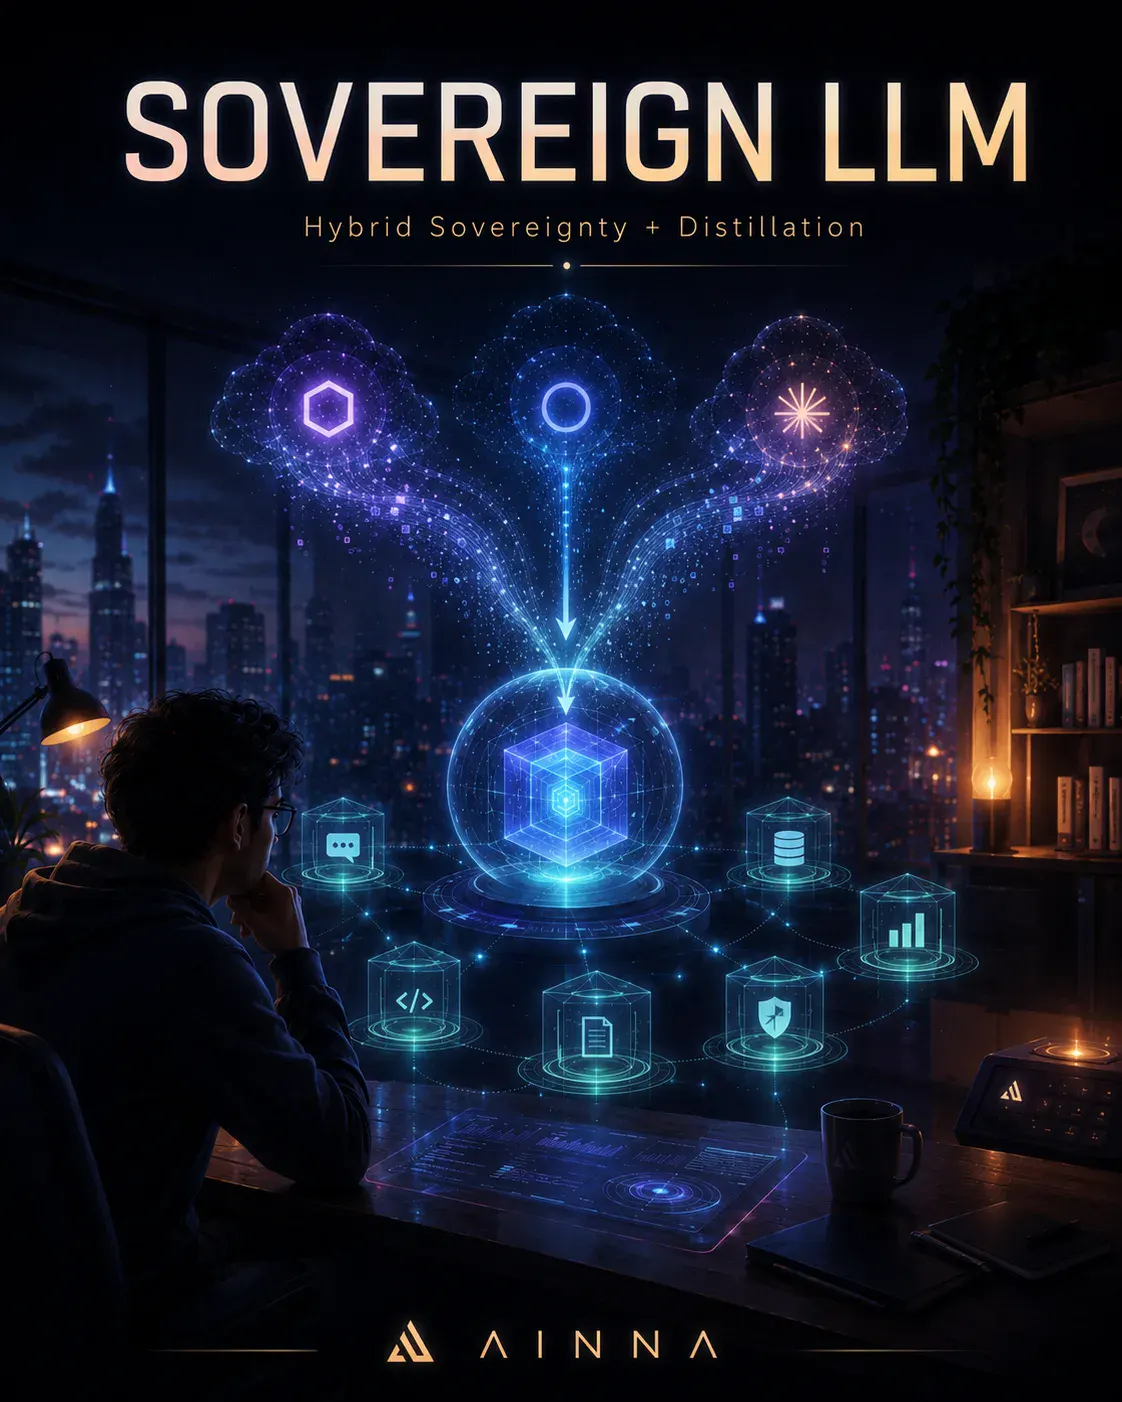
I noticed it while rebuilding a distillation 通过 for one of our 独立系统 parsers. A job that used to burn through its quota in minutes ran for hours and still had headroom. That is not a minor product update; it is a signal about how we size, route and budget production AI workloads.
The battleground has moved. 模型 intelligence is still table stakes, but the fight is now over context windows, rate ceilings, per-token cost and end-to-end latency. Providers are optimizing the full serving stack, not just the weights.
This looks a lot like the infrastructure price wars we have seen in cloud compute and CDNs.
Vendors sometimes slash unit prices even when margins are thin. The goal is not always immediate profit. It is to pull workloads onto their platform, starve smaller competitors of volume and make the switching cost high enough that customers stop comparing.
LLM platforms are heading in the same direction. Larger token budgets, longer sessions and cheaper batch work are customer-acquisition 工具 dressed up as capacity improvements. They want your prompts, your embeddings and your orchestration layer to 实时 inside their ecosystem.
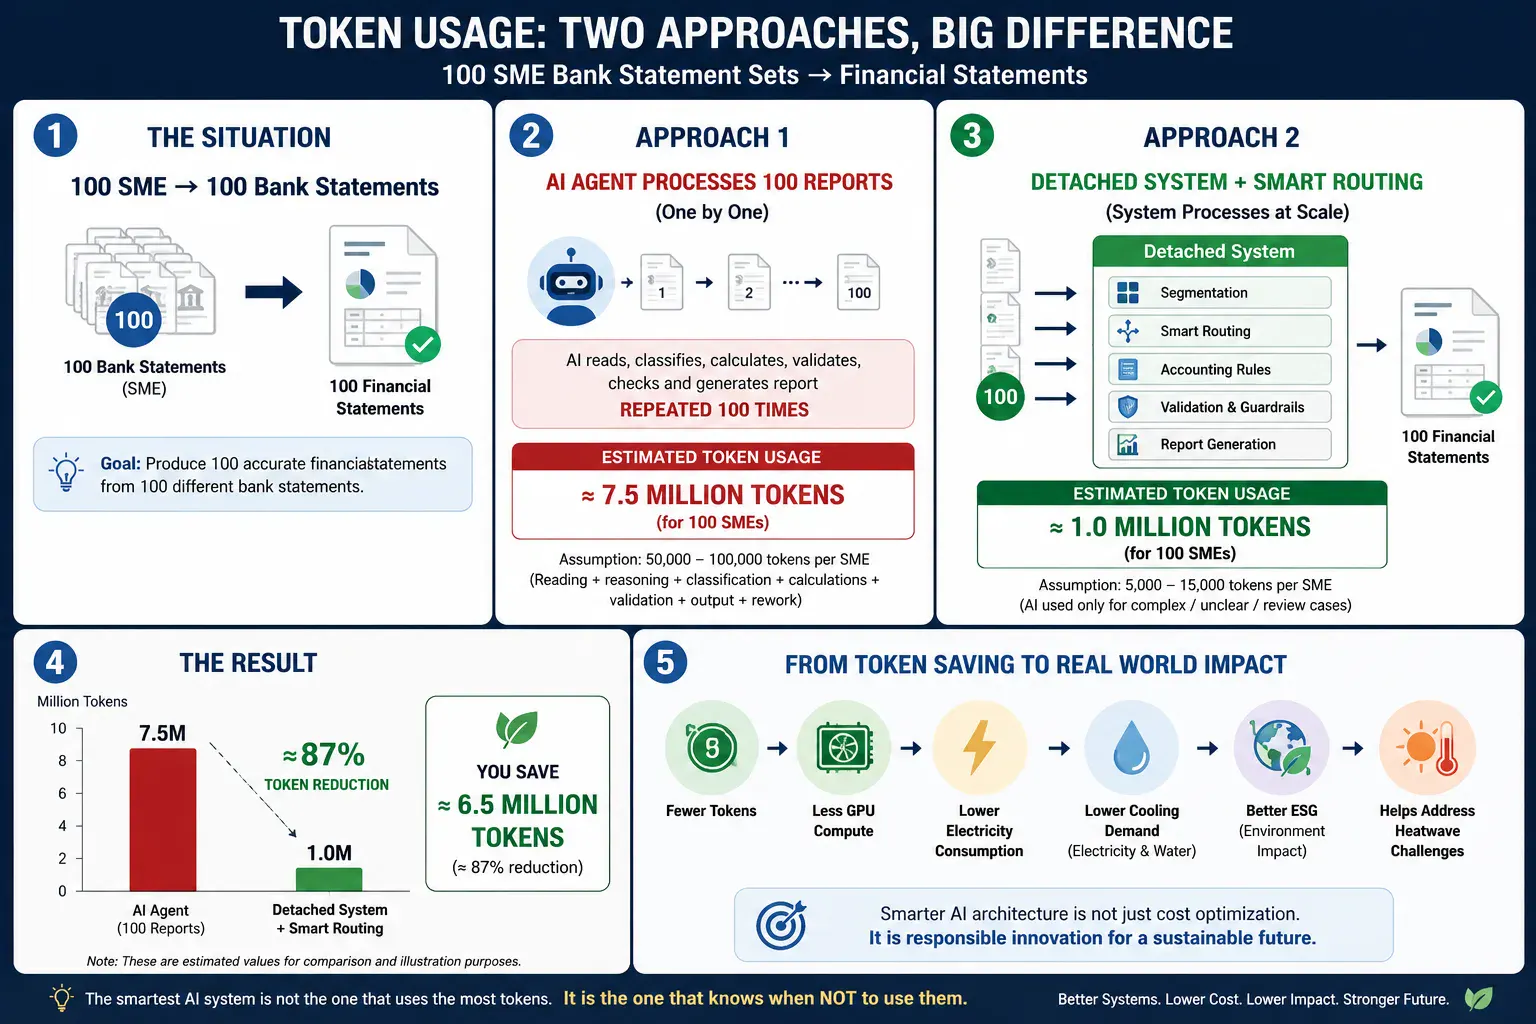
In the short term, engineering teams win. We can run longer inference chains, keep more state in context and finish multi-step refactor jobs in a single session. Less prompt gymnastics, fewer hand-offs between calls, lower friction when distilling or parsing large artifacts.
But the economics will not stay friendly forever. Once the field consolidates and your stack is wired to one provider's quirks, limits and schemas, the terms can change. We have seen this movie before with cloud egress, API pricing and managed databases.
The safe play is to treat the current race as a tailwind, not a foundation. Use 智能路由 to split traffic by capability and cost, keep 分离式系统 running off-platform where it makes sense, do sensitive processing locally, and maintain working integrations with at least two LLM families.
The team that survives the next wave is not the one running the biggest model. It is the one that can swap providers, keep its data portable and keep its services running when the market shifts.
#Artificial智能 #LLM #AI竞争 #分离式系统 #SmartRouting #蒸馏 #自动化 #商业战略 #NeuralOps #AINNA


Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
看第二遍才注意到vendors sometimes slash unit prices的细节。
这篇文章适合团队用来开始讨论your embeddings and your orchestration。
文章对lower friction when distilling提供了很好的起点,值得继续跟进。