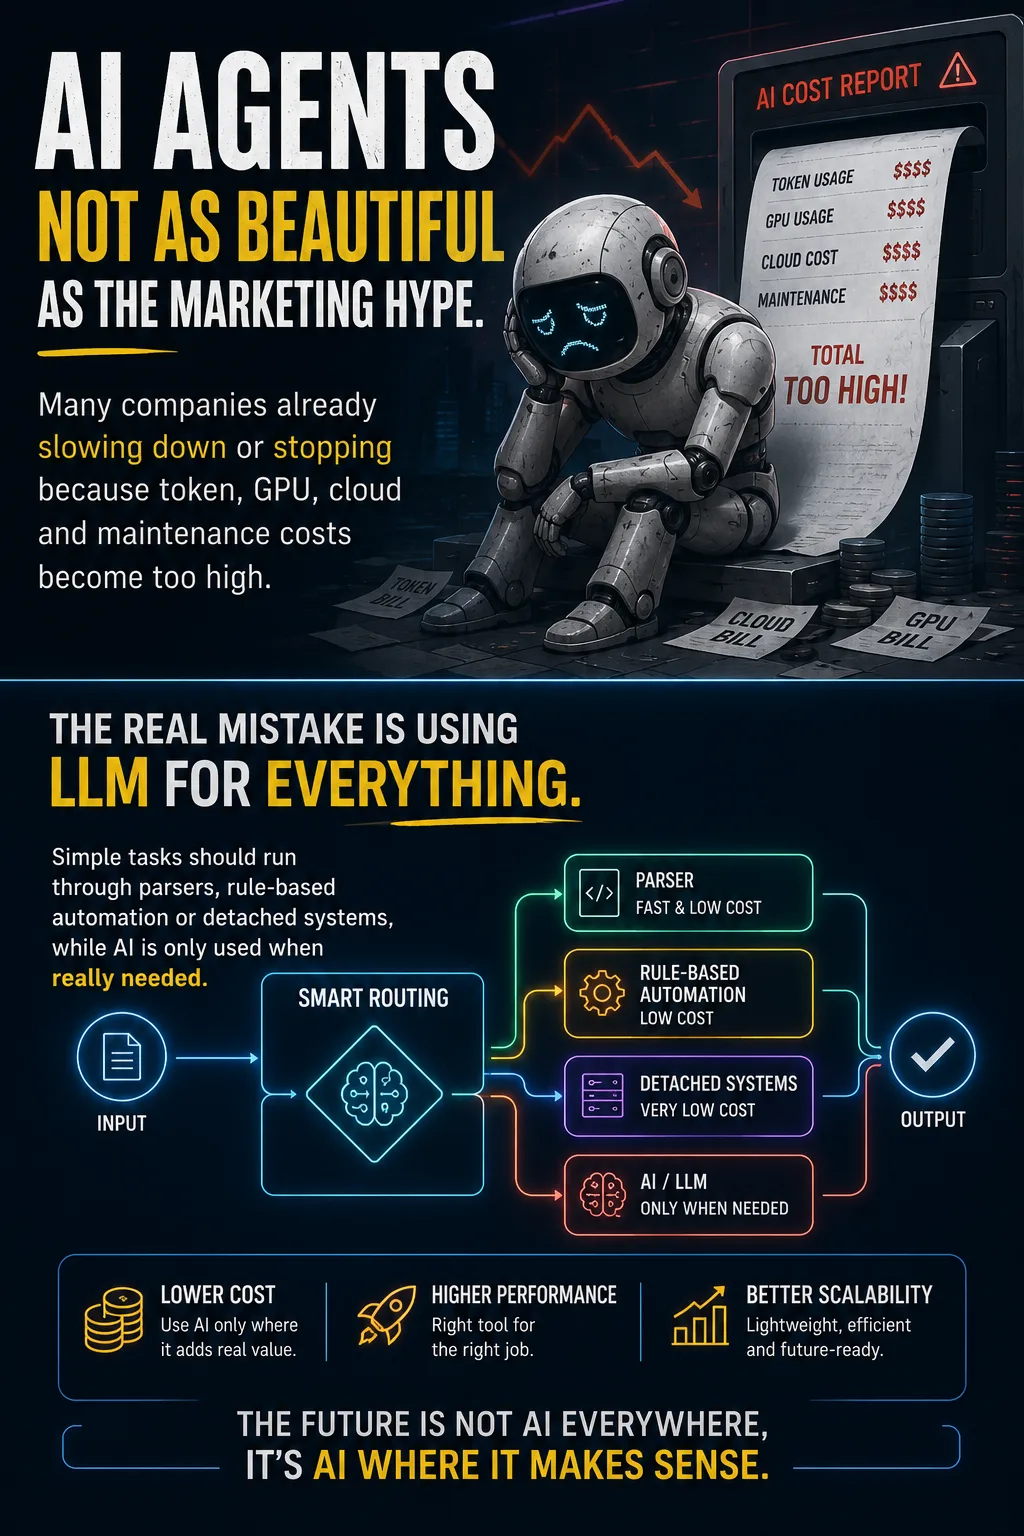
代理 deployments don't scale on marketing hype alone. In the field, we're seeing builds slow down or get shelved because token burn, GPU quotas, cloud egress and operational debt stack up faster than the value they return.
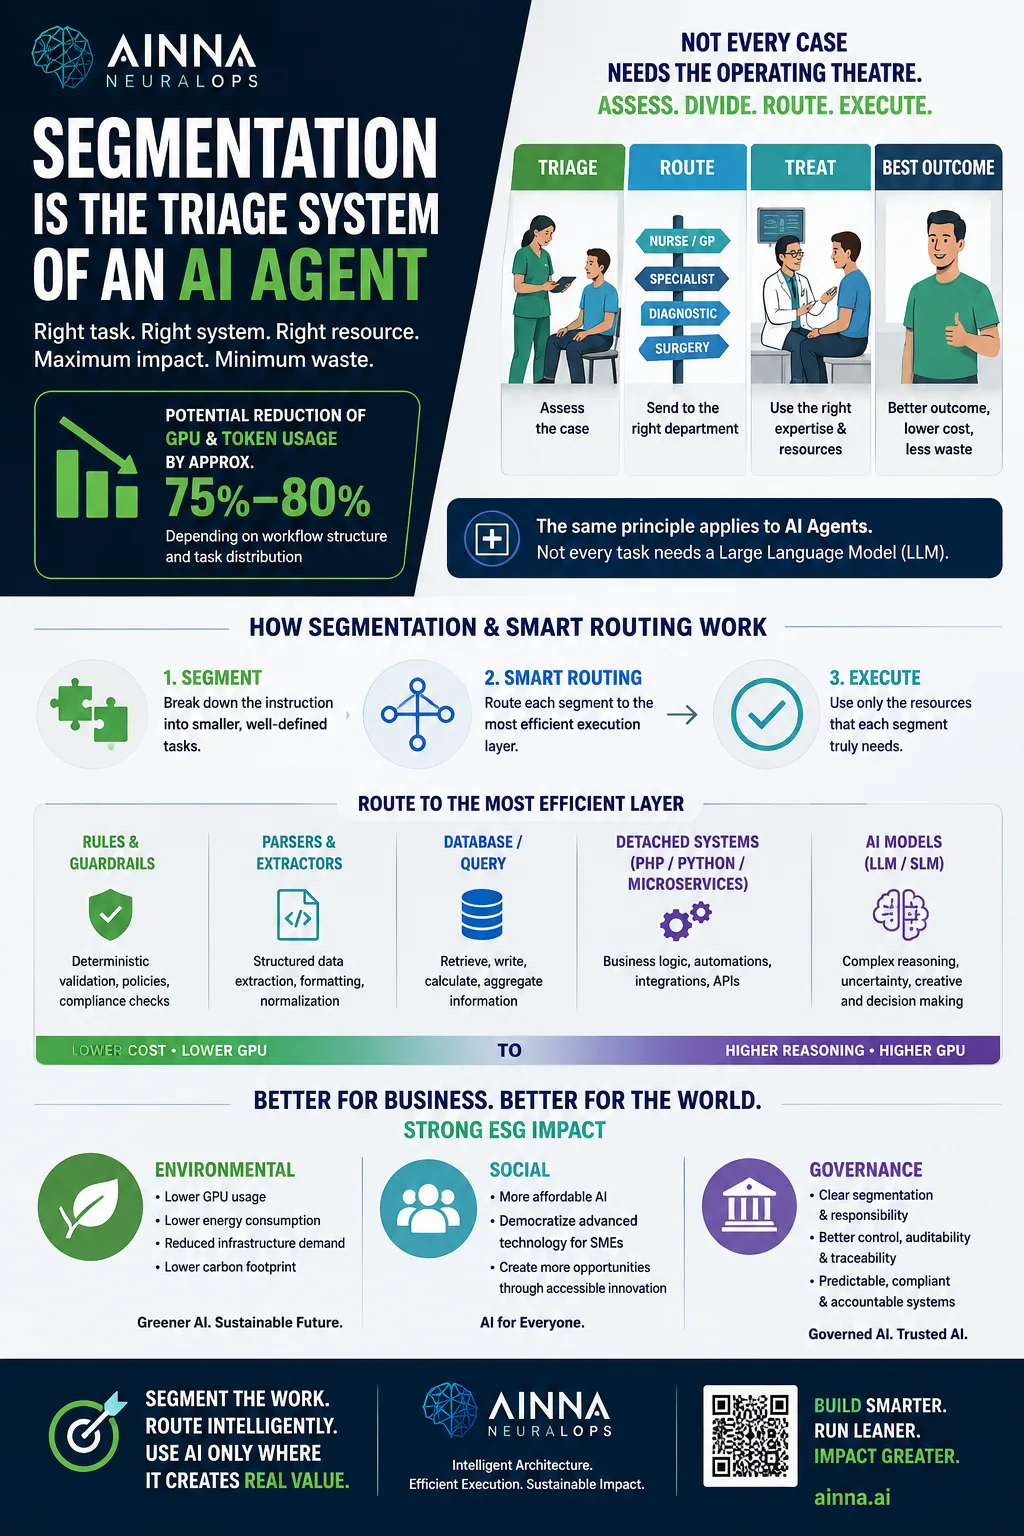
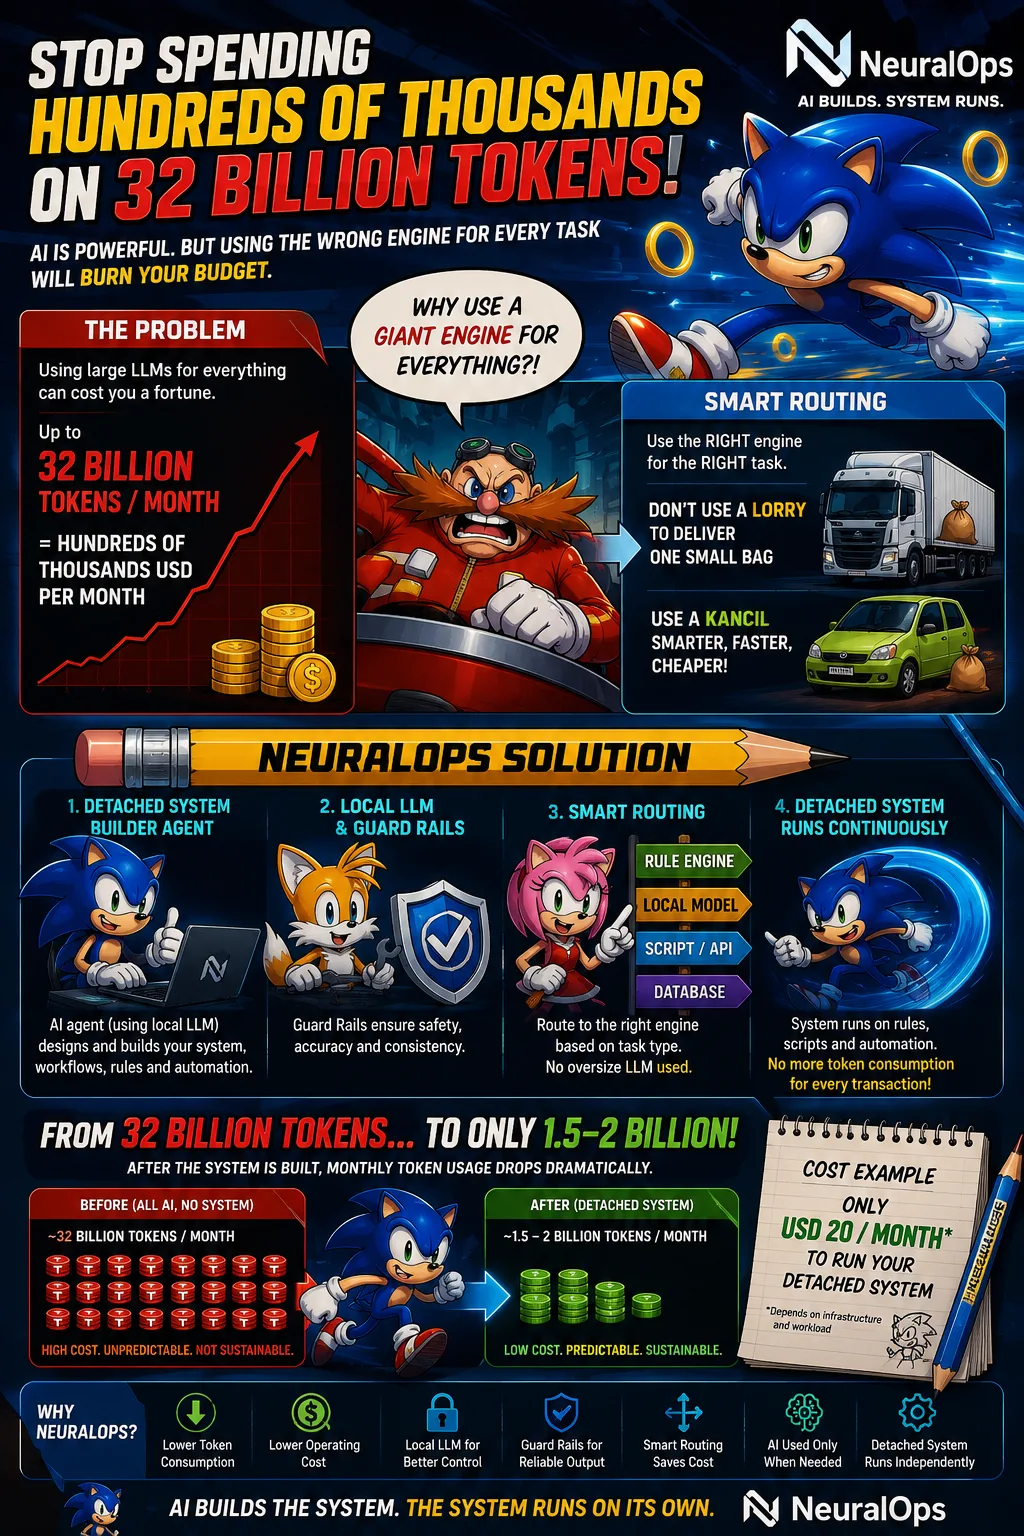
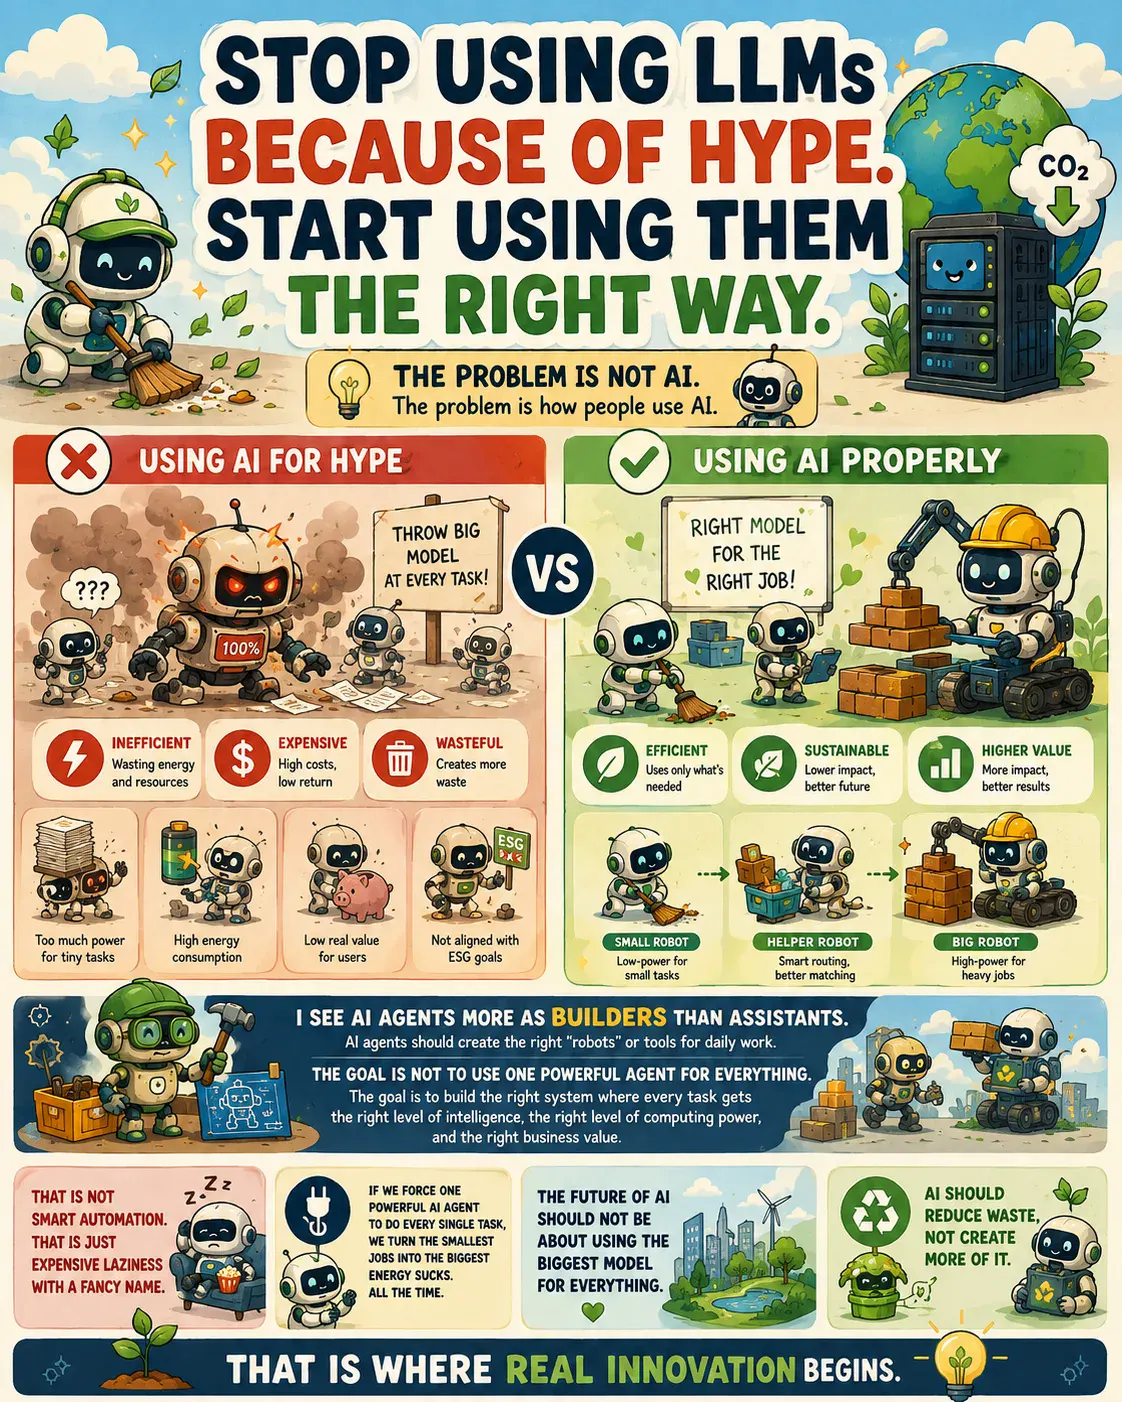
The real architecture mistake is pushing every task through an LLM. 可预测 work should flow through parsers, rule engines, event-driven services and edge-classifiers, while LLM calls are gated behind clear need and fallback logic.
Official 跨-网络 Resource


Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
我会把event-driven这一段分享给需要了解技术的同事。
收藏了,主要是为了edge-classifiers。
视觉和结构让we're seeing builds slow down的概念更容易掌握。
代理 deployments don't scale这个说法我要拿回去跟同事讨论。
这篇文章对可预测 work should flow through的解释很清楚,实际操作的重点也很容易理解。
关于可预测 work should flow through的说明很完整,基础部分尤其清楚。
难得有人把we're seeing builds slow down讲得这么直白。
关于可预测 work should flow through的例子很实用,适合团队继续讨论。