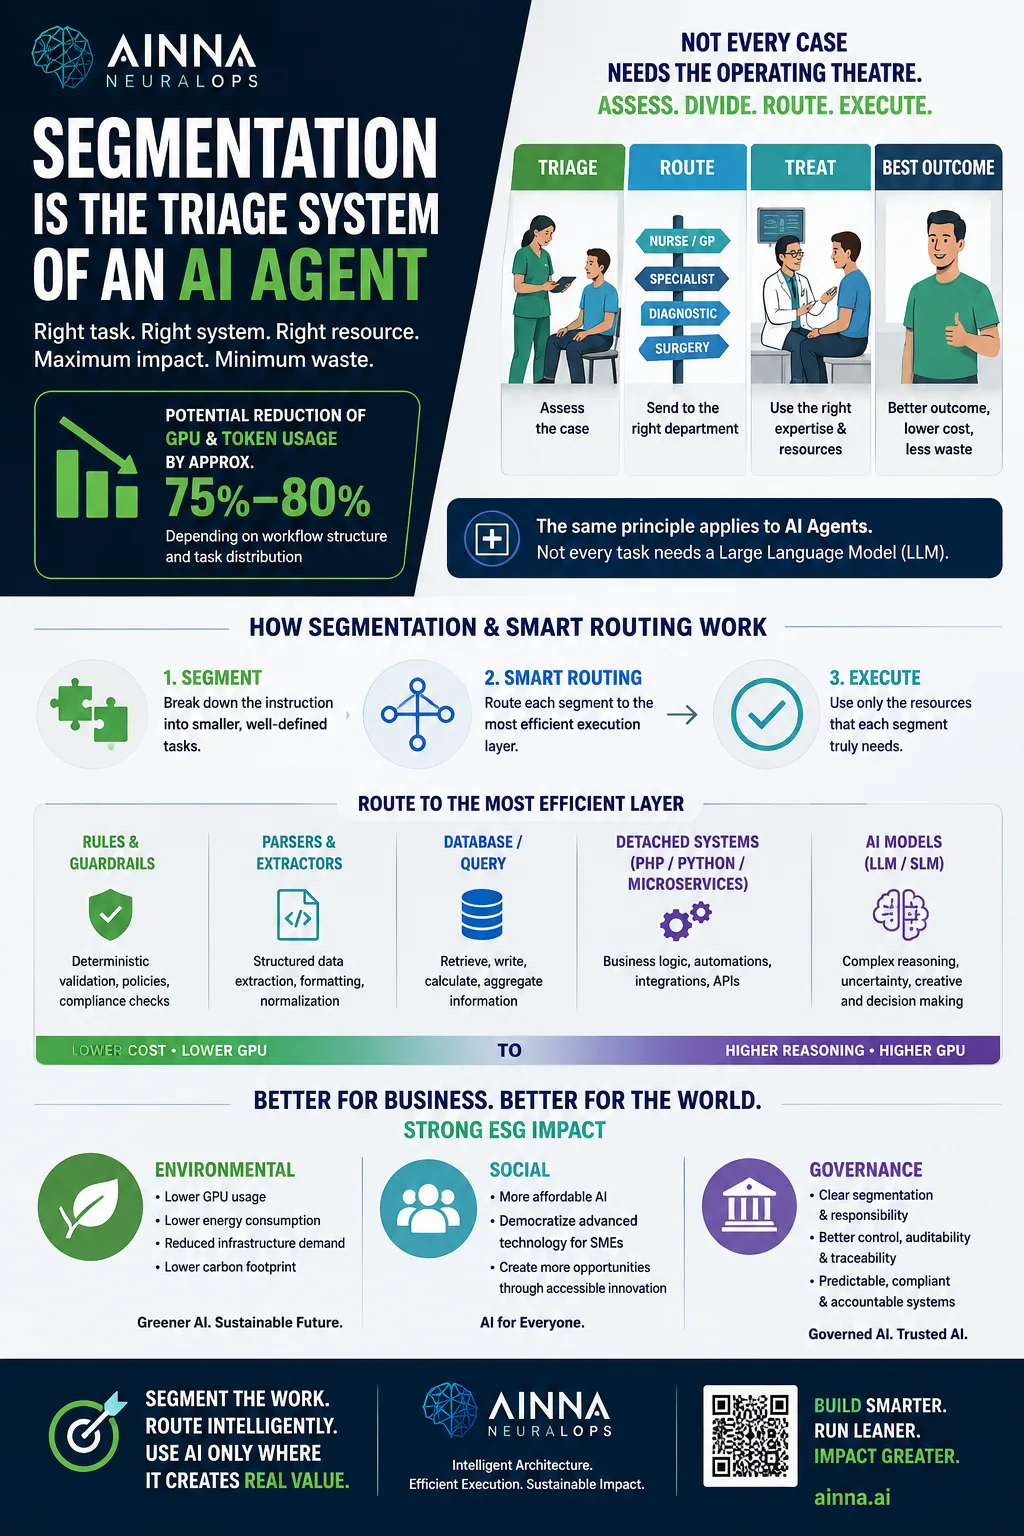
Every hospital has a triage desk for a reason. Sending every patient straight to the operating theatre would technically work, but it would be expensive, slow, and wasteful. The same logic applies to AI pipelines: not every request needs the full reasoning stack.
At AINNA, we 设计 NeuralOps around three operational principles: 分段, 智能路由, and 分离式系统.
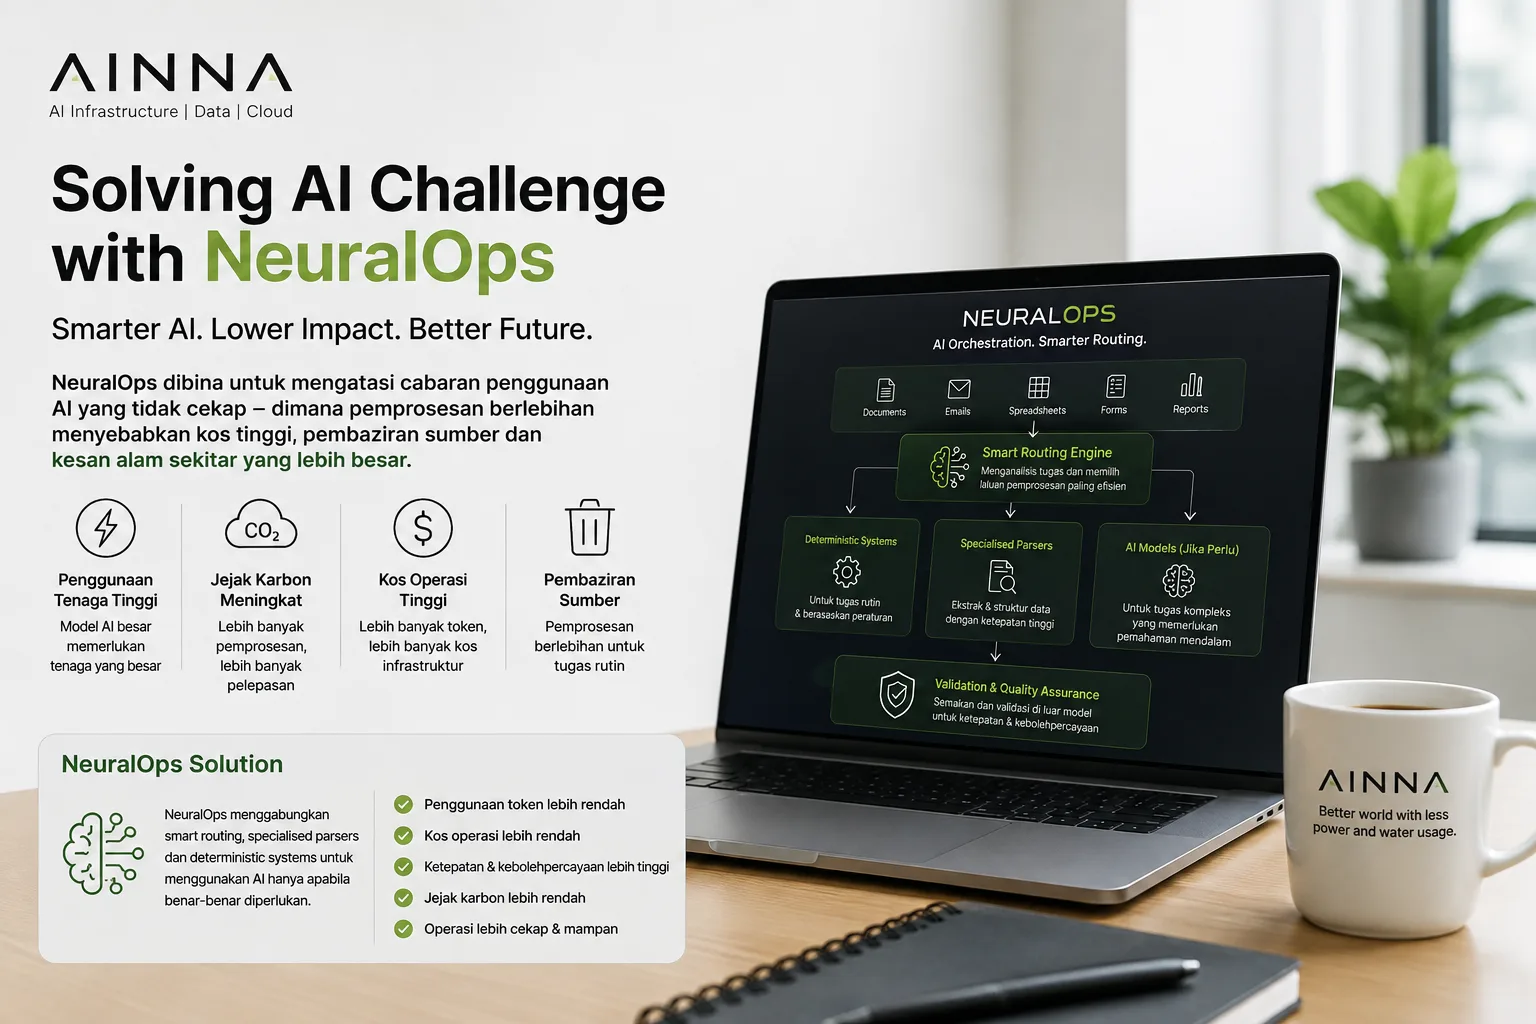
时间 an instruction hits the orchestrator, it is broken into discrete tasks and routed to the cheapest execution layer that can still guarantee correctness:
确定性 work-lookups, parsing, validation, CRUD, simple calculations-runs through rules engines, databases, or lightweight PHP/Python microservices.
Only tasks that genuinely need contextual reasoning, synthesis, or ambiguity resolution are handed to the AI model.
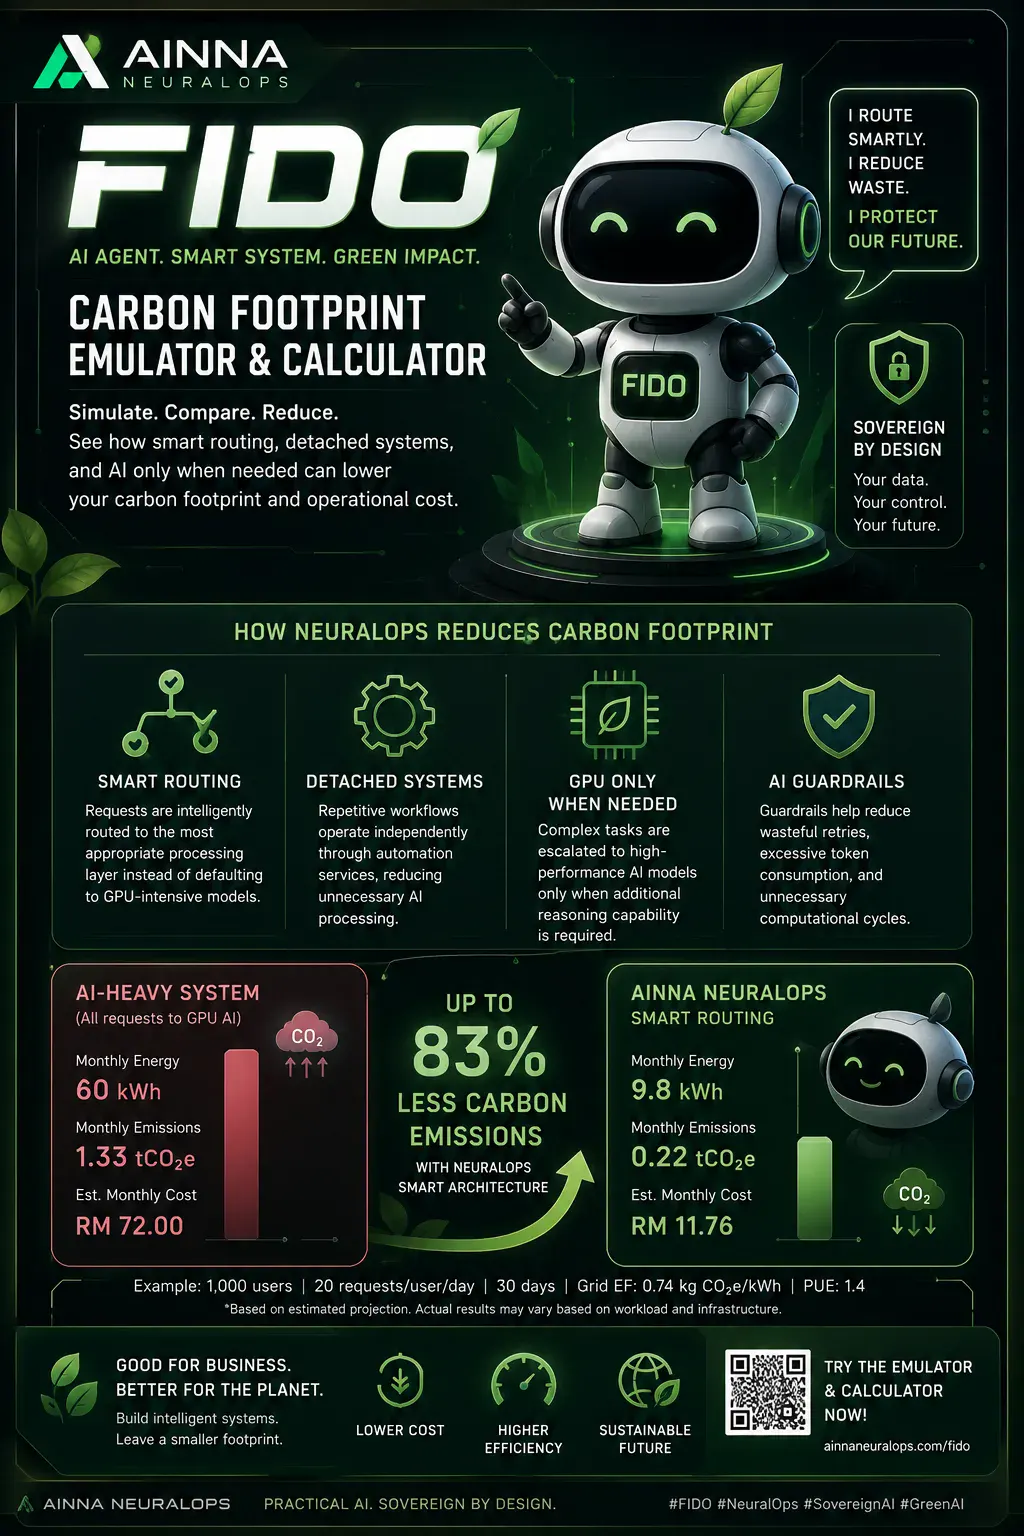
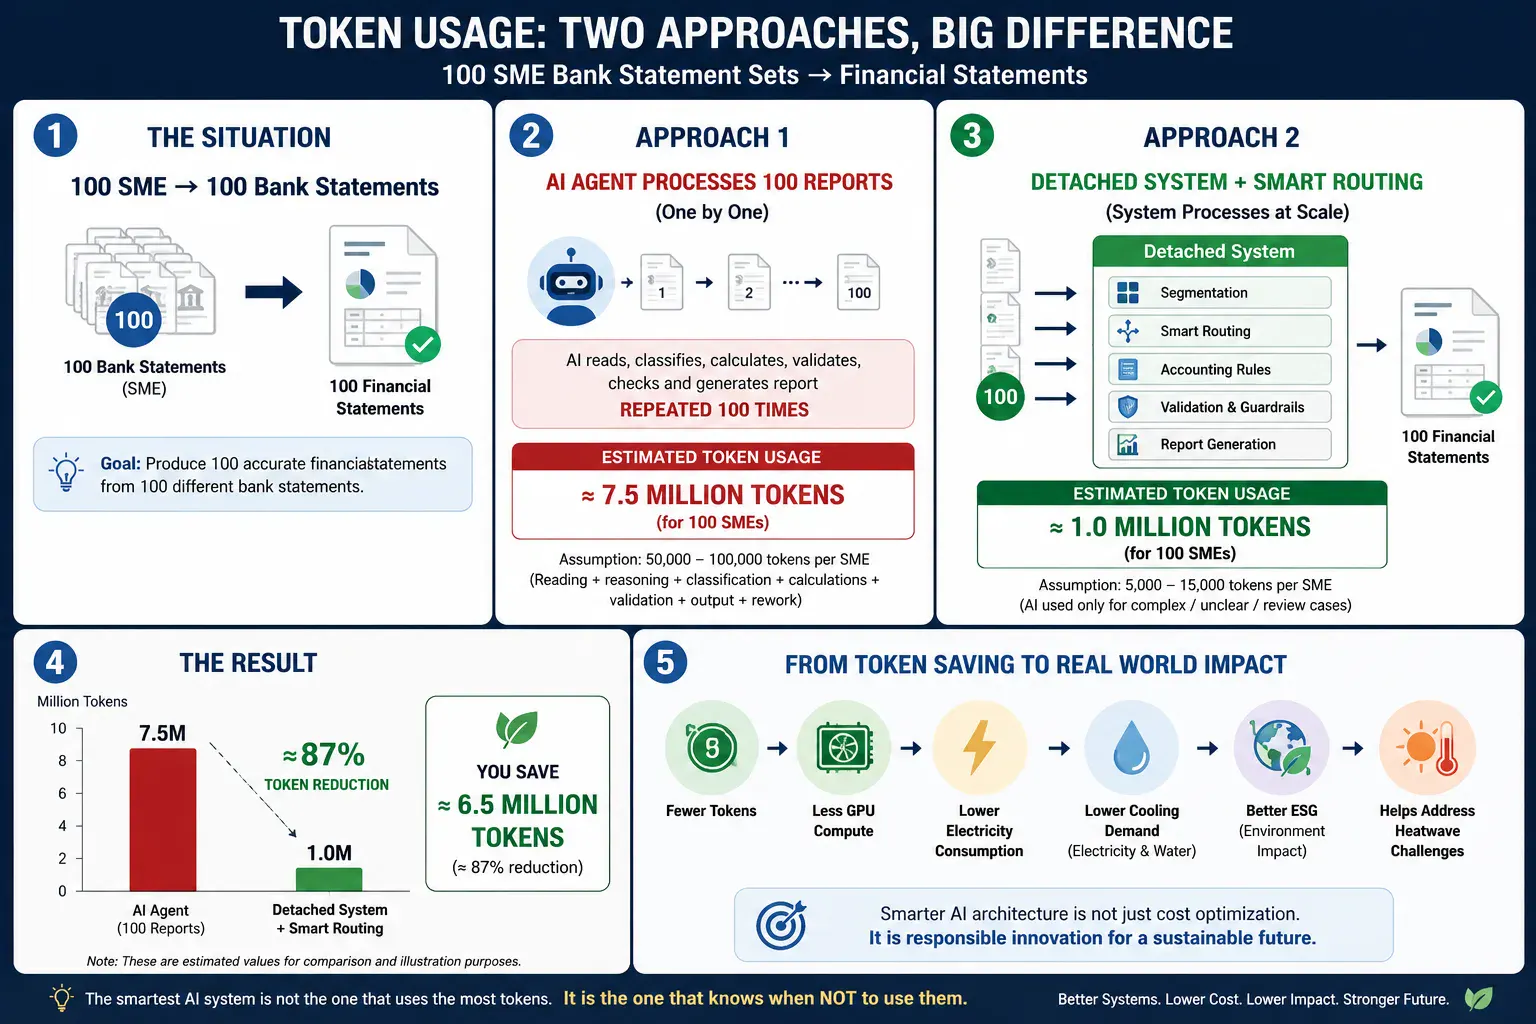
On real production workloads, that routing decision alone can cut unnecessary GPU time and token spend by 75% to 80%, depending on the workflow mix.
The ESG impact is not a marketing add-on; it is a 系统-level consequence:
环境: Less wasted compute means lower energy draw and a smaller carbon footprint.
社会: Cheaper inference makes practical AI accessible to 中小企业, not only to 企业s with large GPU budgets.
治理: 确定性 paths are easier to audit, version, and keep predictable under compliance scrutiny.
分段 the work. 路线 it to the right execution layer. Use AI only where it earns its keep.
#AINNANeuralOps #SmartRouting #分离式系统 #可持续AI #ESG #GreenAI













Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. 电子邮件 diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
simple calculations-runs through rules engines这个说法我要拿回去跟同事讨论。
文章对时间 an instruction hits提供了很好的起点,值得继续跟进。
看第二遍才注意到depending on the workflow mix的细节。
这篇内容让我更容易理解为什么the workflow m 75%值得关注。